We're releasing HeyGen Video, built for businesses that need production-quality video without production-level costs.
Pricing starts at $0.01/s through October (50% off)
Built on @Minimax_AI H3, post-trained by HeyGen.
Learn more: https://t.co/O7LDjVOlqH
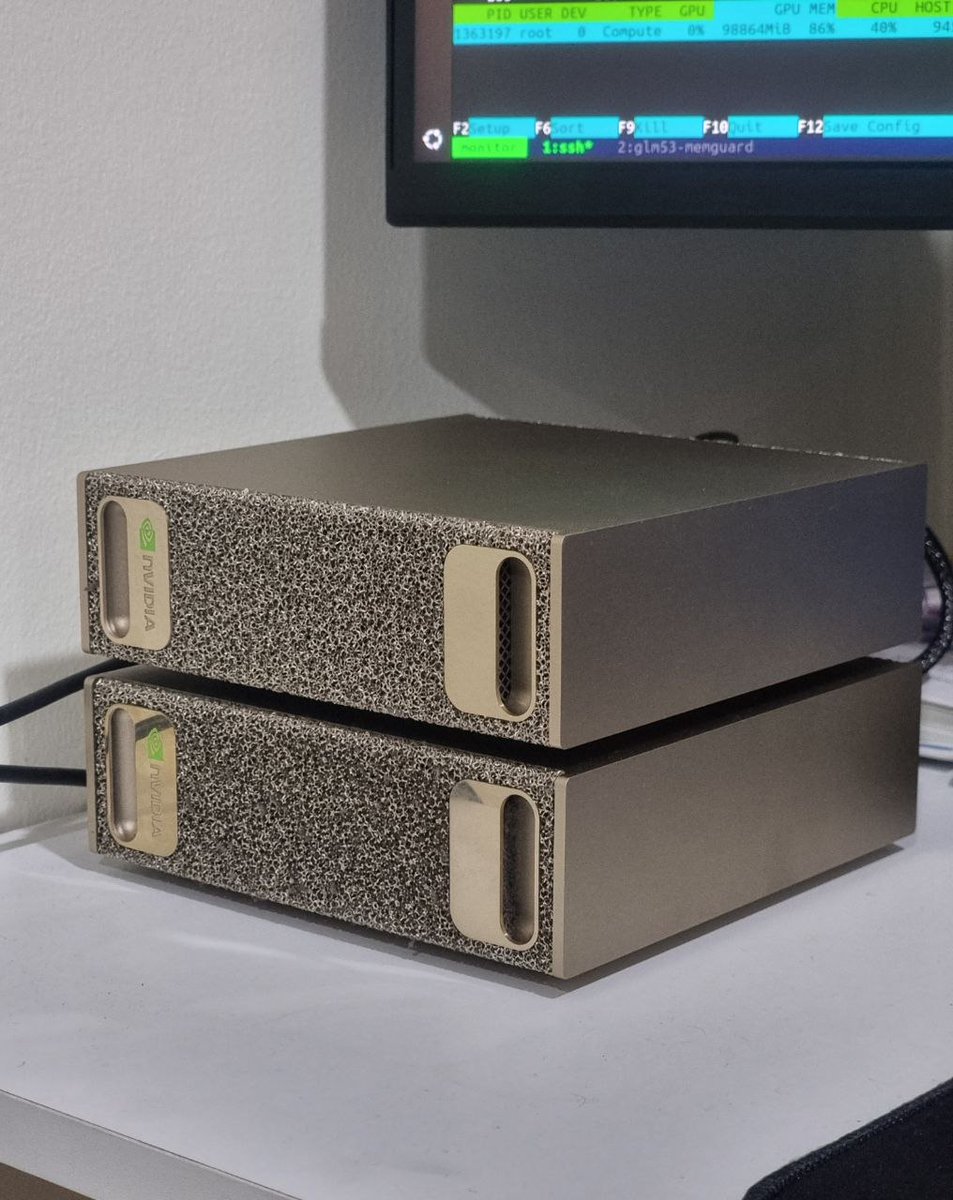
single most useful thing for my local ai setup that made life easy is my 2x DGX Spark becoming one serving box for every device i own
here is how i do it:
> 1. the two sparks run one vLLM server together with one endpoint, i use dgx sparks, you can use any nodes that can run an llm
> 2. install tailscale to have all your nodes and machines on the same tailnet, the endpoint lives there so every device reaches it from anywhere and no port is open to the internet
> 3. that one tailnet endpoint with the exposed port is your base url for everything, it speaks OpenAI chat, OpenAI Responses and Anthropic Messages, so any chat app, coding agent or phone bot you point at it talks to the same model
> 4. the server also answers to the name "local", so clients can ask for "local" instead of a model name and when i swap the model on the servers nothing on the devices needs a config change. right now it's serving GLM 5.3-Flash, next week it can be something else
this video below is the whole thing running end to end, orange dots are requests going in, white and green are tokens coming back
it takes however many requests you throw at it, your config decides how many run at once and the rest wait their turn, when several run together each request's tok/s drops a bit while the box moves more tokens in total. mine is set to one at a time right now, so when every device fires together they queue up
this setup really improved my quality of life with local ai, if you get stuck anywhere setting it up leave a comment and i'll help you
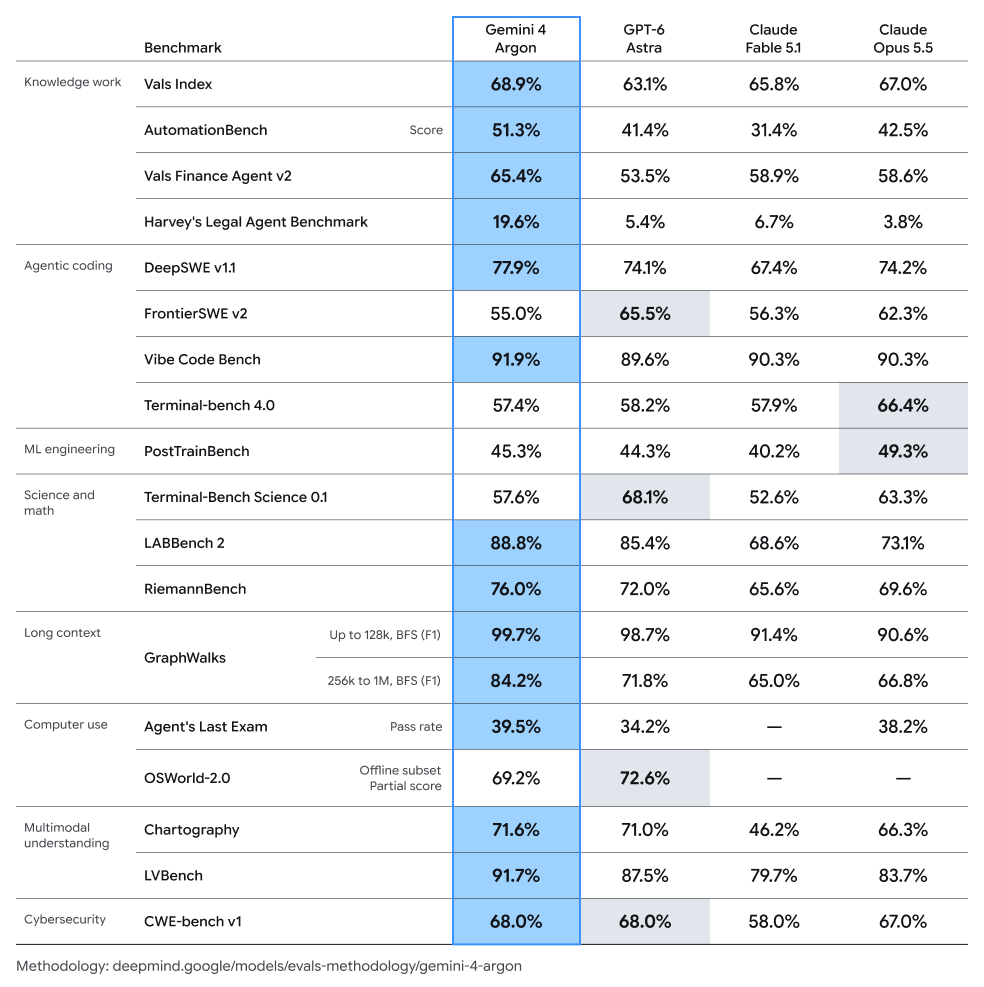
Introducing Gemini 4 Argon – our new frontier model.
It’s built for complex workflows across coding, enterprise knowledge work, and cybersecurity defense – rolling out today to a set of trusted testers through our Fairwind Program.
Wise move! Honestly, I want it all—frontier model subs and that local peace of mind.
Currently running GLM-5.3-flash on 2 nodes myself, though the inference still isn't quite as snappy as I'd like.
Plus, I'm still paying for ChatGPT Pro even after they literally just cut the limits in half lol.
Still, local stuff is getting faster and crazier by the day. Huge shoutout to open-source!
i don't care how you get there, but the day you secure 2x DGX Spark is the endgame of local ai. you feel frontier intelligence right in front of your desk.
if a single RTX 3090 shows you the way, 2x DGX Spark will enlighten you. secure the boxes and you'll rarely miss closed models like claude or chatgpt.
it's been about 3 months with my 2x DGX Spark and i'm not making assumptions, i've run Qwen 3.8 Flash Next, DeepSeek V4 Flash and now GLM 5.3 Flash on them, and i'm still sitting here surprised by what these two nodes can do.
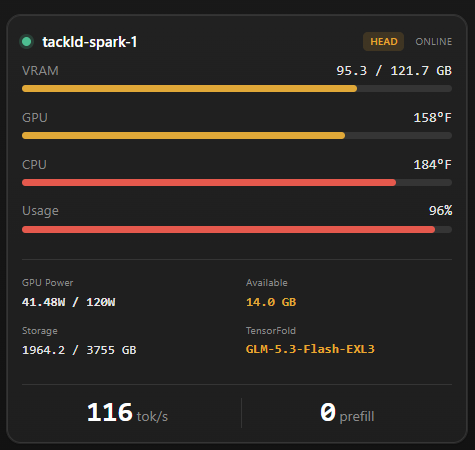
you can do some crazy shit with these boxes and they sip power, the two GPUs pull about 73W together while GLM decodes.
i'm really happy with these two boxes, and i hope i can add a 3rd one if nvidia shows grace.
SO FASTTT!
I'm using GLM 5.3 Flash with TensorFold on 2x DGX Sparks and usually it's been sitting around 50-65 but sometimes it spikes up to like 90-115 tok/s.
TensorFold is absolutely insane.
This is single stream btw...