What's better than 384 MB of SRAM? How about doubling it? 🔥
Google TPU 8i is a leading inference platform (see our 2026 I/O demo). With TPU 8i Max, we are taking it to the next level.
👉 Check out the next level at 5pm UK / 9am PST: https://t.co/qYRJ7YLn8K
Thrilled to share a big milestone from our AI & Infrastructure team at @Google.
Today we’re expanding our 8th generation TPU portfolio with:
• TPU 8i Max: Built for massive context windows and the highest compute density per rack
• TPU 8tx: Purpose-built for secure, confidential inference
This marks the first time we’ve introduced four distinct TPU systems in a single generation, in one year.
For developers, hardware is only as good as the software stack. And we want you to be able to build with TPUs as easily and efficiently as we do at Google. You can now:
↳ Run native PyTorch & Hugging Face models via TorchTPU (zero code rewrites)
↳ Cut KV transfer latency >90% with open-source TPU Sync
↳ Eliminate idle compute waste with Agent Compute Engine
Read more about our newest TPUs on our blog: https://t.co/8eaFhq3jhi
I look forward to connecting with builders, researchers, engineers and organizations pushing the boundaries of AI and computing!
The @GoogleDeepMind Science team is sharing two key cryptographic advances today uncovering weaknesses in legacy 1024-bit RSA schemes.
Working with leading cryptanalysis experts, our team showed how AI agents could make two significant cryptographic advances in just weeks, uncovering results which can bypass older digital signature protections and factor legacy 1024-bit RSA keys in bulk.
While these results do not affect the security of modern encryption schemes such as RSA 2048, these results show why we must not assume the mathematical "hardness" of cryptographic schemes which we have relied upon in the past. It also shows how AI can help defenders improve security standards well ahead of future threats.
I have written in more detail about our results, and why they are important for the future of security, in a longer essay which you can read here:
https://t.co/K1TxNdqfQv
This could not happen in the UK because of non-compete rules and long gardening leave. One of the reasons the Bay Area is thriving is this energy and movement.
Tinkering on tax is not going to create the next OpenAI or Anthropic.
Some news: I’m joining OpenAI to lead product management for Core Products!
I have a lot of respect for OpenAI for showing the world that scaling works, for bringing AI to over a billion people, and for believing great products are core to the mission.
I’m excited to work with @thsottiaux, an incredible PM team, and everyone across OpenAI. Together, we’ll build agents that have your back and your team’s, and keep you in control, so you get more time for the people and work you love.
Lots to learn, and lots to build. Please keep your feedback coming!
Election Tuesday is just two days away. For those eligible to vote in the U.S., please make time to go to the polls to vote (or mail in your ballot if you haven't already). Voting is a great privilege of living in a democracy and how we all make our collective voices heard. 🗳️
Like a lot of people, X-Men and Star Trek introduced me to Sir Patrick Stewart's many performances. However, it is his work on human rights that sets him apart.
RIP Sir Patrick. 🇬🇧🇪🇺
This seems like a great time to reshare my favourite Sir Patrick Stewart performance, ‘What has the ECHR ever done for us?’ It’s just perfect in every possible way … including the ending 😂😂😂 RIP.
🎥 The Guardian
The Gemini Large Scale Pretrain team is hiring a Research Engineer in London or MTV! The team works across the pretrain stack: research codebases, distributed training infra, data pipelines, tooling for training dynamics analysis, and most importantly using Gemini to accelerate our work! 🚀
If you're an engineer who has a strong "whatever it takes" attitude and is not afraid of spending tokens, apply here with some showcase work: https://t.co/Xlw9f4NYlP
No particular qualifications needed, and we welcome early career applicants. Join if you want me to bug you with refactors to enable [new AGI compute multiplier]! 👀
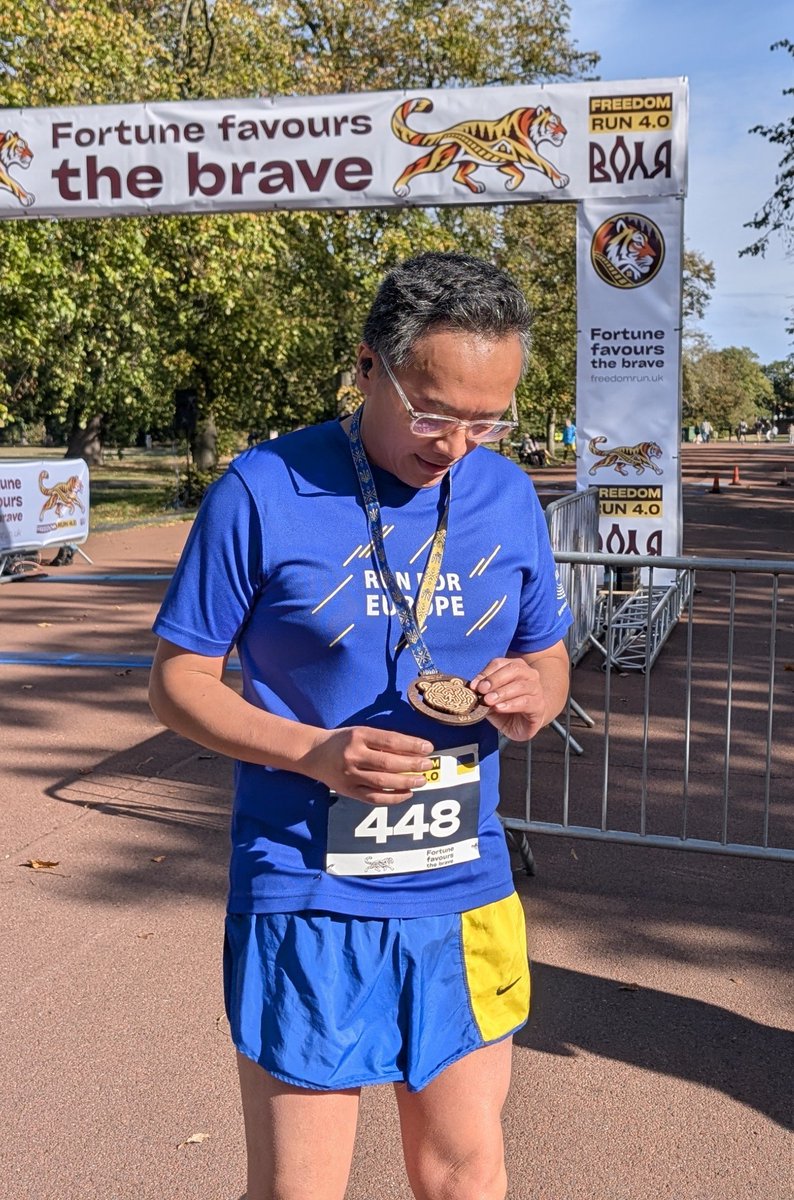
🇺🇦 Doing what we can to help Ukraine: raise funds, run the Freedom Run 10k...
👉(if you can) vote in the American mid-term election 🇺🇸🗳️
If Ukraine falls, it will be British, European and American soldiers next. Putin won't stop.
Donate here: https://t.co/TxEsqXmJzj
Since the American President announced the energy ceasefire a week ago, Russia has deliberately attacked Ukraine’s energy and oil and gas sectors 76 times. Last night alone, there were strikes on substations in the Vinnytsia, Zhytomyr, Khmelnytskyi, and Odesa regions. Tens of thousands of families remain without power. Energy workers and repair crews are working virtually around the clock to restore electricity supply. Overnight, the Russians also struck residential buildings in our regions. As of now, 12 people have been reported injured, including two children. Two people have been killed. My condolences to their families and loved ones. This morning, there was a strike on an agricultural enterprise in Volyn. All necessary services are working at the site.
In total, over this past week, the Russians have attacked Ukraine with almost 2,700 attack drones, 1,700 aerial bombs, and 66 missiles, most of them ballistic. The main targets of these strikes are energy facilities – the Russians are trying to cause a blackout. And America should see that Russia is not taking any reciprocal steps in response to sanctions relief or agreements. On the contrary, they take every signal of an opportunity to make money as proof that their bet on war is paying off and they can keep fighting. It is because of this position of Russia’s that the war continues, not because Ukraine is rightfully defending itself. It is Russia that must face pressure for peace to have a chance. Thank you to everyone who understands this and helps.
A self-driving Tesla crashed into a California highway patrol vehicle, seriously injuring two officers inside.
According to the officers, the driver said he was asleep at the time and using the car’s driver-assistance technology.
We're significantly expanding access to Gemini for scientists via antigravity - sign up now!
Top of mind question for scientists on data retention - please turn off telemetry if you'd like.
https://t.co/cQm6QPlyYk
We all need to start calling it what it is:
Trump indeed wants the war to end quickly. He’s just choosing to end it with a Russian victory.
Read our Editorial: https://t.co/zEU79FxBIm
@AIQuanting This topic is particularly close to my heart because we spend a whole quarter last year working shoulder to shoulder with our TPU team on this. I really can't thank the TPU team enough!!
We looked at every bit of latency, how to shard models etc etc: https://t.co/jy2quoPfoU
TPU 8i is co-designed with our Gemini research team to support low latency inference. Among the attributes that support this are large amounts of on-chip SRAM, enabling more computations to be done on chip without having to go to HBM for weights or KVCache state as often.
The boardfly network topology (see image below) offers a much lower diameter network to connect all 1152 chips in an 8i pod, by fully connecting all 4 chips on the board together, fully connecting groups of 8 boards together, and then fully connecting 36 groups of 8 boards together. In addition, there is specialized Collectives Acceleration Engine (CAE) circuitry on each chip to offload various kinds of reductions and other global operations from the main computational portion of each chip, reducing on-chip latency by up to 5x.
Together, these features will offer very high throughput for large-scale models (including MoEs, which often require mapping onto many chips for inference), and will do so at very low latency. This will make agentic workloads and interactive usage really shine on the TPU 8i.
Fun fact: Google TPU already do this. Our current generation Ironwood pod is 9,216 accelerators with 1.8 PB HBM in 144 racks.
You can have multiple pods in a single cluster and then scale up from cluster -> campus -> metro -> multi-metro.😊
Some interesting conversations here at OCP with AI infra folks on if we can get to true scale up/out compute domains sooner than later if that alleviates the race to GPU/XPU density per rack.
Meaning maybe we don’t need to try and get to ~500 gpus per rack.
@AIQuanting You should check out our demo (it's real!) for our next gen TPU v8i at Google I/O with the Boardfly ICI topology: https://t.co/exym7CPIFo
Even without it, due to the large pod sizes, we've a very high aggregated memory bandwidth, Gemini is rated among the lowest latency models.