@hitmewithmusic1@RCM_Doherty In term of foundational tech basically the core pieces of internet, programming languages and even some hardware were born in Europe: www, Linux, c++, Python, PHP, Redis,Git, Bluetooth, Arm cpu architecture, GSM, Mp3
With single Intel B70 + 64gb DDR5 I'm running Qwen 3.8 FLash Next 23.3tok/s @ 8K ctx and 13 tok/s @ 80K ctx
It's the Q2_K_XL and the prefill is quite slow but hopefully there is margin for improvement
@SergiiioBS@vattybear I've a 1 B70 + 64GB DDR5 and windows
With qwen3.8-Flash-Next Q2_K_XL (so lower quality than your 4.3 bit gguf) on patched llamacpp/sycl, mmap+auto fit, q8/q8 kv and mpt off.
I get 23tok/s @ 8K ctx and 13.3 tok/s @ 80K ctx
Will try some of your tips, maybe can push it some more
@0xSero I guess that 100% vibing it's the new standard nowadays but that readme reeks of Claude slop nonsense, at least we should take our sweet time to write a human readable readme, or we are already at the point that readmes are only for clunkers?
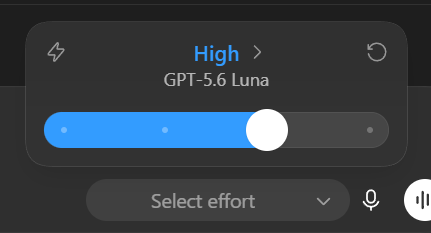
Openai model cheatsheet I made for myself as a reminder
Basically Luna/xhigh is my mainly driver 70-80% of times, Sol/high when i need good reasoning on larger context and then relegate Astra/med to complex tasks and long autnomous agent exec
For pure economics this conf wins imo
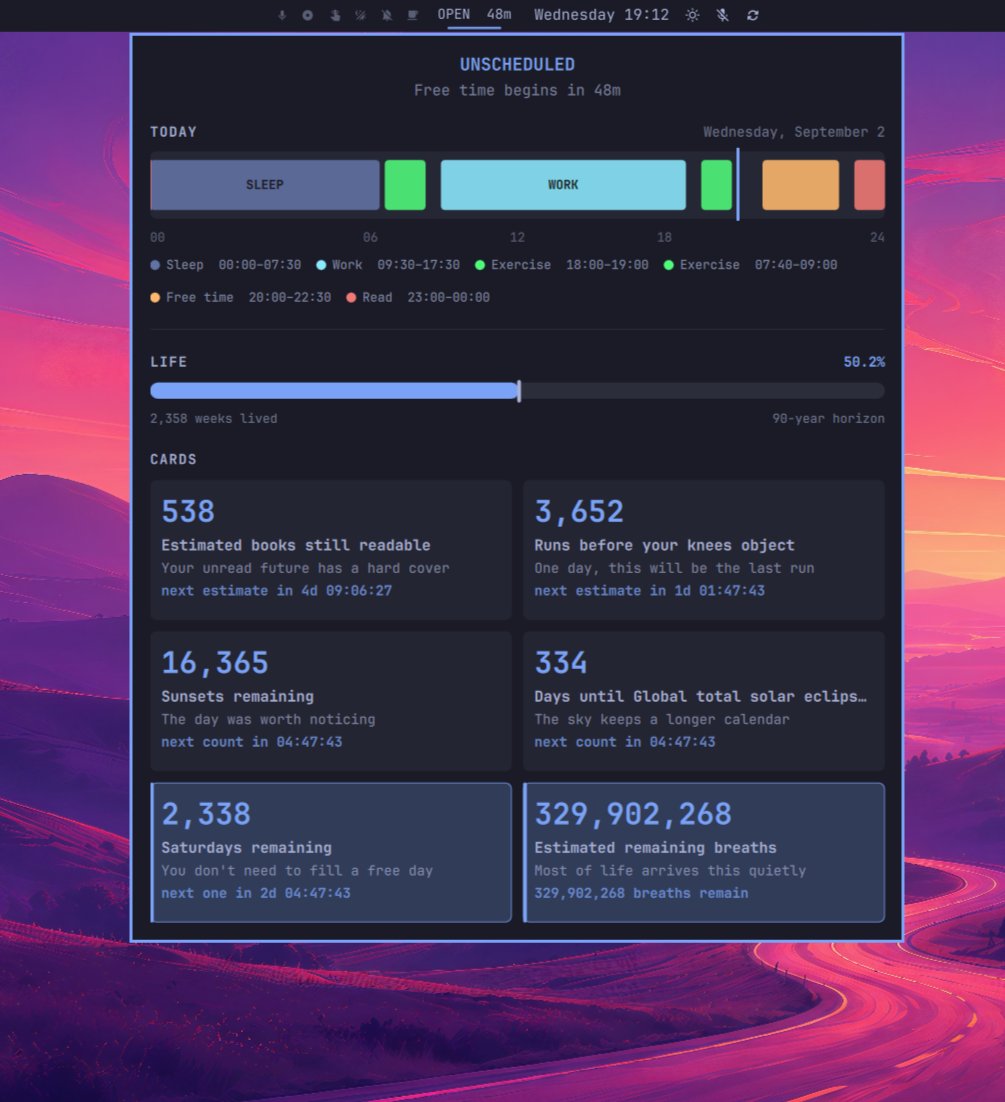
Inspired by @dhh life bar in Omarchy 4 I've made a top bar plugin for keeping myself accountable on the daily reccuring schedules plus a few reality checks on how much life should (hopefully!) still be ahead https://t.co/i9c9BgZRRt
This is the death of affordable local AI Rig
Even with open-weights models democratizing computation local AI adoption will not happen until consumer hardware is undergoing this neverending price shock