Meet NVIDIA Nemotron 3.5 Super VL
Our new open model combines reasoning and tool use with text, image, document, and video understanding for long-running AI agents.
120B total parameters with 12B active 🧵
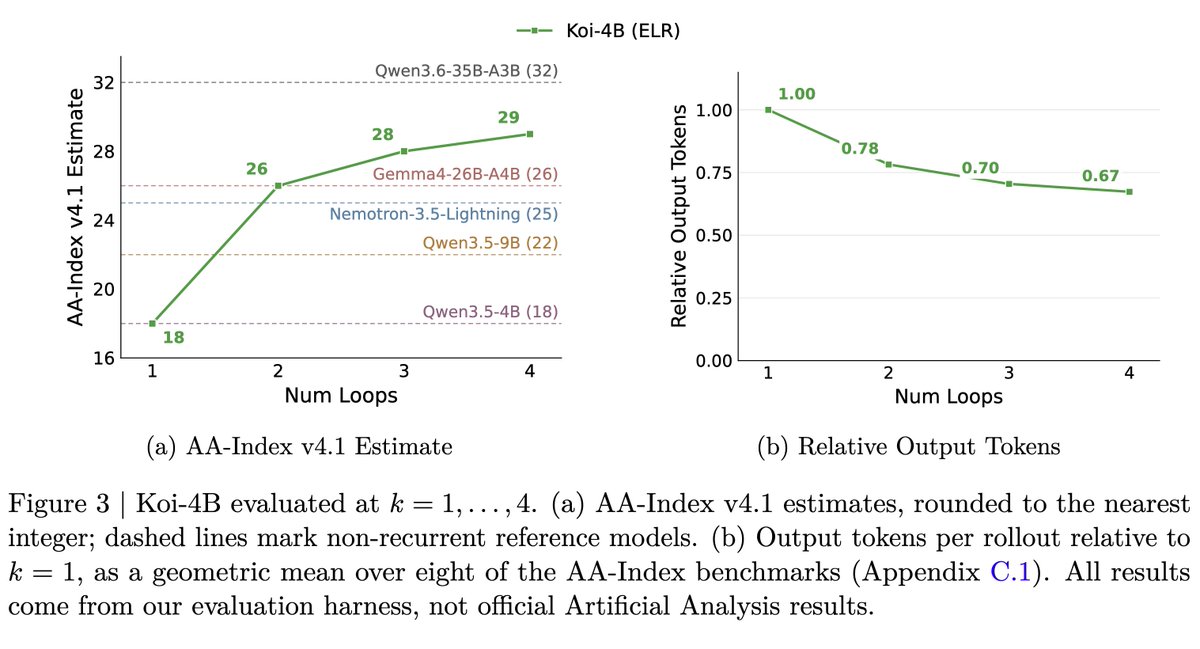
5/ We carry the recipe through pretraining and post-training to build Koi-4B. In our evals, one checkpoint scores an est. 18 on AA-Index v4.1 at one loop, matching competitive 4B models, and 29 at four loops, beating MoE models up to 30B total params.
Introducing our latest work on Elastic Latent Recurrence (ELR).
Looped LMs trade compute for accuracy, but usually fall behind a regular model at one loop. ELR stays close at one loop and improves with every extra loop.
Paper:
https://t.co/PhGcVZro6y
🧵
4/ At inference, keeping only the final loop's attention KV cache holds attention KV memory at its one-loop level while preserving most of the gains from extra loops.
3/ Looping adds training and inference cost. To cut it:
- Delayed mixed-depth training: loops only in the final stage of pretraining
- Cross-loop route replay: MoE layers reuse first-loop expert assignments on later loops
2/ How ELR works:
- A gated state update with a learned step size
- Loop counts mixed within each optimizer update
- Each pass conditioned on its loop index and loop budget
Introducing NVIDIA Nemotron 3 Ultra.
A frontier smart open model built for long-running agents that need to plan, reason, use tools and keep working across complex coding, research and enterprise workflows.
Up to 5x faster inference and up to 30% lower cost for agentic tasks.
Learn more: https://t.co/h9XLqqYPFf
Today we're shipping Nemotron 3 Ultra.
A 550B MoE frontier-intelligence open model built for long-running agents.
It delivers 5x faster inference and lowers the cost of complex agentic tasks by up to 30% versus other open frontier models.
NVIDIA has released Nemotron 3 Super, a 120B (12B active) open weights reasoning model that scores 36 on the Artificial Analysis Intelligence Index with a hybrid Mamba-Transformer MoE architecture
We were given access to this model ahead of launch and evaluated it across intelligence, openness, and inference efficiency.
Key takeaways
➤ Combines high openness with strong intelligence: Nemotron 3 Super performs strongly for its size and is substantially more intelligent than any other model with comparable openness
➤ Nemotron 3 Super scored 36 on the Artificial Analysis Intelligence Index, +17 points ahead of the previous Super release and +12 points from Nemotron 3 Nano. Compared to models in a similar size category, this places it ahead of gpt-oss-120b (33), but behind the recently-released Qwen3.5 122B A10B (42).
➤ Focused on efficient intelligence: we found Nemotron 3 Super to have higher intelligence than gpt-oss-120b while enabling ~10% higher throughput per GPU in a simple but realistic load test
➤ Supported today for fast serverless inference: providers including @DeepInfra and @LightningAI are serving this model at launch with speeds of up to 484 tokens per second
Model details
📝 Nemotron 3 Super has 120.6B total and 12.7B active parameters, along with a 1 million token context window and hybrid reasoning support. It is published with open weights and a permissive license, alongside open training data and methodology disclosure
📐 The model has several design features enabling efficient inference, including using hybrid Mamba-Transformer and LatentMoE architectures, multi-token prediction, and NVFP4 quantized weights
🎯 NVIDIA pre-trained Nemotron 3 Super in (mostly) NVFP4 precision, but moved to BF16 for post-training. Our evaluation scores use the BF16 weights
🧠 We benchmarked Nemotron 3 Super in its highest-effort reasoning mode ("regular"), the most capable of the model's three inference modes (reasoning-off, low-effort, and regular)
🚀 Nemotron 3 Nano 30B-A3B is here! Open weights + open data + open source.
AA Intelligence Index: 52 (@ArtificialAnlys )
✅ 1M‑token context
✅ up to 3.3× higher throughput vs similarly sized open models
✅ stronger reasoning/agentic + chat
Details + links in the thread 🧵
🚀 Introducing Star Attention - a novel inference method combining local and global attention to do LLM inference over long sequences.
✅ Improves inference by 11x while preserving 95-100% accuracy
✅Integrates with any LLM without any finetuning
Paper: https://t.co/FiGuo9nftP
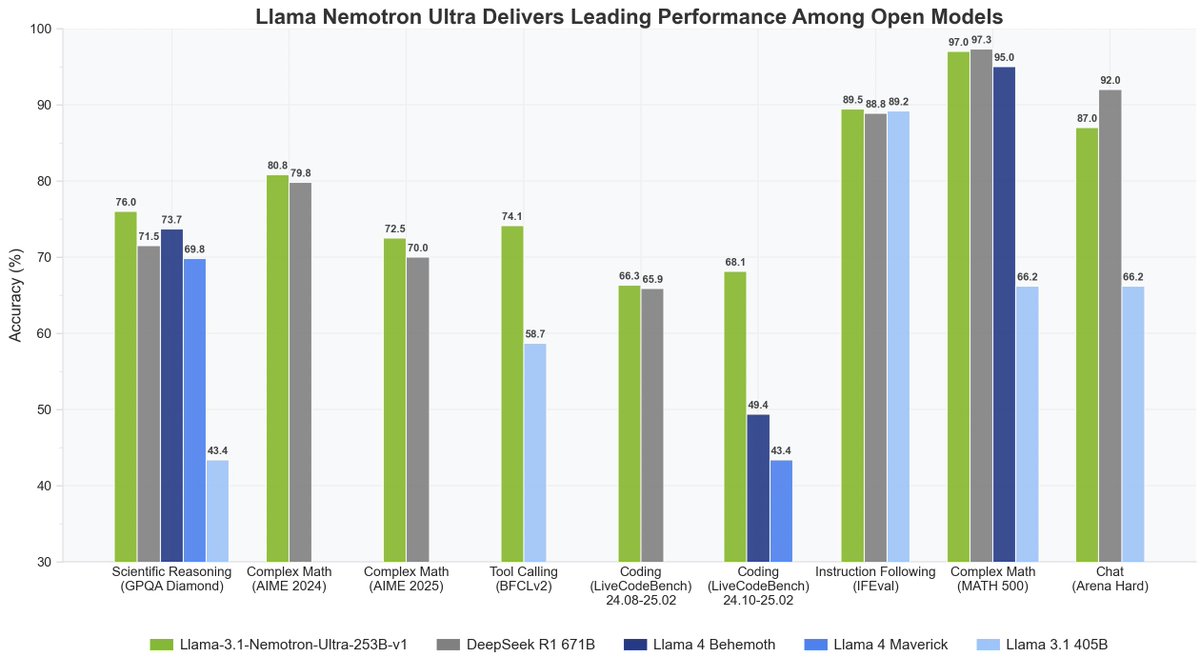
🎊 Llama Nemotron Ultra 253B is here 🎊
✅ 4x higher inference throughput over DeepSeek R1 671B
🏆Highest accuracy on reasoning benchmarks:
💎 GPQA-Diamond for advanced scientific reasoning
💎 AIME 2024/25 for complex math
💎 LiveCodeBench for code generation and completion
Try as #NVIDIANIM ➡️ https://t.co/bHVzfSbsZf
Technical deep dive ➡️ https://t.co/hsHmzJLig7
We are excited to release Llama-Nemotron-Ultra! This is a reasoning ON/OFF, dense 253B model. Open weights and post-training data. https://t.co/dCTacylBR8 We started with llama-405B, changed it via NAS pruning then followed by reasoning-focused post-training: SFT + RL in FP8.
8B and 56B Hybrid Mamba-Transformer models that provide better or comparable accuracy to other similar SOTA Transformer models while giving upto 3x inference speed.
Glad to have contributed to enhancing the long context capabilities of these models upto 128K context length.
Nemotron-H: A family of Hybrid Mamba-Transformer LLMs.
* Hybrid architecture means up to 3X faster at the same accuracy
* Trained in FP8
* Great for VLMs
* Weights and instruct versions to come soon.
https://t.co/h3dLuDuiUz
Meet the recipients of the 2024 ACM A.M. Turing Award, Andrew G. Barto and Richard S. Sutton! They are recognized for developing the conceptual and algorithmic foundations of reinforcement learning. Please join us in congratulating the two recipients! https://t.co/GrDfgzW1fL
Star Attention
Problem:
Processing long sequences with LLMs is slow and memory-intensive due to the quadratic complexity of attention.
Method:
Splits processing into local attention for blocks and global attention for queries, using an "anchor block" for context retention.
Insights:
Local attention suffices for most tasks, with the anchor block's content being critical for accuracy.
Results:
Achieves up to 11x faster inference with minimal accuracy loss, working effectively on long sequences and single-fact retrieval tasks.
Author @imSAcharya is on alphaXiv this week to answer your questions on his paper!
Star Attention is also being featured on the arXiv discussion forum @askalphaxiv
I will be on alphaXiv to answer any questions you have on the paper.
https://t.co/F8nqMoa6cr
🚀 Introducing Star Attention - a novel inference method combining local and global attention to do LLM inference over long sequences.
✅ Improves inference by 11x while preserving 95-100% accuracy
✅Integrates with any LLM without any finetuning
Paper: https://t.co/FiGuo9nftP