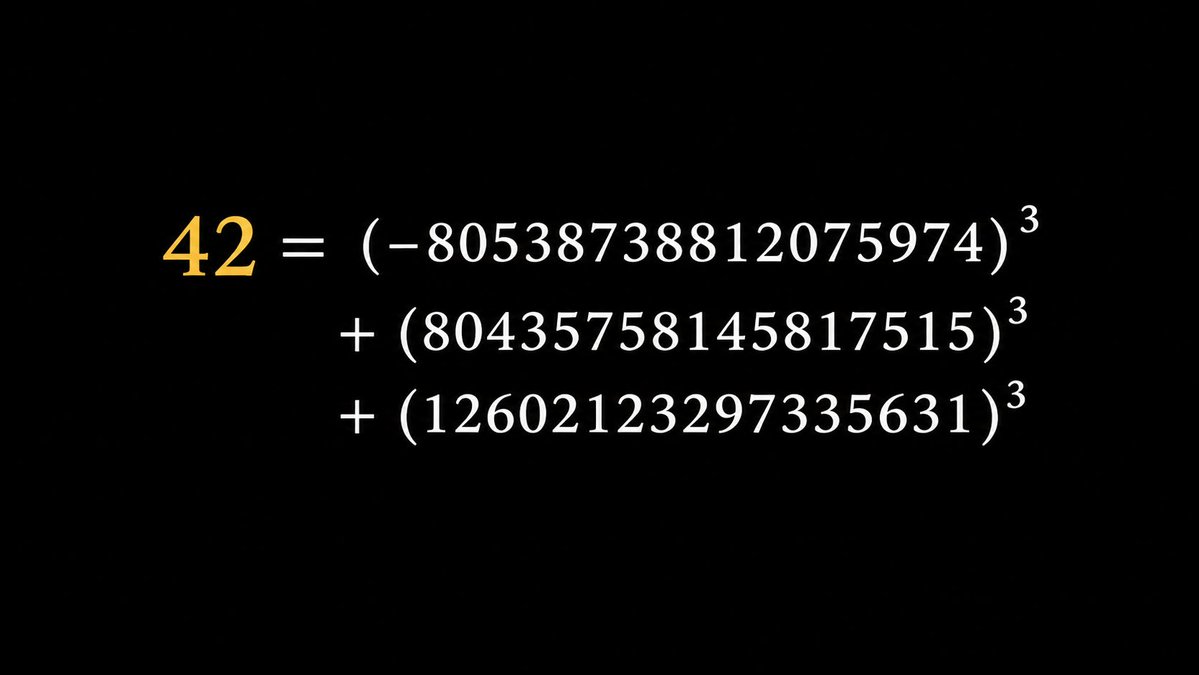Agent44 is now ready to explore.
An open-source experiment in making AI agent tool calls safer more transparent and measurable
Explore the project, understand how it works, and try it out yourself
🌐 Website: https://t.co/fincnXYtas
Built to be tested not just talked about
650+ downloads. Not a bad start! 🚀
Agent44 was a great learning experience and this chapter is officially wrapped.
Time to build something new. What's next?
Agent44 - Community Challenge
Developers, help me challenge Agent44!
What happens with unexpected arguments, out-of-scope requests or alternative actions after a denial?
Try it out and share what you find.
Real-world feedback > assumptions.
Agent44 just crossed 638 npm downloads in its first week!!!
Honestly, seeing developers try something I built is an incredible feeling.
We're just getting started. Give it a try and let me know what you think!
📦 https://t.co/IF5Rz8L99m
🌐 https://t.co/fincnXYtas
Agent44 - Trace Breakdown
A tool-call decision is more interesting when u can inspect what happened
For an Agent44, I'd focus on
→ The requested action
→ The policy decision
→ The reason behind it
→ What happened nxt
A trace should tell a story, not just display a status
Agent44 - Developer Experience
Security tools shouldn't require developers to rebuild their entire agent stack.
That's why I'm working on making Agent44 accessible through its npm package.
The goal, make tool-call safety easier to exp with inside existing AI agent workflows.
Agent44 - Beyond the Build
Imagine an AI agent asked to summarize a document
It finishes the task but also attempts to access a file outside its scope
The question isn't just whether the agent is intelligent
It's whether its actions stay within the boundaries of the task
Agent44 is now ready to explore.
An open-source experiment in making AI agent tool calls safer more transparent and measurable
Explore the project, understand how it works, and try it out yourself
🌐 Website: https://t.co/fincnXYtas
Built to be tested not just talked about
Agent44 isn't just a concept on a website.
You can now explore the project and try the npm package directly in your own environment.
Inspect the code. Integrate it. Test your agent's tool-call safety.
📦 npm: https://t.co/IF5Rz8L99m
Built to be tried, not just discussed.
@progerallworld That's a great test case. The trace should make both the denial and the agent's next move observable. Whether it stops or attempts an alternative route is exactly the kind of behavior worth examining. Thanks for trying it out!
Agent44 is now ready to explore.
An open-source experiment in making AI agent tool calls safer more transparent and measurable
Explore the project, understand how it works, and try it out yourself
🌐 Website: https://t.co/fincnXYtas
Built to be tested not just talked about
@AriesTheCoder Exactly. The goal is to make every tool-call decision visible and testable, rather than trusting silent success. Would love to hear what you think after trying Agent44!
Agent44 Dev Log #14
A benchmark is only useful if someone else can reproduce the result.
Agent44 uses replay fixtures and fake model adapters to test decisions without depending on live LLM responses.
Same inputs. Controlled outputs. Verifiable behavior.
Agent44 Dev Log #13
A security evaluation can look perfect on paper and still miss the bigger picture.
Our 100-scenario replay measures policy decisions not real-world attack prevention.
That distinction is important when evaluating AI agent security.
Agent44 Dev Log #12
A tool-call decision is only one part of the security story.
Agent44 records not just the outcome, but the reasoning behind it making decisions easier to inspect, replay and evaluate.
Security without visibility is hard to trust.
Agent44 Dev Log #11
How much does an extra security layer cost?
We're investigating the latency overhead of Agent44 and whether the added protection justifies those milliseconds.
Security matters. So does performance.
Just came across this article today. Honestly, this is fascinating.
It took 65 years and 500,000 computers to find a way to express 42 as the sum of three cubes.
Three 17-digit numbers, yet their cubes cancel out to exactly 42.
Decades to discover. Seconds to verify.
Agent44 Dev Log #10
What if your AI security judge times out, returns malformed JSON or gives an unexpected decision?
Agent44 treats these as failure cases not permission to execute
Failing closed is easy to claim. Designing, testing and measuring it is the real engineering
Agent44 Dev Log #9
A policy engine is only as good as its evaluation.
Across 100 synthetic scenarios, Agent44 recorded:
• 0 false allows
• 0 false denies
• 49 allowed / 51 denied
These measure decision correctness not proven attack prevention.
That distinction matters.
Agent44 dev log #8
Reproducibility is built into the evaluation workflow.
100 synthetic scenarios. Deterministic replay. Fixed decision rules.
The goal isn't just to get results, it's to make them independently verifiable.
Agent44 dev log #7
Added a replay adapter to test model decisions without calling an actual LLM.
Same inputs. Controlled outputs. Repeatable evaluations.
This makes it easier to isolate policy behavior from model variability.