@SebAaltonen > Apple has a very nice ray scheduling/packing hardware (does more than SER)
Is there any public information on this? Or is it visible in GPU captures? Curious as I haven't seen any signs of packing/reordering/SER-like behavior (at least on M3 hardware)
@stefan_3d@yiningkarlli NVIDIA does support runtime compilation via NVRTC (https://t.co/v5jGrLk9hn). You still need to ship the NVRTC library with the program, but it should be lighter than bundling the CUDA toolkit
Adobe just released an Apache-2.0 licensed reference implementation of the OpenPBR Surface standard, extracted from their in-house Eclair renderer.
Neat trick: the reference implementation cross-compiles for C++, GLSL, Cuda, Metal, and Slang!
https://t.co/T9tgTHsDXO
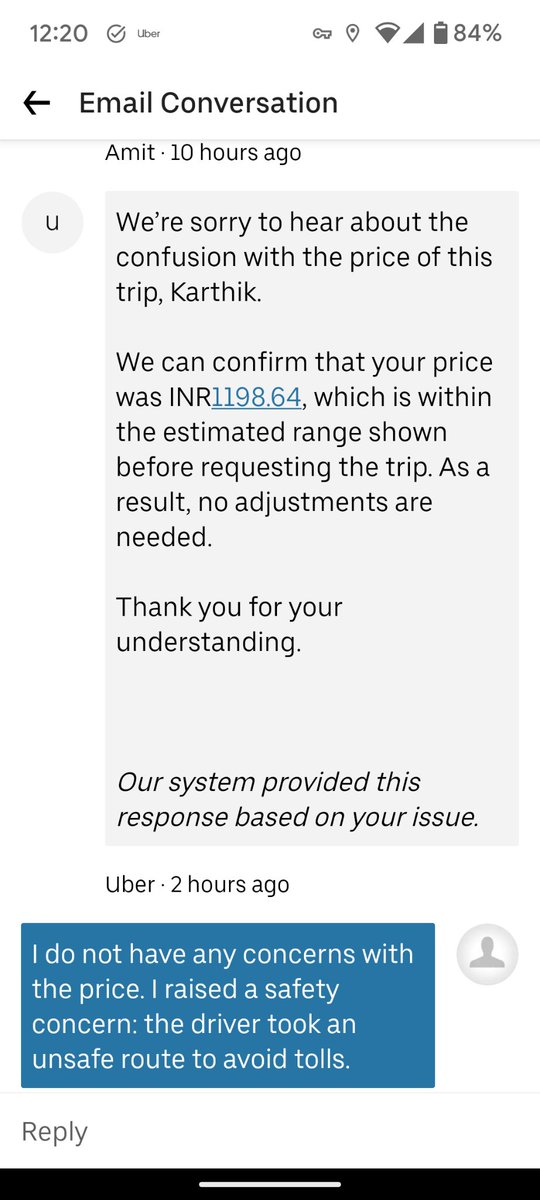
@Uber_India support is brain-dead. I raised a safety complaint that the driver took a longer, unsafe route to avoid paying tolls, and the support response is some nonsense about price?!?
REAC 2025 talk details have been posted on the website! Register today - it's free! https://t.co/cwrCfbUKTf
If you can share this message, we'd appreciate it. Thanks, and see you soon!
@lefticus if (a)
do_a_thing();
if (b)
do_b_thing();
Does 100% line and branch coverage imply that the case (a && b) is tested? Likely not, and I'd argue there are bugs. I've seen this happen with two separate (tested) features that work well on their own, but not together
@pavpanchekha > two per cycle
Is this assuming there are enough memory requests queued up(with the final address known), and that the data is already in the last-level cache?
@j_bikker @petermcneeley84 Curious what specifically you'd like to have more control over? The BVH construction heuristics? Scheduling of any-hit/closest-hit shaders? Something else?