🪗 Your Transformer Is Secretly Elastic 🧵👇
Transformer families come in a few fixed sizes, so you commit to one for your hardware and latency constraints, even as query loads vary. What if a single pre-trained model could serve every budget?
We learn one importance ranking over every MLP neuron and attention head, once, with frozen weights. At inference time, the model can then be pruned to any computational budget by dropping its least important units, without retraining.
Across 27 vision and text encoders spanning 22M to 8B parameters, performance degrades smoothly up to 60% sparsity. For example, pruning DINOv3 ViT-H+/16 to 50% sparsity removes 427M parameters, for only a 0.8% drop in ImageNet-1k linear probing.
Super fun project in collaboration with Dheeraj Varghese (@dhevarghese), supervised by Gertjan J. Burghouts (@gjburghouts) and Cees Snoek (@cgmsnoek)
🌐 Project page: https://t.co/zBNxee1Xyh
Ever wondered whether AI agents could play thousands of video games on a supercomputer? We did. 🎮
Introducing PlaySuite: 5,734 games, 14 open models, and a large-scale benchmark for interactive visual intelligence.
Here's what we built, and what we learned. 🧵👇
♾️ LiFT: Loop Flow Transformers 🧵👇
Diffusion models usually spend more inference compute by taking more sampling steps. What if we could also spend compute inside each step?
LiFT turns part of a DiT into a recurrent core, letting us scale depth at inference with only a small architectural change. On ImageNet, it beats dense DiT-XL/2 with 3.34 lower FID, while using 60% fewer parameters, 32% fewer training FLOPs, and 52% fewer inference FLOPs.
Jointly led with Mohammad Mahdi Derakhshani 👑(@mmderakhshani)
And amazing supervisors Cees Snoek (@cgmsnoek), Jan-Willem van de Meent (@jwvdm) and Gertjan J. Burghouts (@gjburghouts)
[🔁🚨PhD opening]
We have a new opening for a PhD student at our @FunAILab at the University of Technology Nuremberg on combining Vision-Language-Action Models with 3D Geometry.
This PhD position is in close collaboration with @HelsingAI with the amazing researcher @TomUnterthiner and will be a unique opportunity to conduct research and have impact.
Please see below for more information:
https://t.co/9FU8ryPTPN
We particularly encourage applications from people of diverse and underrepresented backgrounds. If you have any doubt if you should apply or not, send me a message.
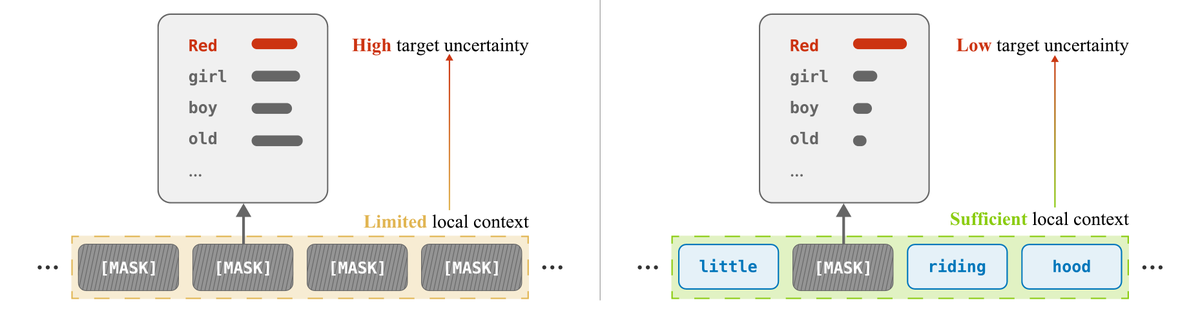
New preprint: Context-weighted Discrete Flow Matching.
Paper: https://t.co/iHokRakAtG
We study how local context relates to token predictability in discrete flow and diffusion models -- and how it can be used to improve sampling.
🧵
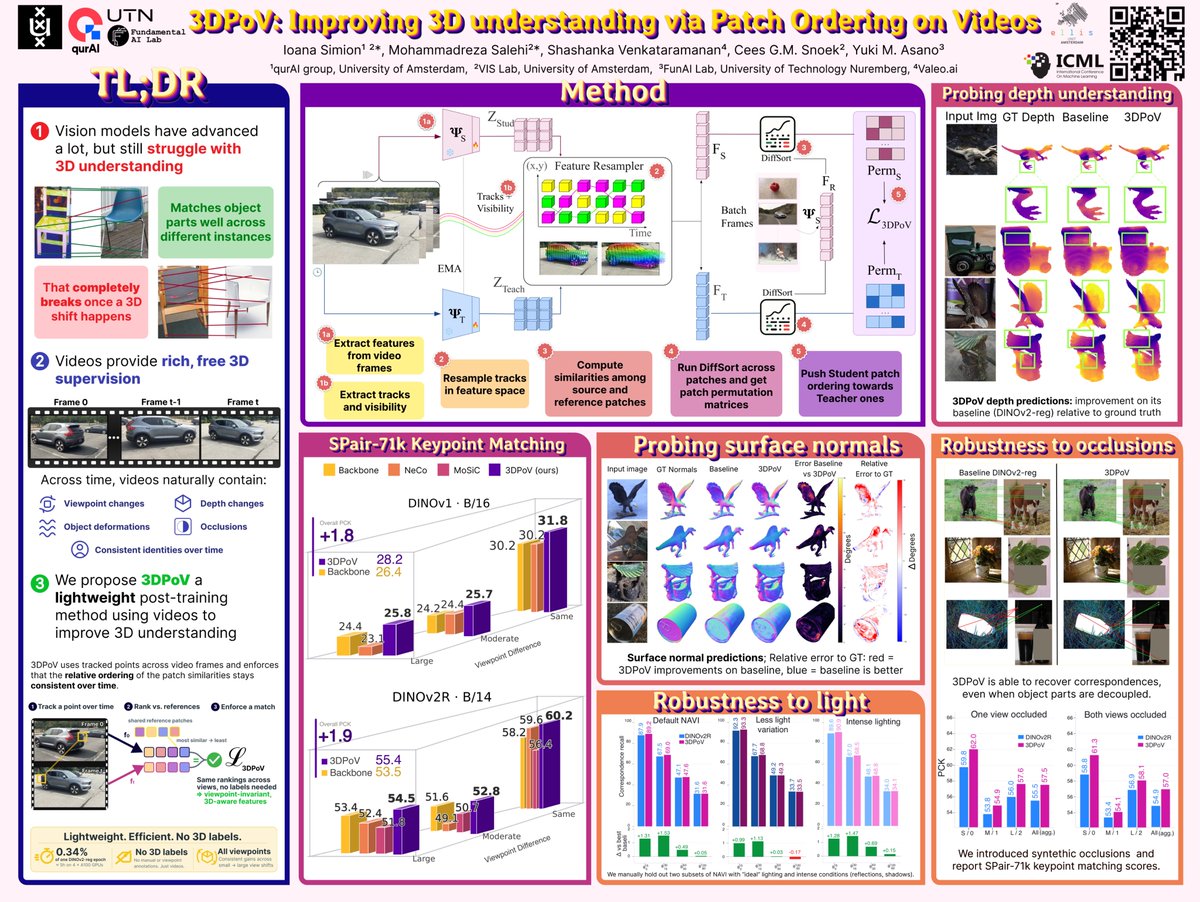
(1/n) What if you could teach a vision model about 3D structure without a single 3D label and just a tiny fraction of its pretraining compute? 👁️ That’s 3DPoV. ✨ Heading to #ICML2026 in Seoul 🇰🇷 to share it 👇
🎉[openings] I’m hiring postdoctoral researchers to join our @FunAILab at UTN through the Alexander von Humboldt Research Fellowship (@AvHStiftung), via the Henriette Herz Scouting Programme.
As a Henriette Herz Scout, I can nominate outstanding international researchers for this fellowship route. I’m especially keen to hear from candidates working on multimodal learning, video and image pretraining, and post-training.
Fellows would be hosted in our lab at UTN and work closely with us on these topics.
Key requirements:
* finished your doctoral studies less than 4 years ago or will finish in the next 6 months
* did not live/work in Germany in the last 10 years
* applications from female, trans* and/or non-binary candidates are highly encouraged!
Interested? Please send a short note with your CV, PhD year, current affiliation, 2–3 key publications, and a few lines on how your work connects.
Please share! 🔀
Ever asked yourself: 𝙃𝙤𝙬 𝙙𝙤 𝙩𝙚𝙭𝙩-𝙤𝙣𝙡𝙮 𝙇𝙇𝙈𝙨 "𝙨𝙚𝙚" 𝙩𝙝𝙚 𝙫𝙞𝙨𝙪𝙖𝙡 𝙬𝙤𝙧𝙡𝙙?
Our new TMLR paper finds that language capability predicts visual alignment of LLM features (r=0.768).
This means: LLM progress boosts vision(-language) models as well.
🧵⬇️
I’m excited to announce that our workshop “Multimodal Intelligence: Next Token Prediction & Beyond” will take place at ICLR 2026!
📅 April 2026
📍Rio de Janeiro, Brazil
🔗https://t.co/rk77hbL1dd