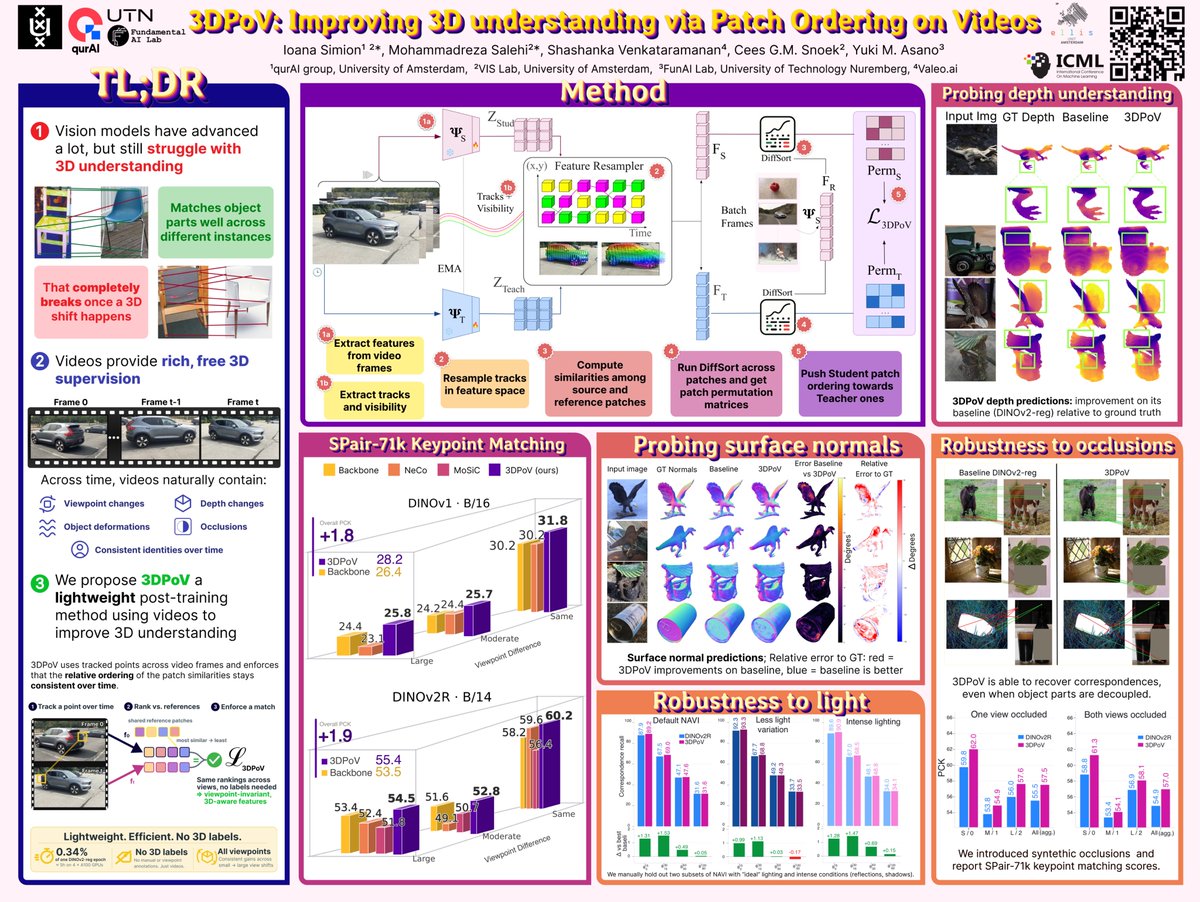
(1/n) What if you could teach a vision model about 3D structure without a single 3D label and just a tiny fraction of its pretraining compute? 👁️ That’s 3DPoV. ✨ Heading to #ICML2026 in Seoul 🇰🇷 to share it 👇
(5/n) Come find me at ICML!
📍Tuesday 2PM -> Hall A, poster #1309
Happy to talk 3D, self-supervised learning, or vision transformers ✨
Huge thanks to my amazing co-authors @MrzSalehi@shawshank_v@cgmsnoek@y_m_asano 🙌
Very excited about our work on finding the right drifting direction 🐎
We tackle a core open question in drifting: when does “no drift left” mean the model really matched the data?
Kernel-gradient drifting is the answer (with natural extensions to manifolds + discrete data)!
Discrete diffusion — but fast? ⚡️ Test-time inference — but for discrete data? 🧠
Categorical Flow Maps: continuous transport toward the simplex, turning discrete generation into a single-step problem. Built on Variational FM (CatFlow), we obtain (self-)distillation from scratch.
Language, molecules, and test-time steering — one framework.
Scaling to LLMs and foundation models next. Watch this space 👀
You like discrete diffusion, but it's too slow? 🥀
You like test-time inference, but it's for continuous methods? 😩
We fixed it.
Introducing Categorical Flow Maps: continuously sample discrete data in a single step 🚀💫
How? 🧵⬇️
💪 Co-led with @FEijkelboom, @daan_roos_
🚨 New paper accepted at @ICCVConference
As video foundation models gain momentum, we introduce MoSiC—a method that leverages motion as supervision to learn dense, temporally consistent representations.
Full details in the thread! ✨
New paper out - accepted at
@ICCVConference
We introduce MoSiC, a self-supervised learning framework that learns temporally consistent representations from video using motion cues.
Key idea: leverage long-range point tracks to enforce dense feature coherence across time.🧵
🎉 NeCo is accepted to @iclr_conf#ICLR25
TL;DR: Self-supervised patch-level neighbor consistency boosts dense features of foundation models like DINOv2—in just 19 GPU hours.
📍 Tomorrow,10:00–12:30@Hall3+Hall2B#133
📄 Paper: https://t.co/er8Y47trVI
Wait, we can just ask? 🙋
Here's what we do at @FunAILab in Nuremberg: research on self-supervised learning from images and videos and building /improving (M)LLMs. @nvidia@LambdaAPI@CohereForAI :)? Happy to provide more info.
🚀 Excited to present SIGMA at @eccvconf ! 🎉 We upgrade VideoMAE with Sinkhorn-Knopp on patch-level embeddings, pushing reconstruction to more semantic features. With @mdorkenw.
Let’s connect at today's poster session at 4:30 PM, poster number 256, or send us a DM.
First time organising a Tutorial with an amazing team and am very excited 🎉! The topic is learning from videos, which I think will be the new 'Big' paradigm for new vision foundation models. Come to learn, chat and discuss @eccvconf!
📰 blogpost:
https://t.co/9OWML2JPkX
🕹️ google colab:
https://t.co/vBxnTWhALp
I tried to make the blog post more accessible than the paper and added a lot of supporting visualizations.
Please check it out if you are curious about spacetime-equivariant CNNs 🚀