Continuous Diffusion LMs went from niche to contender this year, but the recipe is shaky: why self-conditioning? How to embed tokens? 🤨
Our new work takes your one-hot flow from 4% to 50% on TinyGSM without self-conditioning, and explores the design space of CDLMs. 🔥🚀 (1/6)
Introducing PoEM.
With PoEM you can simulate an RL policy for a reward without doing the RL training, provided you trained for a broad family of other rewards in the past.
Even if the reward functions are not linearly connected, we find that RL often leads to log-policies that are approximately linearly connected.
This allows us to approximate a new RL run without actually doing a new training.
We tried PoEM for both LLMs and diffusion models, using programmatic and neural rewards.
Our Midpoint Generative Models (MGM) are out and heading to NeurIPS 2026! 🎉
To build a one-step model directly from real data, we use a neat fact: the Flow Matching velocity between real and generated data at t = 1/2 vanishes once the generator matches the data.
Joint work with @d_shlenskii, @leffffffffffff1 & @iamalexkorotin👇
(1/9) Quantizing recurrent language models is easier than you think!
Hybrids compete at scale (e.g. Qwen, Kimi, Nemotron). Yet the PTQ stack has largely been tailored to softmax attention. 🤔
In this work, we reveal that recurrent models can be easier to quantize.
Introducing Ambient SFT: a drop-in replacement for SFT for llms.
Finetuning LLMs on small datasets makes them forget.
Ambient SFT solves this by treating the model pre-finetuning as a "noisy teacher", that we can only trust at a coarse level.
Works for domain adaptation, instruction following and reasoning, with improvements reaching up to 21% relative to vanilla SFT.
⚠️ Numerical issues can go on silently for decades like in the softmax/CE! Similar issues are present in other widely-used divergences like the KL and JSD
I just posted this paper overviewing what they are and how to fix them:
📚 https://t.co/hKlMwrV6xN
Big reasoning speedups are here. 1,000× faster training and 280× less compute than any looped model. All done using a fully trainable energy from the 80s
Keep reading to hear how energy is the right paradigm for reasoning
With @HughBlayney@jcrwhittington@prefrontal_ai
🧵/10
Presenting “Monte Carlo Methods for Diffusion Model Sampling” at the Mostly Monte Carlo seminar tomorrow (Fri, 2:30pm) at PariSanté Campus
Alongside @__SimonCoste__ who will present “Importance Sampling”
https://t.co/3aOUL88N1y
I’ll be giving a tutorial on diffusion language models at AACL-IJCNLP 2026 on Nov. 10
w/ @Bollegala
🔗 https://t.co/zTumLwYrBa
(Slides coming soon!)
#aacl2026@aaclmeeting
💭Grateful for the opportunity to organize my perspective on this fast-moving field and share it with the NLP community. This will be my first tutorial, so it’s a bit of a personal challenge for me as well. Looking forward to the discussions :)
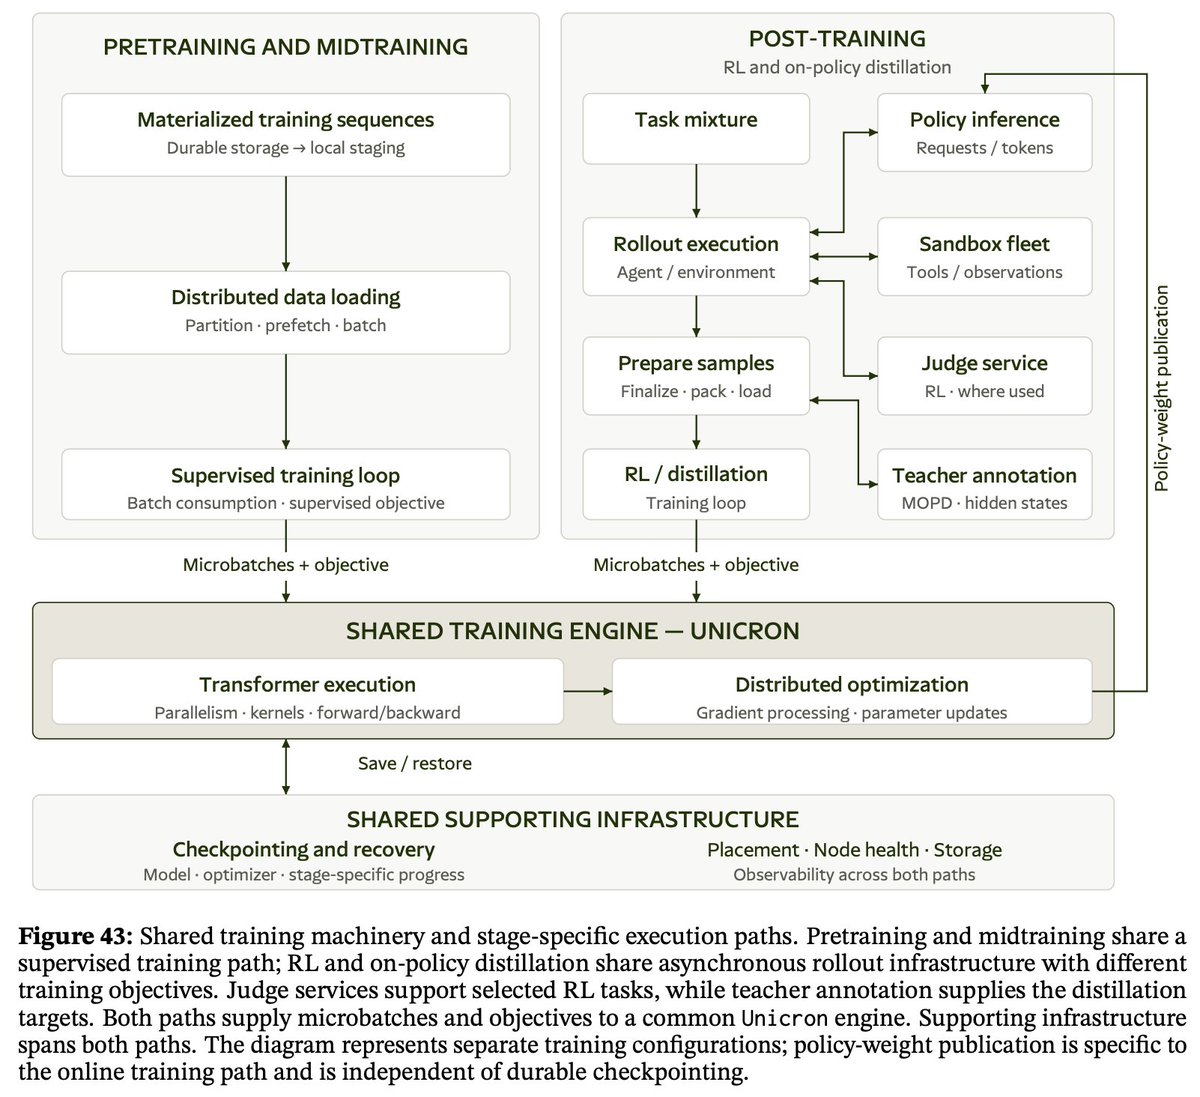
We've posted a 156-page tech report on Beam! We have good systems and it's worth reading. It covers all phases through pre-training, mid-training, SFT, RL, and OPD and goes into the infra, data, and scientific decisions we made throughout the process
📚 https://t.co/UPwkbAnlb3
Incredible work led by @ntumm120
Building a whole framework for quantizing linear attention models such as GDN, KDA and Mamba 🔥
The key is to leverage several computational invariances of these models in a clever way.
Check it out 👇
Excited to share that our paper, “Kernel-Gradient Drifting Models,” has been accepted to NeurIPS 2026! ❤️
📄 Paper: https://t.co/WeDMRyrqbM
💻 Code: https://t.co/7ugk1cwaFf
Happy to share our most recent work:
An ODE-based Sampler for Discrete Diffusion Models
- we introduce a probability-flow analogue for discrete diffusion: deterministic dynamics that preserve its time marginals.
- we derive a principled discretization and efficient implementation for both MDM and UDM.
- this allows a theoretically grounded consistency distillation objective.
https://t.co/lOMB1zQL5i
Joint work with @samsongvch, @ericxing, @EricMoulines, @AlainDurmus and Giacomo Zanella
We are very excited about this direction and believe that it can be pushed much further!
(1/n)
1/9
We built CoBit for language. Then we asked: what happens if we use the same architecture for images, speech and proteins?
Turn each modality into bits. Flatten. Denoise.
The surprise: how little had to change.
https://t.co/cnhNArJrpg
This will change how LLMs are trained: Parallel Language Models predict several tokens in parallel at autoregressive quality. Add a parallel decoder at pretraining, get 5.7x speedup after posttraining.
🧐 → https://t.co/vXTeHmLOEe
ℹ️ → https://t.co/UuhnIBJZ6x
Read on: 🧵 1/4
Stellar lineup at the AITHYRA Next generation AI for Biomedical Science workshop -- next Monday 2 Nov at the IMBA lecture hall in Vienna Biocenter. No registration is required.
Excited to share our work on information-theoretic scaling laws for diffusion models, with @druv_pai and @YiMaTweets!
By quantifying how much information a model learns from data, we can predict when memorization begins and how generation quality (FID) scales with training.
We generated 458,000 RL environments to train an agent on stateful, multi-step on-device tasks. We share in our preprint how we decided along which axes to enlargen our RL env corpus, via data composition scaling laws.
📄 https://t.co/lqyzIyvvtF
🧵1/9