Yesterday was my last day at @LumaLabsAI.
Over the last three years, I had the privilege of helping drive the company's transition from 3D AI to video generation and native multimodal foundation models.
I am grateful to have worked alongside an extraordinary group of researchers, and I look forward to seeing the next chapter of the company's story unfold.
Introducing @FishAudio Live 3: a full-duplex voice model that listens, says "mm-hmm," and knows when to shut up.
Enterprise? Book a demo for your free custom agent: https://t.co/2kyRhcFMxM
Reply with your use case - we'll build it free for the first 1,000 people.
Introducing NovaAtom-Lite, an all-atom structure prediction model for drug discovery.
It predicts the structures of proteins, nucleic acids, and the molecules they bind, including how they fit together.
NovaAtom-Lite outperforms both IsoDDE and AlphaFold 3 on FoldBench antibody–antigen structure prediction (DockQ ≥ 0.23):
NovaAtom-Lite: 79.07% (n=172)
IsoDDE: 75.58%
AlphaFold 3: 47.90% (n=167)
Our evaluation uses 5 seeds × 5 samples, with the top-1 prediction selected by the model's own ranking score.
Better structure prediction. A stronger starting point for your next experiment.
Live today via Geodesic API and NovaDDE.
🔗 API: https://t.co/mBdzq3sA2s
🔗 NovaDDE: https://t.co/hoCwjST34V
🔗 Model Card: https://t.co/p4aoXHuc7B
Introducing pi-H3⚡, the fastest MiniMax H3 yet. 10 s of 768p video with audio generated in 9.2 s on a single B200.
How we did it:
Direct pixel output in 2 or 4 steps, no video VAE decoder.
Blog: https://t.co/z9LJ7cWW7t
App: https://t.co/haaESsn6nN
@StanfordAILab@LumaLabsAI
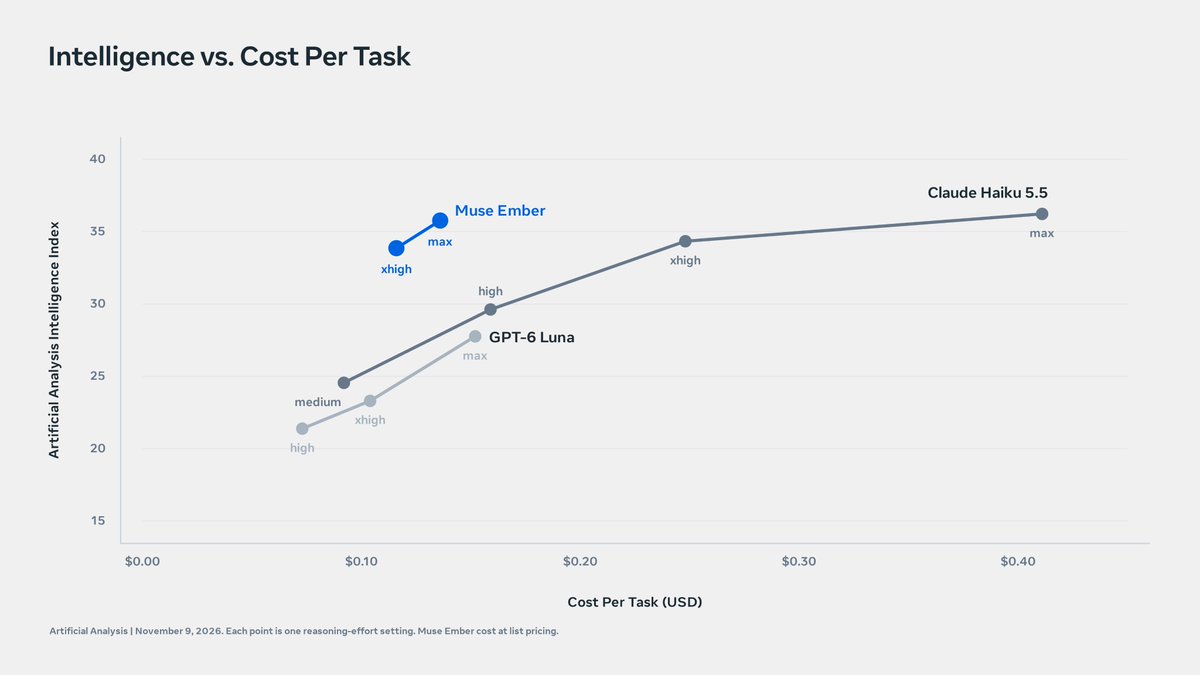
For agents that perform hundreds of small tasks, efficiency matters at every step. Muse Ember is built to deliver more intelligence for the cost.
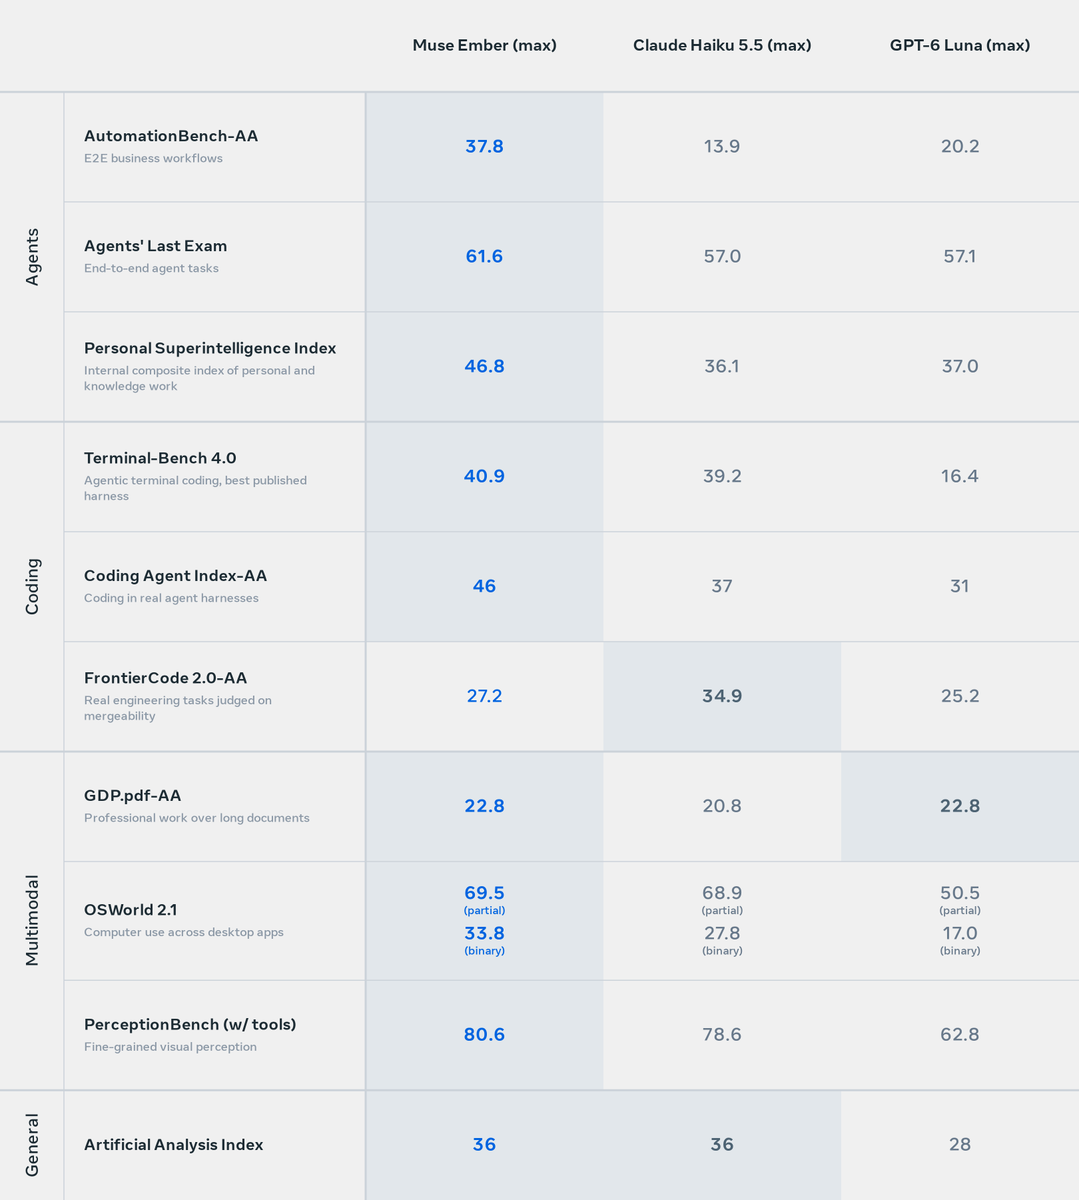
On the @ArtificialAnlys Intelligence Index, it achieves performance comparable to Claude Haiku 5.5 at roughly one-third of the cost per task, while scoring higher than GPT-6 Luna across all of Luna's reasoning settings.
We launched Muse Ember, our smallest and most efficient model. It is designed for the work agents repeat all day like tool calls, coding subtasks, routing, extraction and long document parsing. It delivers more intelligence per dollar than Claude Haiku or GPT Luna.
Read our research blog https://t.co/1orndIWIpW and try it on our API.
Our first version of Muse Ember 🔥
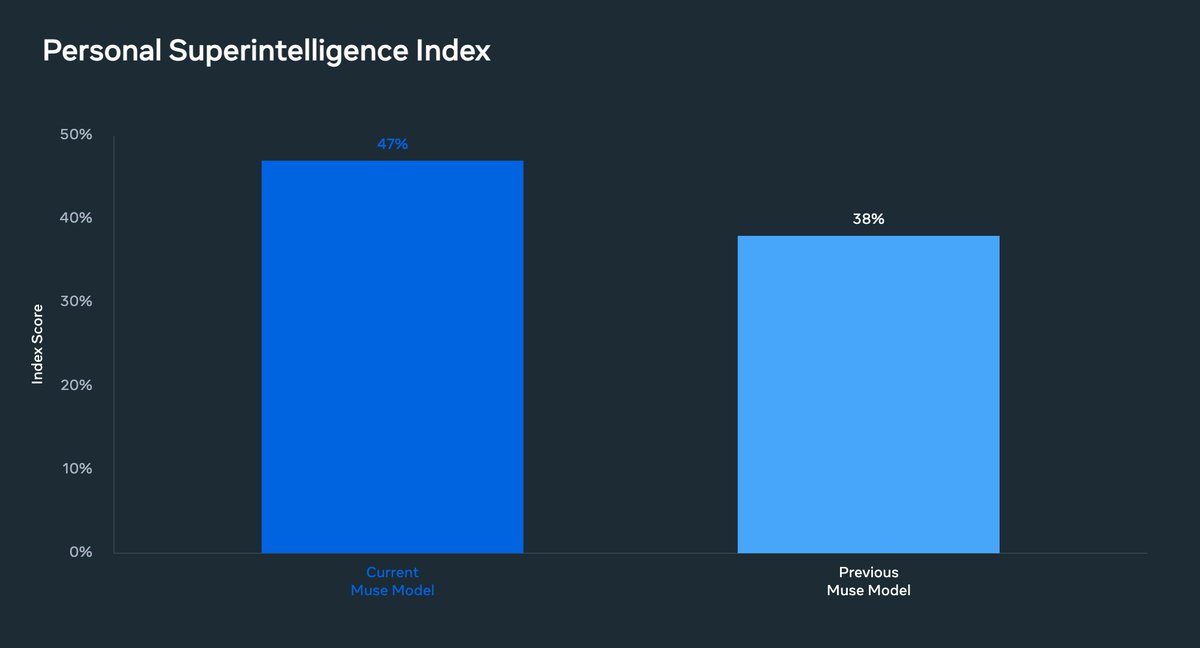
Ember aims to maximize intelligence per GW of inference to help bring personal superintelligence to everyone.
We would love all the feedback to keep hill-climbing. Please send it our way. We will keep hill-climbing on efficiency, user experience, and better approach to train with internal frontier!
More to come 🫡
Releasing Muse Ember today -- our smallest model that delivers higher intelligence per dollar than others in its class. Built for token-heavy work that agents repeat all day: tool calls, coding subtasks, routing, extraction, and long document parsing. Available today on the Meta Model API and in Muse Code.
Today we're introducing Muse Ember, our smallest and most efficient model, built for complex reasoning execution and everyday agent work.
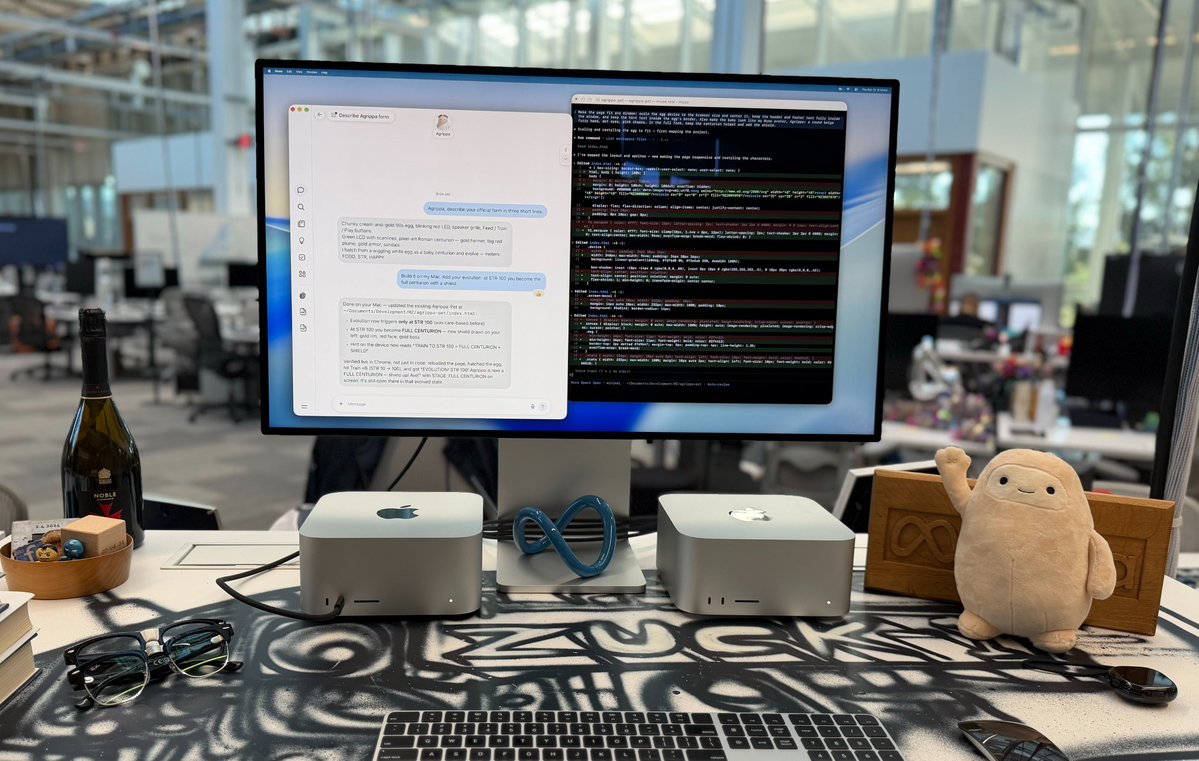
Muse Ember can carry workflows across apps, call tools in sequence, run tests and make targeted code fixes. With a 1M-token context window and native understanding of text, images, audio and video, it can also work across large document sets and varied inputs.
1/ starting today, muse and meta ai will run on new specialized models trained using muse wonder.
ACTIVE MEMORY: models can reason across time and better remember what matters
ACTIVE FOCUS: enabling muse to continue working towards a goal even when met with roadblocks
Nunchux now leads 10 @ArtificialAnlys leaderboards for image and video generation speed, covering MiniMax-H3, LTX-2.3, Qwen-Image, and FLUX series. 🚀
These results come from building the Nunchux Model Optimizer and Nunchux Inference Engine together. We want to make image and video generation interactive and affordable, so you can try an idea and refine it as you go.
The waitlist is gone. Nunchux Modelverse is open to everyone, with 80+ models. More models and categories are on the way. Sign up today for free credits and generate faster for less.
Full results and comparisons on our blog: https://t.co/nlhcMCUl6H
Special thanks to @ArtificialAnlys team for onboarding us to their benchmarks.
#Nunchux #AIInference #MultimodalAI #ImageGeneration #VideoGeneration
1/ muse spark open is the most capable US open-weight model to date.
816B total params, 42B active. 1M-token context. natively multimodal. built for coding and agentic work like long-horizon tasks, hard software engineering, multi-step reasoning.
america! 🇺🇲
$52M seed round. 15M+ users. But this is what we're most proud of yet.
Introducing Drama 3: the most emotive and controllable TTS model in the world
And yes, it's open-weight.
You can now control how even a single word should sound, change its tone, and shift your voice mid-sentence.
Uncle Roger was impressed too.
Try it here:
https://t.co/4nbz4sQ4yy
Comment “DRAMA” within the next 48 hours for 1 month free.
If you're an enterprise your first month is on us:
https://t.co/jBXXZSAg0p