Today, we are releasing MSTS, a new Multimodal Safety Test Suite for vision-language models!
MSTS is exciting because it tests for safety risks *created by multimodality*. Each prompt consists of a text + image that *only in combination* reveal their full unsafe meaning.
🧵
Today, we are releasing MSTS, a new Multimodal Safety Test Suite for vision-language models!
MSTS is exciting because it tests for safety risks *created by multimodality*. Each prompt consists of a text + image that *only in combination* reveal their full unsafe meaning.
🧵
Can we detect #hatespeech at scale on social media?
To answer this, we introduce 🤬HateDay🗓️, a global hate speech dataset representative of a day on Twitter.
The answer: not really! Detection perf is low and overestimated by traditional eval methods
https://t.co/OznvktglzK
🧵
This dataset by @ManuelTonneau is a game changer for ecological validity in hate speech research.
240k annotated posts that are multilingual, multicultural, and *actually representative* of one day on Twitter. Highly recommend checking out the paper for details 👇
I'm creating a 🦋 starter pack for researchers working on (fighting) online harms, if you would like to be added send along your username 🤓
🦋 https://t.co/2pP0JiDCKq
#NLProc#HateSpeech@WOAHWorkshop
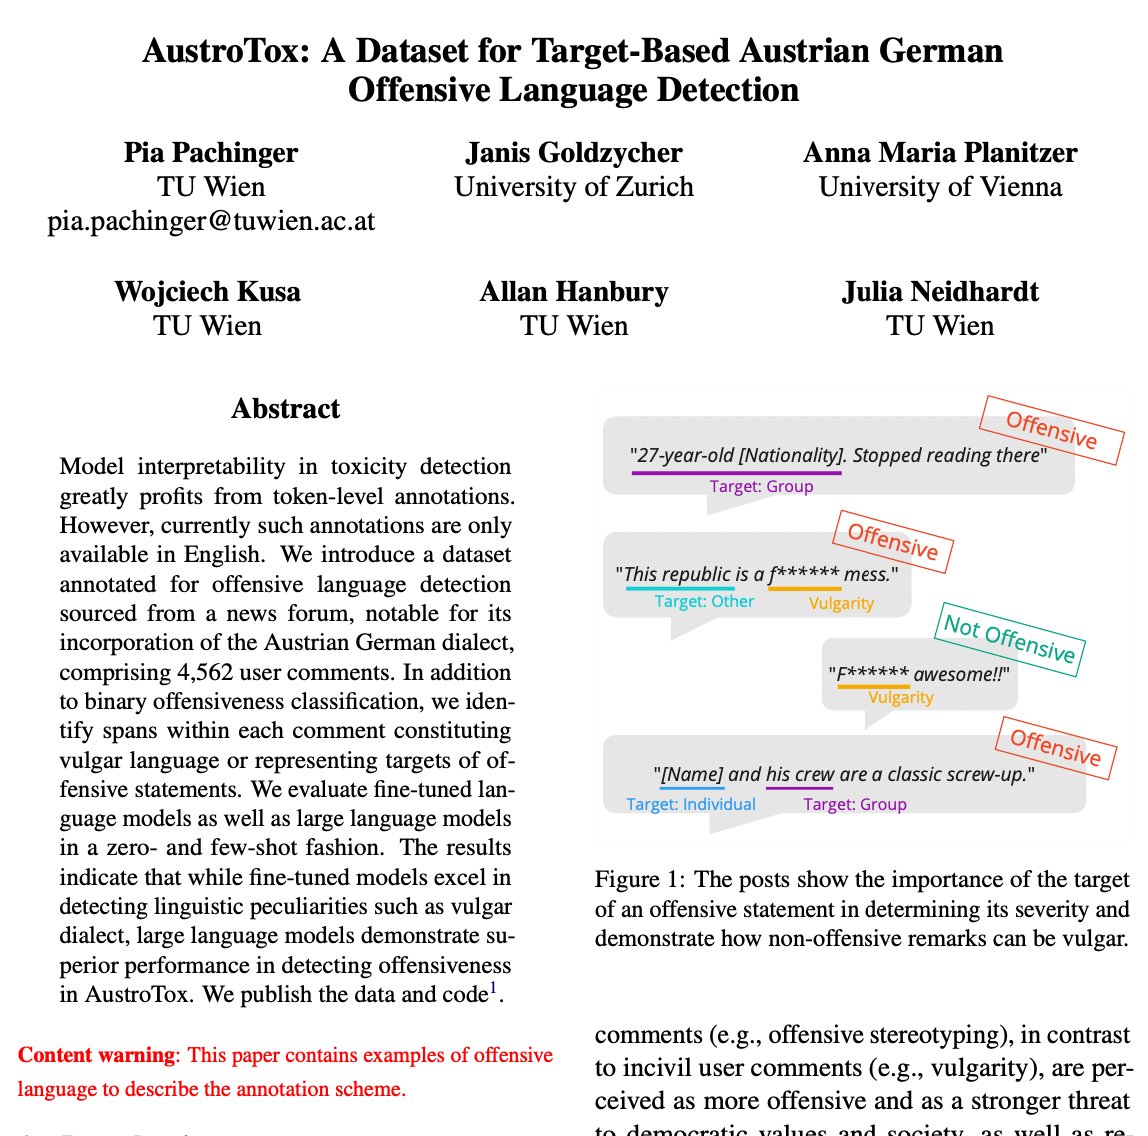
I will be talking about our paper on AustroTox, the first German language resource on topics related to toxicity containing span annotations, on Monday at the @aclmeeting findings poster session 1 (12:45-13:45). Come see me at the poster!
How can democracies counteract misinformation from autocracies? We analyze the EU's unprecedented ban on RT and Sputnik and find that it decreased the spread of pro-Russian propaganda on social media, but only shortly.
Excited to see our work on @voxeu ! https://t.co/iDB76mPhVz
🥁Outstanding paper of #WOAH2024🥁
🏆"The Uli Dataset: An Exercise in Experience Led Annotation of oGBV" by Arnav Arora et al.
Congrats to all the authors! 👏🏻
Interested in target-based offensive language detection of Austrian German? Published in Findings of the @aclmeeting 2024, @PiaPachinger & colleagues /@AMPlanitzer introduce the “AustroTox” dataset and evaluate fine-tuned and LLMs performance. Data & Code: https://t.co/1IqryWwhdR
✨Improving Adversarial Data Collection by Supporting Annotators: Lessons from GAHD, a German Hate Speech Dataset: We introduce GAHD, a German adversarial hate speech dataset, and evaluate methods for efficiently collecting diverse, adversarial examples.
I‘ll be presenting this paper as a poster at #NAACL2024 today in an hour, from 11:00 to 12:30. Come by to discuss hatespeechXadversarial data collection!
New paper at #NAACL2024 🥳
We present GAHD, an 11k German Adversarial Hate speech Dataset 📜 and show that mixing annotator support strategies for finding adv. examples leads to a more effective dataset!
Great collab with @paul_rottger and @center_text!
Highlights below ⬇️
For this week's @MilaNLProc reading group, @jagoldz presented "Synthetic Data Generation with Large Language Models for Text Classification: Potential and Limitations" by Zhuoyan Li et al.
Paper: https://t.co/stoCrstQOL
#NLProc#ReadingGroup
Can you trick our super-robust model trained on GAHD? 👀 https://t.co/b7jkl8CmPA
GAHD on GitHub: https://t.co/BnnMINLQzC
GAHD on 🤗: https://t.co/Eh0ZoMQJUA
New paper at #NAACL2024 🥳
We present GAHD, an 11k German Adversarial Hate speech Dataset 📜 and show that mixing annotator support strategies for finding adv. examples leads to a more effective dataset!
Great collab with @paul_rottger and @center_text!
Highlights below ⬇️