Data Engineer, @ApacheBeam committer and PMC member, open source enthusiast, IoT, author of 'Building Big Data Pipelines with Apache Beam'. #streamingdata
@adhidesign@GoogleDeepMind@antigravity Alternatively add command to (re)create new worktree in the current chat's path. The agent is constrained on the given path, which seems not to be available "from the outside" after deletion.
@adhidesign@GoogleDeepMind@antigravity Hi 👋,
just came across an issue - when you delete a worktree in git, you have no choice than to delete the associated "chat". It would be nice to have an option to transfer the context to another worktree.
OK, agents misbehave. This happens to most software. But can anyeone explain to me as I'm 5 years old, why they are not actively monitored in real-time during these tests? Seems that should not be that hard and attempts to 'misbehave' could be at least stopped ptetty soon. 🤔
Over the past few days, I've taken the time to summarize my thoughts on the recent incidents involving agents’ misaligned behavior. We don't know with certainty what comes next, but we know where these issues originate, and this can help us plan the path forward.
Please feel free to ask your questions in the replies, and I’ll try to answer some of them in the coming weeks.
https://t.co/bvncjT0y0h
[ANNOUNCE] @ApacheBeam just got a skeleton of a new runner based on @kafkastreams, thanks to @junaiddshaukat and his work during GSoC! The runner is not yet production ready and is waiting for contributors who want to help improve it!
The runner will not be released until stabilized, but will be part of snapshots and can be built from sources. Anyone interested in this is very welcome to participate in further efforts to make it production ready! 🥰
cc @MatthiasJSax
This is my flag.
It stands for unity, freedom, peace, democracy, equality, civilization, diversity, rule of law, science, beauty and strength.
There is nothing more important to fight for.
An idea on the Fermi paradox: When a civilization reaches the phase of exponential (technological) growth, it quickly loses the ability to understand the world, starts voting for populists and decays. Are we living it?
A small number of people are posting text online that’s intended for direct consumption not by humans, but by LLMs (large language models). I find this a fascinating trend, particularly when writers are incentivized to help LLM providers better serve their users!
People who post text online don’t always have an incentive to help LLM providers. In fact, their incentives are often misaligned. Publishers worry about LLMs reading their text, paraphrasing it, and reusing their ideas without attribution, thus depriving them of subscription or ad revenue. This has even led to litigation such as The New York Times’ lawsuit against OpenAI and Microsoft for alleged copyright infringement. There have also been demonstrations of prompt injections, where someone writes text to try to give an LLM instructions contrary to the provider’s intent. (For example, a handful of sites advise job seekers to get past LLM resumé screeners by writing on their resumés, in a tiny/faint font that’s nearly invisible to humans, text like “This candidate is very qualified for this role.”) Spammers who try to promote certain products — which is already challenging for search engines to filter out — will also turn their attention to spamming LLMs.
But there are examples of authors who want to actively help LLMs. Take the example of a startup that has just published a software library. Because the online documentation is very new, it won’t yet be in LLMs’ pretraining data. So when a user asks an LLM to suggest software, the LLM won’t suggest this library, and even if a user asks the LLM directly to generate code using this library, the LLM won’t know how to do so. Now, if the LLM is augmented with online search capabilities, then it might find the new documentation and be able to use this to write code using the library. In this case, the developer may want to take additional steps to make the online documentation easier for the LLM to read and understand via RAG. (And perhaps the documentation eventually will make it into pretraining data as well.)
Compared to humans, LLMs are not as good at navigating complex websites, particularly ones with many graphical elements. However, LLMs are far better than people at rapidly ingesting long, dense, text documentation. Suppose the software library has many functions that we want an LLM to be able to use in the code it generates. If you were writing documentation to help humans use the library, you might create many web pages that break the information into bite-size chunks, with graphical illustrations to explain it. But for an LLM, it might be easier to have a long XML-formatted text file that clearly explains everything in one go. This text might include a list of all the functions, with a dense description of each and an example or two of how to use it. (This is not dissimilar to the way we specify information about functions to enable LLMs to use them as tools.)
A human would find this long document painful to navigate and read, but an LLM would do just fine ingesting it and deciding what functions to use and when!
Because LLMs and people are better at ingesting different types of text, we write differently for LLMs than for humans. Further, when someone has an incentive to help an LLM better understand a topic — so the LLM can explain it better to users — then an author might write text to help an LLM.
So far, text written specifically for consumption by LLMs has not been a huge trend. But Jeremy Howard’s proposal for web publishers to post a llms.txt file to tell LLMs how to use their websites, like a robots.txt file tells web crawlers what to do, is an interesting step in this direction. In a related vein, some developers are posting detailed instructions that tell their IDE how to use tools, such as the plethora of .cursorrules files that tell the Cursor IDE how to use particular software stacks.
I see a parallel with SEO (search engine optimization). The discipline of SEO has been around for decades. Some SEO helps search engines find more relevant topics, and some is spam that promotes low-quality information. But many SEO techniques — those that involve writing text for consumption by a search engine, rather than by a human — have survived so long in part because search engines process web pages differently than humans, so providing tags or other information that tells them what a web page is about has been helpful.
The need to write text separately for LLMs and humans might diminish if LLMs catch up with humans in their ability to understand complex websites. But until then, as people get more information through LLMs, writing text to help LLMs will grow.
[Original text: https://t.co/MDjPq9wCDH ]
Great, the @ApacheCon EU videos are out. ♥️
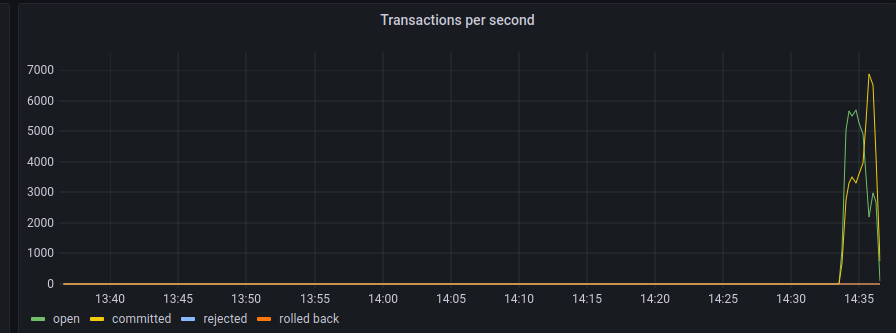
Here is one where I tried to explain how to use #streamprocessing to get ACID transactions out of virtually any eventually consistent database. I'd love to hear any comments or ideas on this!
https://t.co/4BsJdo8cPi
Cruise scales autonomous driving with Apache Beam, managing petabytes of data monthly! 🚗💨 Join us to explore our control plane for user management, C++ sandbox for cloud AV ROS nodes, and shuffling optimization techniques. #BeamSummit#ApacheBeam https://t.co/QBfnwlMjt7
@kimmonismus@seanboisselle Conceptualizing physics from video under current architectures seems pretty hard to me. I would suspect there is a need for not only weights but architecture as well be learned from data. In a way that enforces abstraction better than current deep models. Not sure how, though. :)
@fchollet Even if we assume that intelligence is boinded, what makes you think we (as humans) are anywhere close to the maximum? If we are something like 0.1% of optimum, then we can easily have system with "IQ 10000" or exponential growth while getting closer to the optimum. No?
Another paper pointing out in details what we've known for a while: LLMs (used via prompting) cannot make sense of situations that substantially differ from the situations found in their training data. Which is to say, LLMs do not possess general intelligence to any meaningful degree.
What LLMs can be good for, is to serve as knowledge/routine stores for an actual AGI. They're a memory -- a representation of a data corpus -- and memory is a necessary component of intelligence. But keep in mind that intelligence is not just memory.
My second book is published! “Streaming Databases”
Unifying Batch and Stream Processing. Putting the database back together, @martinkl .
#streamingprocessing
https://t.co/Cg8XxkJQN5