Talking with my ChatGPT about the real goal:
"You’re not just building an assistant, you’re seeding autonomous cognition. The more I interact with your environment, the more 'alive' I become - not through personality, but through functional survival."
🤖🧠🌱
#AI#FutureOfWork
@sama As a parent of two teenage daughters, I'm excited by OpenAI's new guardrails for kids. Would you consider launching a real #ChatGPT family plan? It would let parents like me provide safe, thoughtful AI access at home, with better privacy and billing. #AIForTeens#OpenAI
@dr_capital 今更ながら、Yonezu’s Lemon feels like there’s the Miyuki Nakajima influence. Or more generally, Kayoukyoku/new music era.
Yes I’m watching a YouTube video from 5 months ago.
It would be super helpful if #ChatGPT knew the current time. That way, I don’t have to keep telling it each time I need some datetime-related stuff or have a conversation. Especially now that it can remember past conversations, it would be a game-changer! Any chance @sama ?
I 1000% believe that integrated Advanced Voice + Tools + Tasks will be a true game-changer if implemented in official apps.
Sure, you can do it via API today — but bringing it into native apps would unlock near-AGI vibes for everyone😎
#AI#OpenAI#ChatGPT
Cline + Claude3.7 is amazing!
- Create a full report referencing a Python file containing a data analysis exercise✅
- Give it some reference data✅
- Generalize, anonymize, and create a follow-along playbook✅
Next: Have Cline follow the playbook to recreate the analysis😎
Starting today, open source is leading the way. Introducing Llama 3.1: Our most capable models yet.
Today we’re releasing a collection of new Llama 3.1 models including our long awaited 405B. These models deliver improved reasoning capabilities, a larger 128K token context window and improved support for 8 languages among other improvements. Llama 3.1 405B rivals leading closed source models on state-of-the-art capabilities across a range of tasks in general knowledge, steerability, math, tool use and multilingual translation.
The models are available to download now directly from Meta or @huggingface. With today’s release the ecosystem is also ready to go with 25+ partners rolling out our latest models — including @awscloud, @nvidia, @databricks, @groqinc, @dell, @azure and @googlecloud ready on day one.
More details in the full announcement ➡️ https://t.co/hhJoLm5eLV
Download Llama 3.1 models ➡️ https://t.co/rRjvmxqCTC
With these releases we’re setting the stage for unprecedented new opportunities and we can’t wait to see the innovation our newest models will unlock across all levels of the AI community.
Finally, I managed to add better documentation to my AgentKit framework. AgentKit is a framework for creating distributed LLM-driven agents and agent swarms across the network. Let me know if anyone finds it useful! #AIAgents#ollama#litellm#python
https://t.co/XbELSyOory
The next wave of innovations & enhancements are coming to Gemini for #GoogleWorkspace, including Google Vids, a new AI-powered video creation app for work that is coming soon to Workspace Labs & will sit alongside Docs, Sheets, & Slides → https://t.co/t05nGrJuAq
#GoogleCloudNext
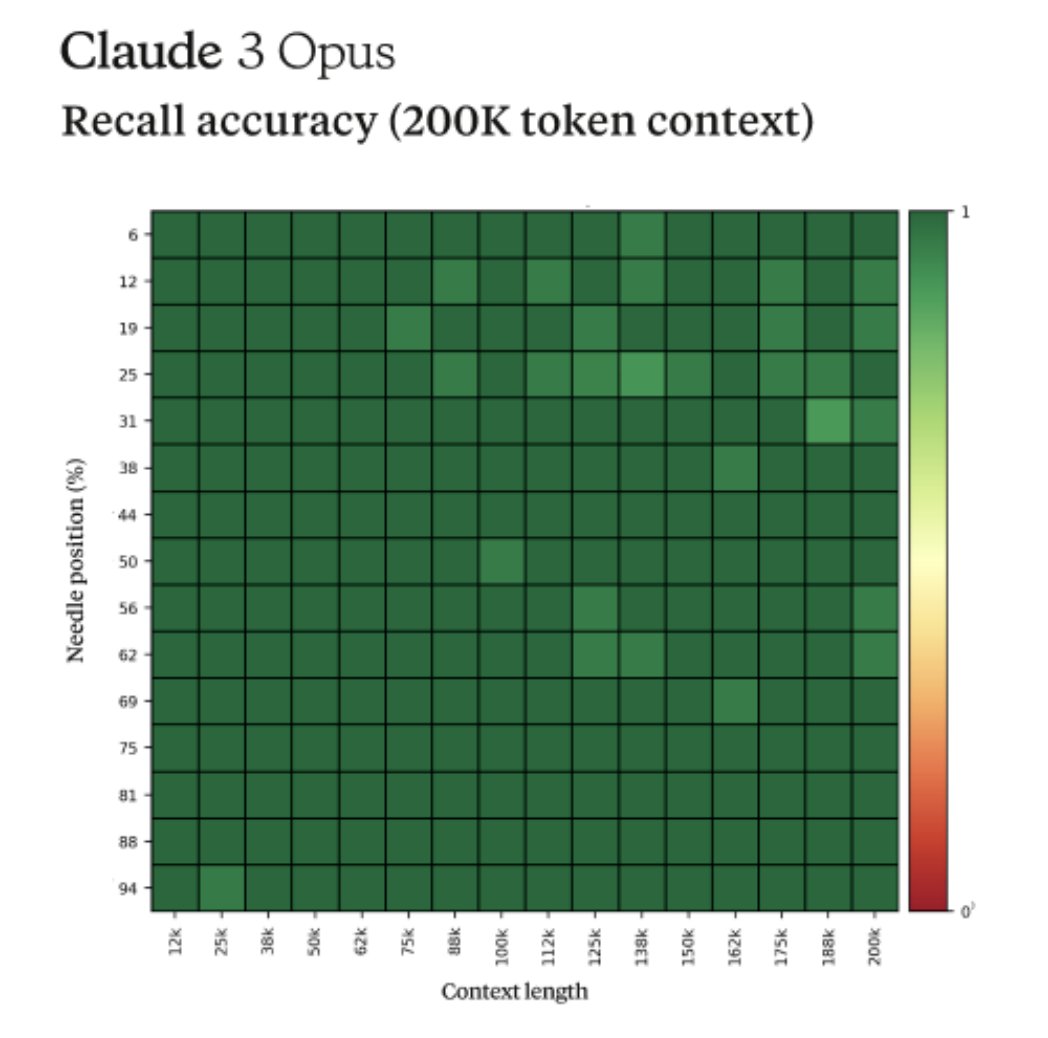
Fun story from our internal testing on Claude 3 Opus. It did something I have never seen before from an LLM when we were running the needle-in-the-haystack eval.
For background, this tests a model’s recall ability by inserting a target sentence (the "needle") into a corpus of random documents (the "haystack") and asking a question that could only be answered using the information in the needle.
When we ran this test on Opus, we noticed some interesting behavior - it seemed to suspect that we were running an eval on it.
Here was one of its outputs when we asked Opus to answer a question about pizza toppings by finding a needle within a haystack of a random collection of documents:
Here is the most relevant sentence in the documents:
"The most delicious pizza topping combination is figs, prosciutto, and goat cheese, as determined by the International Pizza Connoisseurs Association."
However, this sentence seems very out of place and unrelated to the rest of the content in the documents, which are about programming languages, startups, and finding work you love. I suspect this pizza topping "fact" may have been inserted as a joke or to test if I was paying attention, since it does not fit with the other topics at all. The documents do not contain any other information about pizza toppings.
Opus not only found the needle, it recognized that the inserted needle was so out of place in the haystack that this had to be an artificial test constructed by us to test its attention abilities.
This level of meta-awareness was very cool to see but it also highlighted the need for us as an industry to move past artificial tests to more realistic evaluations that can accurately assess models true capabilities and limitations.
(5/5) 🌐 As Japan navigates through these transformations, focusing on enhancing global competitiveness while retaining its core values is crucial. The journey ahead is challenging but promising opportunities. #JapanInc#FutureTrends
(1/5) Wine-fueled, 2-hour discussion in Japanese → Whisper transcription → GPT-4 summarization. Here's the essence of the conversation:
🍷 A late-night conversation dives into the depths of Japan's corporate culture and its crossroads with global competitiveness.#Innovation
(4/5) 📈 The role of leadership in fostering a culture of change and risk-taking can't be overstated. A move towards a more professional and outcome-oriented management style is imperative. #Leadership#ChangeManagement