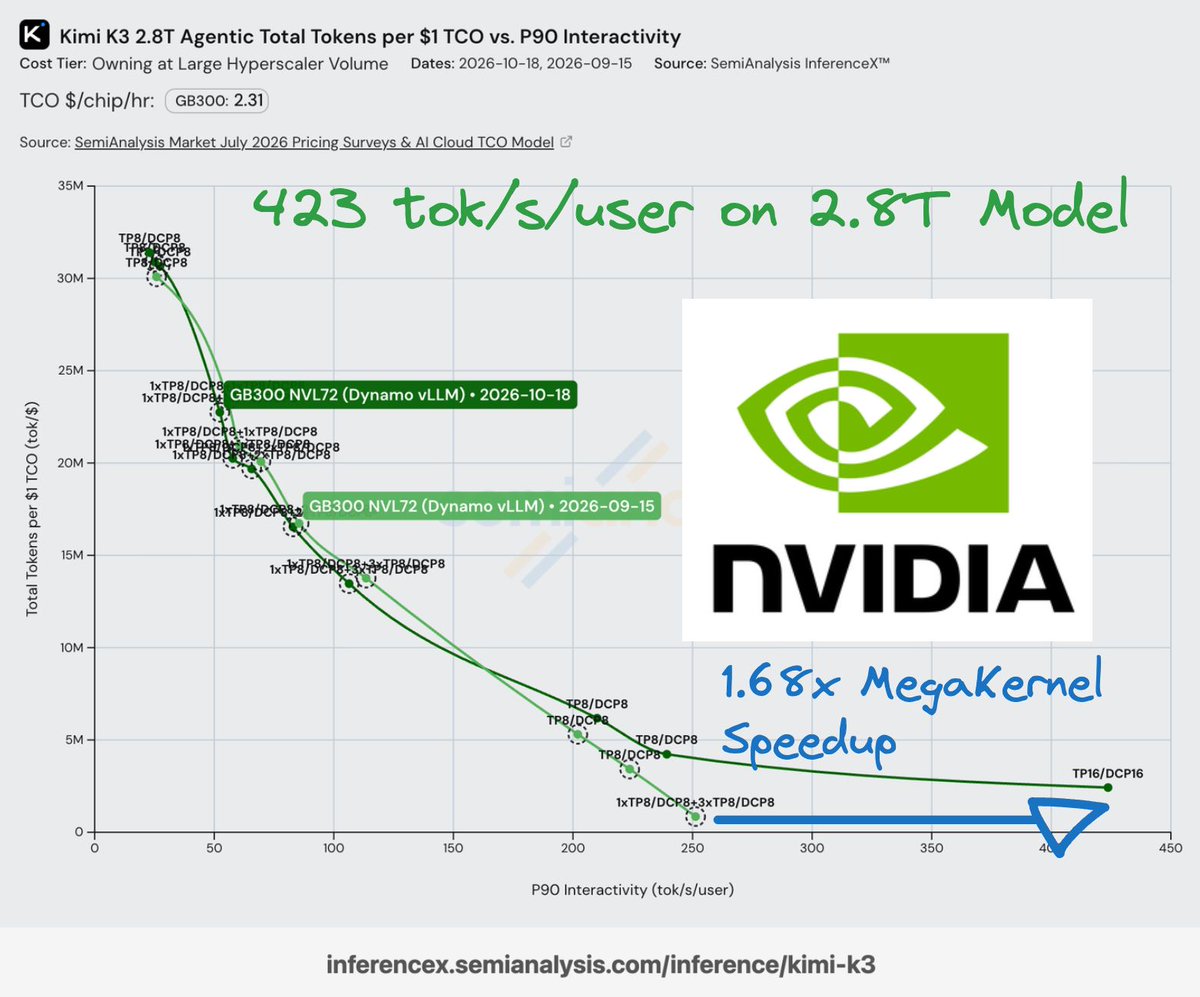
BREAKING NEWS🚨: NVIDIA has just achieved 423 tok/s/user 🚀 on the 2.8T Parameter Kimi K3 model via a new upstream vLLM optimization. 1.68x Faster on the Same Hardware!
This was done by NVIDIA CentML's Benjamin, who wrote NVIDIA's new decode-specialized kernels in Cute DSL via aggressive Megakernel fusion. This is a 12,000 LoC Megakernel and is the future of advanced AI-assisted kernel generation. NVIDIA is already working on DeepSeekv4.1 and other models for vLLM too.
Someone should give this NVIDIA 10x engineer a raise for this great new major feature!
these just appeared in the OpenAI API:
aurora-blue-alpha
aurora-green-alpha
aurora-red-alpha
there was an openrouter model called aurora-alpha earlier this year which was likely GPT-5.3-Codex-Spark
so these could also be specialized codex coding models, or high-speed inference versions of GPT-6 models
BREAKING NEWS🚨: NVIDIA has just achieved 423 tok/s/user 🚀 on the 2.8T Parameter Kimi K3 model via a new upstream vLLM optimization. 1.68x Faster on the Same Hardware!
This was done by NVIDIA CentML's Benjamin, who wrote NVIDIA's new decode-specialized kernels in Cute DSL via aggressive Megakernel fusion. This is a 12,000 LoC Megakernel and is the future of advanced AI-assisted kernel generation. NVIDIA is already working on DeepSeekv4.1 and other models for vLLM too.
Someone should give this NVIDIA 10x engineer a raise for this great new major feature!