Most AI workflows die at week three, not at the demo. I'm documenting the ones that don't: where AI leverage compounds, where it quietly costs more than it saves, and what the real constraint turns out to be. What's the one you dropped after the novelty wore off?
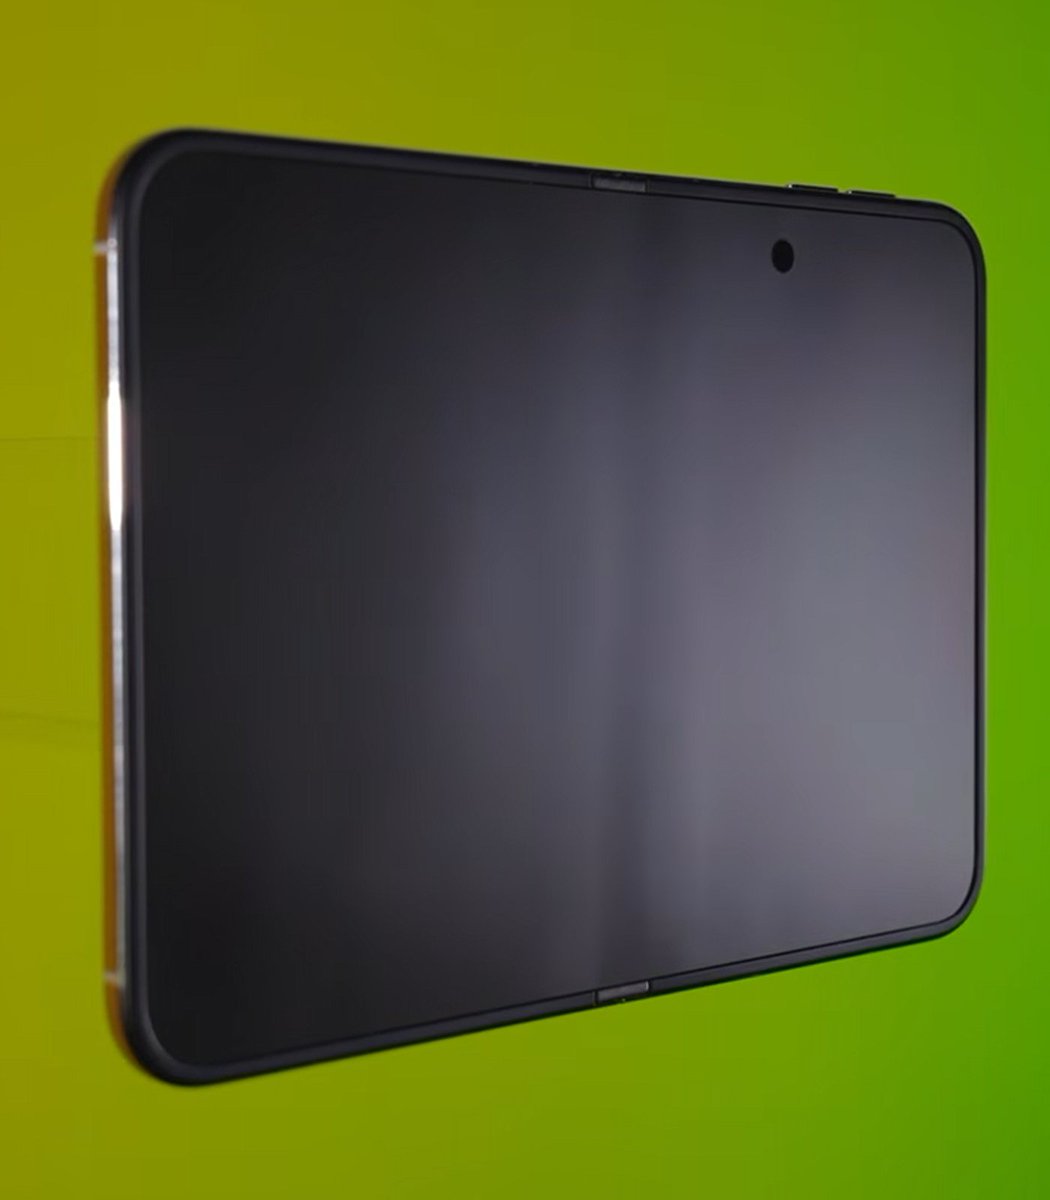
10,000 folds is the test. Samsung's published rating is 500,000 for the display in the Galaxy Z Fold7, which it translates to over 10 years at about 100 folds a day. Apple lists IP68 and a hinge with more than 100 components for the Duo, and no fold-cycle number.
The other test today: Joanna Stern put 32,000 folds through her review unit over four nights, case on, the machine opening flat but not closing all the way. A push-pull gauge read the hinge stiffer afterward than before.
Read the crease photo, then ask for the number behind it. What would you want Apple to publish before you buy one?
GitHub Next's PDD Kit has you approve a Verus spec before the code is written, then the verifier proves the generated Rust meets it for every input, so the human reads the spec instead of the diff. Where a proof isn't possible it falls back to tests and computer-use agents. The guarantee is set function by function. That's the boundary worth drawing before the agent writes the file: which parts of your service get a proof, and which stay on tests. which functions in your app could you actually write a spec for?
How do you _guarantee_ your agent's code is correct? You prove it.
Introducing Proof Driven Development Kit (PDD Kit) from @MSFTResearch.
PDD Kit helps turn your plan into a formal spec, then proves the agent's code meets that spec for every input. No vibe verification. PDD Kit is integrated with @GitHubNext's Chopin, so you can plan as a team.
PDD Kit takes an app's login flow from intent to a verified pull request:
It discusses your code, infers your intent as it goes, and proposes a formal spec in Verus, a proof language for Rust.
Once you approve the spec, the Verus verifier automatically proves the code meets it.
Where proof isn't possible, it falls back to empirical verification with tests and computer-use agents (CUAs).
It works on Rust today. No new language, no change in how you produce the underlying code, making formal methods more accessible.
The goal is a verified software factory, where engineers review specifications instead of code.
Come see it in action at GitHub Universe, Oct 28–29. Swing by the Speakeasy and ask for GitHub Next!
@abdullababakre a cloud phone is a new device to every app on it. banks, whatsapp, instagram all fire a step-up or a login code right when the agent needs to act. do rented phones keep one stable device identity across sessions, or does every run look like a fresh login?
Apple Music's new logo came out of a shallow bath of mineral oil. Fred again.. and NEST Acoustics wrote a short composition, played it through a transducer, and Apple filmed the ripples; that footage is the raw material for the mark.
what's worth stealing for a brand system is the source. single notes were played one at a time, so each one has its own recorded shape, which means the identity can be re-derived from the track instead of redrawn by hand.
did the full composition get released anywhere, or just the clip in the reveal?
Anthropic put a breaking change behind a date instead of a model launch. API version 2026-10-21 removes temperature, top_p and top_k: send any of them and every model returns a 400. Not deprecated, not quietly ignored, a hard error.
That moves where the risk sits. Nothing changes until you send that anthropic-version header, because Anthropic preserves the input and output parameters of whichever version you pin. The upgrade becomes a diff you choose, not a surprise that arrives with a library bump.
Two things worth doing before you move. Pin the header in one place, since the SDKs set it for you and a default is not a pin. Keep a request fixture that still sends temperature, so your CI fails on the upgrade instead of your users doing it.
Then ask what temperature was buying you. On extraction and routing work it usually tuned nothing you could measure, and deleting the knob is cheaper than tuning around it.
Three open-source anatomy datasets went in, and out came a body a student can operate. Toggle a layer off, isolate a muscle, zoom inside a beating heart while it pumps.
If you're building a learning tool, copy the toggle. One structure at a time, in motion, does more than a labelled diagram — the learner assembles the 3D picture themselves.
Nothing in it needed new data. The datasets were already public, and the model did the assembly and the viewer.
Gemini 4 Argon combined three open-source datasets to build an interactive 3D visualization of human anatomy.
Toggle different layers in motion, isolate muscles, or zoom inside a beating heart.
Dilum Sanjaya turned Arduino into an interactive 3D board where a beginner wires the LED, runs the code, and watches it work. 11 free lessons, built with Opus 5.5, and 9,527 people bookmarked it.
The shaping is the transferable skill. Pick a subject beginners find intimidating, then cut it into steps small enough that nothing has to be explained twice. The model writes the lessons; deciding what step one is stays with whoever actually knows the subject.
What's a skill you'd teach this way? 🔧
Hardware looks scary until you break it down into small steps. So I built an app that takes you through Arduino one circuit at a time.
Made with Opus 5.5
https://t.co/1AL82geKtQ
The USB-C Apple Pencil works on the iPhone Duo's inner and outer displays once iOS 27.2 lands, and it's already live in the release candidate Apple seeded Monday. The public build is expected next week.
That makes the Duo the first iPhone that officially takes a Pencil, and per MacRumors it draws, annotates and scrolls on both screens inside supported apps.
Duo owners on the RC: does the Pencil track as well on the outer display as it does on the inner one?
Claude Duet went live today as Anthropic's research preview of a proactive agent. It surfaces what needs your attention, keeps working while you step away, and checks with you before it acts on your behalf.
If you already pay for Claude the setup cost is nothing, since Duet runs on Opus 5.5 and inherits the memory, skills and connected apps in your account. Anthropic says it never sees your passwords, and that it can still misjudge what's urgent.
US waitlist only, Pro and Max plans. What's the first task you'd hand an agent that acts while you're not watching?
We’re opening a research preview of Claude Duet, a new app where Claude works as a proactive agent.
It comes to you with what needs your attention, completes tasks you ask of it, keeps working when you step away, and checks with you before it acts on your behalf.
levelsio published the prompt that built his GTA San Andreas mission, and almost none of it is about the mission. Most of it is environment repair: downgrade the game to v1.0, back up every file first, then verify gta3.img came out at exactly 940,064,768 bytes with CRC32 c8ccf06f.
That's the shape for any legacy target. There's no test suite to lean on, so the pinned version and the checksum become the test suite, and changing one thing at a time is how you find out which change broke it.
What's the oldest thing you'd point an agent at?
Here is the prompt to make your own GTA San Andreas mission on MacOS, just paste it in your clanker, you can change the mission of course to your own story:
You are helping me build a custom story mission for GTA San Andreas (classic PC version) running on macOS through CrossOver. Work step by step, check each step works before moving on, and back up everything before changing files.
GOAL
A playable mission called "Vibe Coded". CJ walks into a marker in San Fierro, drives to a diner, sits at a desk with his co-founder and "vibe codes" a startup called Vibes AI in a minigame. Then he drives to an investor office and pitches. The investors invest $10,000,000 and the mission passes. All dialogue is voiced and subtitled.
PART 1: PREPARE THE GAME
1. Back up the full game folder and the save folder ("Documents/GTA San Andreas User Files") before touching anything.
2. Downgrade the game to v1.0 US. The modding tool CLEO only works on v1.0, and the Steam and Rockstar Launcher versions are newer. Use Jetpack Downgrader (open source, on GitHub), which supports the Rockstar Launcher version. You don't need its Windows GUI. Its package contains the full v1.0 exe (game.jpp is a zip holding it) plus JojoDiff binary patches for 15 data files. Apply each patch with its bundled patcher.exe, run through CrossOver's wine command line. Syntax: patcher.exe original patch output. The files are anim.img, gta_int.img, gta3.img, TrakLkup.dat, nine audio streams, script.img and main.scm. Verify: gta3.img should be 940,064,768 bytes with CRC32 c8ccf06f, and main.scm should be 3,079,599 bytes.
3. Install CLEO 5 (the version bundled with Silent's ASI Loader) and SilentPatch. SilentPatch is required, because without it v1.0 refuses to start on a Mac with "Cannot find 800x600x32 video mode".
4. Make the save compatible. v1.0 uses v1 scripts, so a save from the newer versions won't load. Use https://t.co/R4yTH4wx5g to download a save from the right point in the story (we used one right after "Are You Going To San Fierro?"), converted to v1. Put it in a free slot without overwriting existing saves.
5. Launch gta_sa.exe directly, not through the Rockstar Launcher, which may undo the downgrade. Create a CrossOver shortcut for it inside the bottle. Don't put shortcut files on the Mac desktop.
PART 2: MAC/CROSSOVER GOTCHAS (IMPORTANT)
- The game crashes on launch if a settings file (gta_sa.set) saved by a previous session exists. Delete it before every launch. We made the shortcut run a small .bat that deletes it and then starts the game. The downside is that in-game settings reset each launch.
- The game stops loading whenever its window isn't the active window. After launching, keep the window focused (Cmd+Tab to it) even if it looks black or invisible.
- Force-quitting leaves orphaned Windows processes in the bottle, which silently block future launches. If the game won't start, kill every process in the bottle (or use CrossOver's Force Quit / Restart Bottle), then launch again.
- If the camera spins with mouse and keyboard, set the Wine registry value HKCU\Software\Wine\DirectInput MouseWarpOverride = force. Don't enable Retina mode, because it broke launching.
- Windowed mode through dxwrapper produced an invisible window on the Mac, so we removed it. Film the full-screen game with Cmd+Shift+5 instead.
PART 3: WRITE THE MISSION
1. Write the mission in Sanny Builder 4 syntax, in GTA SA v1.0 SBL mode, as a CLEO script (.cs). Compile it with Sanny Builder's command-line option (sanny.exe --no-splash --mode sa_sbl --compile input.txt output.cs), run through wine. Compile in a different CrossOver bottle from the game's, so compiling never disturbs a running game. Put the .cs file in the game's cleo folder. It loads whenever a save is loaded.
2. Use real data from the game files, never guesses:
- Get interior coordinates and interior IDs from the "enex" sections of the game's .ipl map files. We used the SF diner (DINER2, interior 5) and the Planning Department office (PAPER, interior 3).
- Get object model IDs from the .ide files: office chair kb_swivelchair1 (1714), office desk officedesk1 (2008, has a computer on it, top at 0.8 m), computer PC_1 (2190). There is no laptop model in the game.
- Measure object sizes by reading vertex bounds from the .dff models inside gta3.img and gta_int.img.
- Verify animation names by parsing the .ifp files. We used OFF_Sit_Type_Loop from INT_OFFICE, the prtial_gngtlk talking animations and the business handshake from GANGS, and shout_01 from ON_LOOKERS.
3. Placement rules that took several tries to get right:
- The enex coordinates are not floor height. Find the real floor with get_ground_z_for_3d_coord once collision has loaded (after load_scene and about a 1 second wait).
- set_char_coordinates already adds the ped's standing height (about 1 m). Pass the floor height itself, not floor + 1, or characters float in mid-air.
- A frozen character in mid-air plays a falling pose instead of its animation. Freeze characters only once they're on the floor.
- The sitting animation lowers the body by 0.403 m (read from the .ifp file), which lands the hips on a 0.49 m chair seat.
4. Mission flow:
- Trigger: a $ blip and marker outside the Doherty garage. Start only when not already on a mission, then set $ONMISSION = 1.
- Diner: fade out, teleport inside, place the desk, chairs, computer and co-founder, play the typing animation, set a fixed camera, fade in.
- Minigame: draw a fake laptop screen with draw_rect and display_text_formatted. Tap SPACE to prompt the AI and raise a progress bar. A scrolling agent log appears with jokes (spawning subagents, context compaction, auto-approved rm -rf, deleting the tests). Random red bugs appear, and you have 4 seconds to press Y to accept the AI fix. Each bug has its own funny fix reply. Failing costs 12% progress.
- At 100%: "SHIPPED!", teleport outside, and a blip marks the investor office downtown.
- Office pitch: teleport in, spawn three investors, then three questions with Y or N answers. After each choice, show what CJ said ("CJ: ...") before the investor reacts. Then the $10M offer. Answering N triggers a counter-offer gag where the investors panic and cave.
- End: handshake, fade out, teleport outside, add $10,000,000, play the mission-passed tune, show MISSION PASSED.
- Fail: if the player dies or gets busted, clean up all spawned objects and characters and show MISSION FAILED.
5. Sanny Builder pitfalls: some variable names clash with built-in names (for example "blip" and "fx"), so rename them. There is a limit on local variables, so reuse them. Check the compiler log after every build.
PART 4: VOICE ACTING
1. Write a list of every spoken line, one file per line, with clear filenames (for example vc_02_q1, cj_01_q1_yes, cofounder_01). Spell out numbers for text-to-speech.
2. Generate the voices with text-to-speech, using original or designed voices
3. Process the clips with ffmpeg: trim leading and trailing silence, cut any extra takes, normalize loudness so all characters play at the same volume, and convert to mono mp3.
4. Transcribe the final clips (we used Whisper locally) and adjust the subtitles to match exactly what was said.
5. Play the clips with CLEO 5's audio plugin (https://t.co/5S72Zv8zaS.cleo): load_audio_stream with "cleo:\vibes\filename.mp3", play it, show the subtitle for exactly the clip's length, then remove the stream. If a clip fails to load, show the subtitle without sound instead of crashing.
6. Optional: real character lines can be pulled from the game's own audio. The file audio/SFX/SCRIPT holds 218 banks of raw 16-bit PCM speech (find them via PakFiles.dat and BankLkup.dat), about 6,800 clips. Extract them to WAV and transcribe them to search for specific lines.
PART 5: TESTING
After every change, reload the save and play through the changed part. Ask for screenshots when something looks wrong, especially positions and sitting. Change one thing at a time.
Existing apps do run on the Duo from day one, just inside black borders. Apple only lets a build made with the iOS 27.1 SDK resize to fill the inner display, so app teams have to ship that build themselves; the phone cannot do it for them.
That is why Mark's "weeks" timeline holds for the apps you open hourly and stretches for everything else. Go through the apps you actually live in and check which ones have shipped a Duo build already. That list is the phone you are buying.
The iPhone Duo reviews are some of the most brutal I've seen from an Apple product in a long time (Vision Pro aside). But I've been around long enough to remember the iPhone 5, iPhone 6 Plus and iPhone X. The app optimization issue is a non-issue and will be resolved in weeks.
PHP runs an estimated 70% of websites, and OpenAI says its models found critical flaws in it before attackers did. The fix took two months of coordinated work with maintainers, researchers and security vendors, and it needed a change to the PHP engine itself, so this is a version upgrade, not a config toggle.
Every PHP site can upgrade now. OpenAI's own follow-up post packs a Codex skill for checking whether yours is affected: point Codex at that repo and it walks you through it.
Do you know which PHP version your host is actually running?
OpenAI models helped researchers—operating as part of our Patch the Planet initiative—discover critical security flaws in PHP, an open-source programming language used to run an estimated 70% of websites.
Over the past two months, we led a coalition of maintainers, researchers, and security providers to prepare fixes and protections ahead of disclosure. This duration was necessary because the fix was quite intricate and required a major change to the PHP engine. Every site using PHP can now safely upgrade their version to stay secure, in addition to applying mitigations from various security vendors.
Due to the severity of these flaws and PHP’s widespread use, we consider this bug to be one of the most impactful vulnerabilities in recent memory. It also marks a new phase, where AI can find security bugs with internet-scale impact.
This is an example of the Defender’s Window in action: to our knowledge, frontier AI was able to find this vulnerability ahead of attackers, giving defenders time to prepare.
https://t.co/TW3jrSbB3f
Voicy brings in $18k a month and about $11k of that comes back next month.
Kourosh Ghaffari built the voice-typing app for his dad and still works full time as a PM. The gap is lifetime deals: a $260 one-time plan next to an $8.49 monthly, so monthly revenue runs $16k to $20k while MRR sits at $11k, by his own numbers in Starter Story's interview.
Copy the gap down, not the headline. A lifetime sale collects once and then carries a cost that never stops: OpenAI charges $0.006 a minute for Whisper whether that customer pays again or not.
He serves the people dictation tools ignore, older users and anyone who can't type without pain. That's where the 1,400 active subscriptions come from.
how do you plan around a customer who pays once and costs you every month after?
Everything I learned in the last 5 years of being an indiehacker
I hope this article helps someone❤️
It's not luck, it's just learning from your mistakes. https://t.co/2a8wdxCWMw
Look at what they actually bought. 🧬 OpenAI acquired Orchestra Bio, the platform biopharma teams use to coordinate drug development, and says it'll build on Rosalind from there. Drug work is a dozen parties agreeing on the same protocol across years of trials, so the coordination layer is where a model actually gets used. If you're shipping agents into regulated work, that is the door. Own the coordination and the model rides along.
We’ve acquired Orchestra Bio, a platform that helps biopharma teams coordinate the complex process of drug development.
Together, we’ll build on Rosalind, our AI models and tools for life sciences research, to streamline those operations and help new treatments reach patients sooner.
Welcome @ashokaraj_ and team!
https://t.co/vi51OhznQn
Wait, this is the right order! 🧩 agent writes the statechart from your code, then TLA+ goes hunting for event orders you never handled.
the part that used to cost a human naming every state and transition by hand is now the model's first draft, and the checker finally gets something concrete to refute.
and that's where the ugly bugs live: two events arriving in an order your tests never tried.
there's something really cool about asking your agent to draw a statechart (hypothetical example in this image), then using the /create-formal-verification-skill you made with pstack to find bugs through something like TLA+. you can both understand your code better and how the user flow should work, and fix issues users would otherwise see
Ramp went through the off-the-shelf agent harnesses, none of them fit, so they wrote their own. Six agents run on it now. 🔧 A coding agent, a support bot, document OCR, their phone line.
The requirement list says what production actually needs: durability, queueing, compaction, forking. Those four exist for one reason, the job has to survive being left alone. A harness that can't resume mid-task makes you the retry logic.
what's the longest job you've left an agent running with nobody watching?
after much experimentation, we landed on a single set of rails that powers our agentic systems across the company - background agents, async agents, live chat:
1. stack - accounting harness (https://t.co/FP0HUI8zNl)
2. glass - general purpose coworker (https://t.co/Q7X7SGdBE0)
3. inspect - coding agent
4. our support chat bot, Ask Ramp
5. headless agents that do document OCR
6. ramp text (HIRAMP/447-267) agent
works with all models, supports all modern harness features - background tasks, sandboxes, tool hooks, tool search, durability, forking, compaction, queueing, streaming, and observability
laminar, our new harness, sits on top of ramp router, and brings enormous leverage to our agent developers across the company
more info on our blog ->
Anybody can pull a 27B checkpoint on a Saturday. 🛠️ What's rare is an environment your agent can act in, plus a check that scores whether the attempt worked — this Qwen post-train came out of that setup.
And that setup encodes what you actually know about your own work. A model only gets good at what the scoring rewards, so a verifier you trust for one task beats another row on a leaderboard.
Before downloading anything: write down what a correct attempt looks like for the task you'd most want an agent to own, and what a wrong one looks like. That page gives a small model something real to train against, in a domain no lab is going to build for you.
What's the first task where you could actually write down what "correct" means?
Some of the most interesting agent results this year are coming out of post-trains of small open models.
A new RL post-train Qwen3.8-27B model trained with an open-source environments cuts the hallucination rate on AA-Omniscience from 30.4% to 15.1%.
the compressed copy of the mla version fits on my single 24 GB RTX 4090 and holds about 3.5x more context than base Qwen.
It beats GPT 6 Luna-medium on DeepSWE, placing in between Luna 6 medium and high.
scores higher on Terminal-Bench 2.1 while writing a median 23.8K output tokens per solved task, where base Qwen writes 54.9K.
Tried an unreleased version of this model, and really felt the comparative intelligent density, that it writes a lot less.
tops Muse Glimmer 30B and OpenAI’s GPT-6 Luna (high) on Terminal-Bench, τ³-bench, ClawEval and BFCL v4 (Berkeley Function Calling Leaderboard), though Luna still wins DeepSWE at 53.1%.
They also released an MLA version, which is the same model with its 16 full-attention layers converted to multi-head latent attention, which shrinks the memory each token takes from 64 KiB to 18 KiB so far more or longer sessions fit on one GPU.
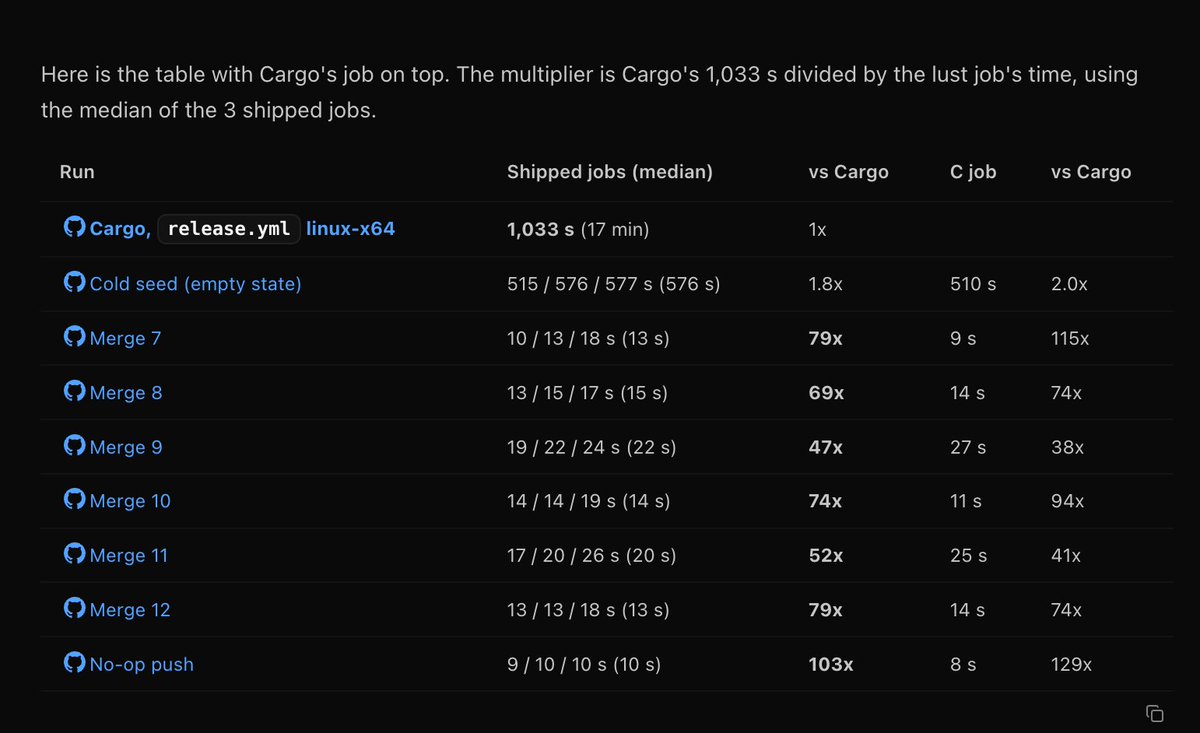
a Cargo alternative that compiles his Rust apps 129x faster 😅 and @theo's first thought was "yeah, and?"
when the cost of trying collapses, "and?" is the honest reaction. a compiler rewrite used to be a career-sized decision; now it's one of ten things you could attempt in a day.
so the useful test changes: does it remove a wait you hit every day. everything else is a demo with good benchmarks.
what would you rebuild first if the rebuild were free?
It's crazy how quick these new capabilities have started to feel normal.
Like I vibe coded a Cargo alternative that compiles my Rust apps up to 129x faster and my immediate thought is "yeah, and?"
This is wild ⚡ a Rust edit can now show up in the program that's already running about 7 milliseconds later, because the build stopped calling the compiler at all.
ra-jit keeps a rust-analyzer database alive in a daemon. rust-analyzer has already parsed, type-checked and lowered the code to MIR, so ra-jit only has to generate machine code for the functions an edit actually touched and splice them into the running process. rustc starts over on every invocation; this one never does.
That 24x is a single function in a Game of Life demo on a 96-core machine. For your project the repo's own table is the better promise: a function edit in ripgrep went 447ms to 90ms, nushell 1.44s to 325ms, and a widely used nushell function 4.75s to 221ms.
What it costs: no borrow checker on this path, so cargo check still runs, live splicing is macOS Apple silicon only for now, and how fast the built programs run against a release build isn't published yet.
Holy shit! 🎶 levelsio cancelled Spotify by having Claude Code write him an Alexa skill that plays his own MP3s out of a Cloudflare R2 bucket. He bought the coffee jazz, drops the files in the bucket, and "Alexa, coffee jazz" plays them.
Two steps stayed manual: build the skill in the Alexa developer console, and add a Routine so "Alexa, coffee jazz" maps to "ask the jukebox to play coffee jazz".
His own read is that the recommendations were the part of Spotify he was actually using on that speaker, and they kept serving him the same tracks. The files were already his.
Plenty of subscriptions are just a playback pipe between files you own and a speaker you own.
It worked
Of course it worked!
It never ever doesn't work right?
I vibecoded my own Spotify that works with Amazon Alexa and plays all my own MP3 music files 😊
Claude Code calls it the 🎶 Jukebox
I put some coffee jazz MP3s (that I purchased) in an R2 bucket, made an Alexa skill in the Alexa Developer Console with help from Claude Code and now it plays it if I ask "Alexa, coffee jazz"
It wrote a package.json and index.js, then I saved and built it on the console. Then I had to manually add a Routine to Alexa so that "Alexa, coffee jazz" became "Alexa, ask the jukebox to play coffee jazz"
It also has Bossa Nova and Lofi and I can just drop music in whenever I want and it auto plays it
Spotify with Alexa was giving me really terrible recommendations of music and always the same and the only thing I used it for was this!
So I guess I can cancel Spotify now too 🙏