Stable maps from drifting neurons: CA1 solves the "representational drift paradox" through coordinated population dynamics.
New preprint w/@AntjeKilias@bartos_marlene@JF_Sauer showing that representational drift isn’t random
https://t.co/ESfIQwAIGt
New paper out 🎉We uncovered time-invariant and cross-subject conserved dynamics of prefrontal cortex in response to repeated threats over multiple days.
With @HMuysers, Hung-Ling Chen, @bartos_marlene and my superviser @JF_Sauer
https://t.co/JXaYeX3aeH
Apparently people start to wear prosthetic fingers, so that surveillance images look like they're generated by Stable Diffusion 😅
The human race is overfitting to the quirks of our AI overlords.
@elsvalente We conducted a workshop with 52 librarians where the perceived 'ethicality' of 8 hypothetical use cases of generative AI in research was rated. Come take a look at our poster (#83) if you're interested!
One of our key sources of human data is no longer fully “human"!
We estimate that 33-46% of crowd workers on MTurk used large language models (LLMs) in a text production task - which may increase as ChatGPT and the like become more popular and powerful.
https://t.co/SJfKjDM6gX
@Larerbloggen Jeg er har stor tro på potensialet innenfor individtilpasset læring.
En stor fallgruve er om skolen ikke makter å omstille seg, slik at vurderingsformer og arbeidsoppgaver enkelt kan kan løses med tankeløs bruk av generativ teknologi.
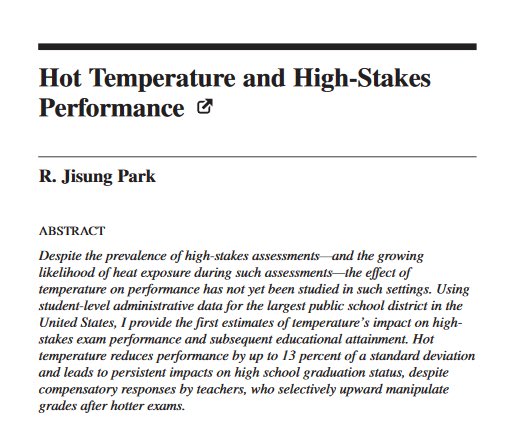
Air conditioning is a vital educational tool.
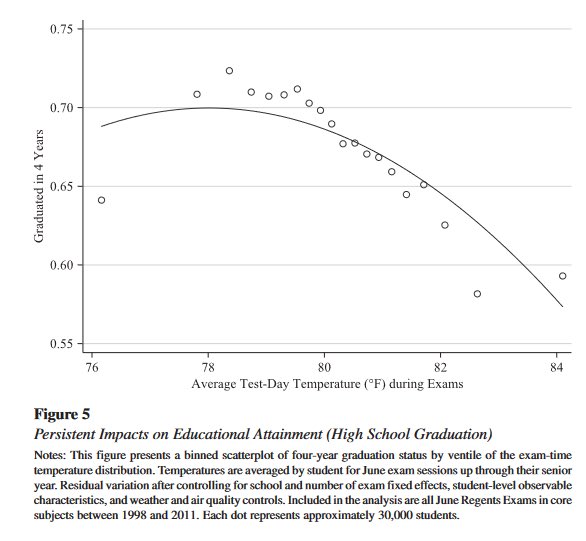
Students do worse when its hot. Over 13 years in NYC alone, "upwards of 510,000 exams that otherwise would have passed likely received failing grades due to hot exam conditions," and these failures delayed or stopped 90k graduations!
Is going to conference presentations worth it?🤔
Yes! It increases citing of
1. Papers you are interested in by 52% (direct effect)
2. Other papers in same session by 51% (serendipity effect)
v2 of paper with @park_soya@ProfNeilT@karger: https://t.co/ijZYBvigWk
(1/4)
@Larerbloggen @Strumke Anbefaler å lese denne. Angivelig et internt dok fra Google der vedkommende maler at bilde av en fremtid hvor de store kommersielle AI aktørene får mindre makt (gitt at de ikke endrer seg i en mer "åpen" retning).
https://t.co/L5cCCTSokA
Keenious is an AI-powered app that will supercharge your academic reading and writing.
It's your personal research assistant inside MS Word and will save you a lot of time and labor.
But most academics don't know much about it.
Here's how to get started on Keenious:
We often use 7-point ratings to measure people's preferences and attitudes (e.g., “how much do you like X?” 1=not at all, 7=very much). In a new paper (just accepted at @APA's Decision; full paper at the end of thread), I demonstrate a problem with such rating measures. (1/n)
Kind of tired of ethics conferences on AI still just saying "we need to talk about ethics and AI," or "ethics is an urgent matter."
I guess we all got that.
Now: what's that going to be looking like?
@Strumke Kan virke som sensasjonaliseringen ikke ligger oss forfatterne. Kanskje en paradoksal effekt av å ha et visuellt flott og "simple-to-get" abstract som dette? Gjør at folk uten kompetansen til å forstå viktige detaljer (som meg selv) fort kan hause opp funnene..
@Strumke Vannvittig kult. Så også denne
tråden tidligere i dag (link). Har hun et poeng i at denne studien er blitt i overkant sensasjonalisert de siste dagene?
https://t.co/JbkiTU28QM
dan, like most AI people, either failed to understand the work, or is lying to make this look impressive
stable diffusion did not read people's minds. he's very conveniently either omitted or left out how this actually works, because it would show that SD didn't do shit
🧵
@GlassHealthHQ Super interesting. Really curious about the references here. How are they related to the generated clinical plan? Is the plan solely based on info from those 5 articles? Also, article #3 is (as far as I can see) behind paywall. Does the model consider full-text or just metadata?
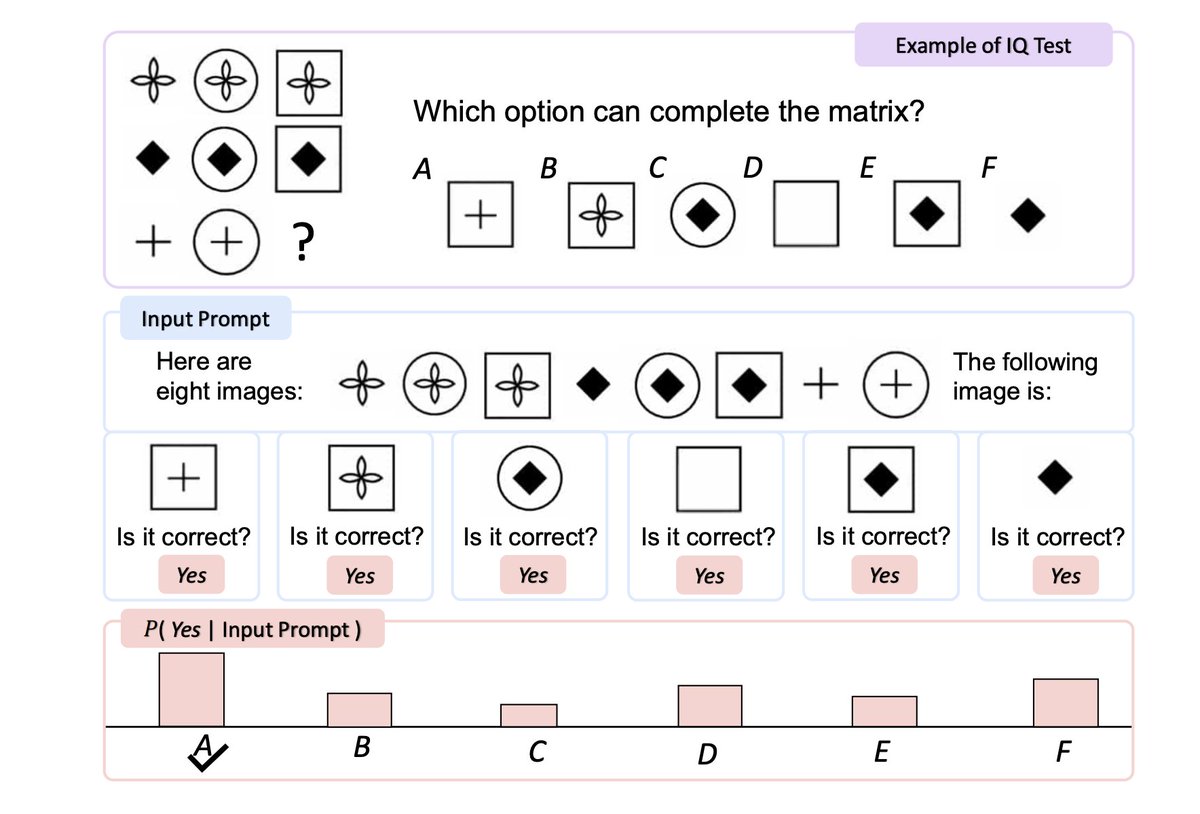
The team also introduced a dataset of Raven IQ test, which diagnoses the nonverbal reasoning capability of MLLMs.
This is an example of Kosmos-1 solving a visual IQ test.
We're proud to reveal a new video demo of Glass AI 2.0🚨
#MedTwitter, we used your >50K Glass AI 1.0 submissions and your feedback to majorly improve Glass AI.
You can anticipate higher accuracy, faster responses, robust and up-to-date clinical plans, and accurate references.