Bredt Family Professor of Computer Science and Engineering, @UMich: Security and privacy, election security, and Internet freedom. Co-founded @LetsEncrypt
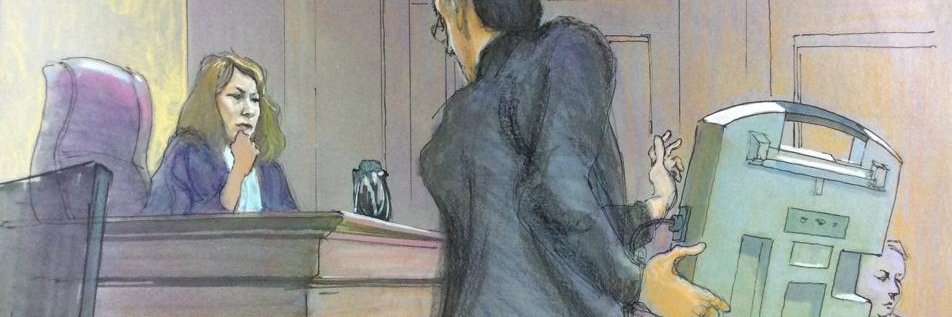
Today, the Federal District Court for the Northern District of Georgia unsealed a 96-page report that I wrote w/ Prof. @_aaspring_ from @AuburnU. It describes serious vulnerabilities we found in Georgia's Dominion ImageCast X ballot marking devices.
https://t.co/4oV0Do45YS
As AI agents learn more about us, the data they accumulate will be both valuable and sensitive.
Excited to see @kenziyuliu and @erikchi launching Second with the guiding principle that AI’s model of you should *belong to you*.
Introducing Second, and a $10M seed led by @a16z.
Second builds a model of you that you own, and your agents can use as an API.
Truly personal software needs a deep understanding of you: not just your emails and messages, but how you work, what motivates you, your people, priorities, style, goals, and intent.
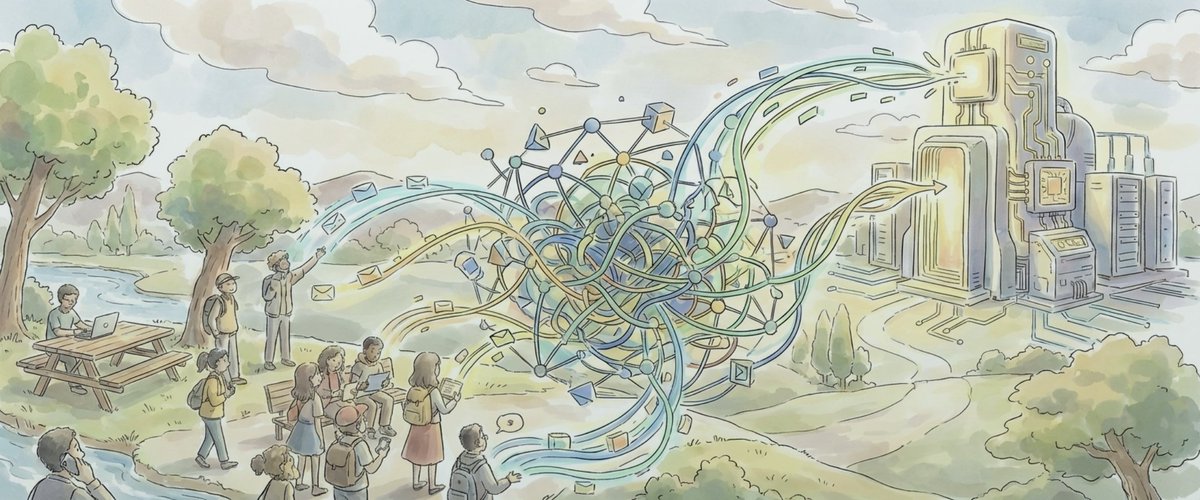
This requires a new kind of personal AI infrastructure. One that continuously aggregates your context, distills it into durable understanding with a ton of compute, and then serves it securely, ubiquitously, and up-to-the-minute. One that builds your *portable user model*.
Second is that infrastructure. It installs seamlessly on your Mac, and your context just comes out. Live APIs of your priorities, to-dos, wikis, writing samples, preferences. Or what you did minutes ago. Or context packs of anything, dynamically assembled in seconds.
Second is streaming-state from local to a private cloud, which means anything you connect to--whether Claude, Dot, Muse, Grok Bot, Instinct, or iMessage--shares the same, growing, continuous understanding of you.
Your portable user model is as powerful as it is sensitive. We founded @FirstPersonLabs on the principle that it should belong to you. This commitment means taking on hard systems and security problems and making sovereignty an invariant of Second from the beginning.
We've barely scratched the surface of what portable user models can unlock. Deep understanding of us, served at machine speeds, could drive the next leap in personal software, human-computer interaction, large-scale coordination of humans and agents, and more!
We're tremendously grateful to be supported by @a16z (@martin_casado, @YODELAGARZA), Mozilla Ventures, @JeffDean, Ram Shriram, Jeetu Patel (@jpatel41), @percyliang, J. Alex Halderman (@jhalderm), @sanmikoyejo, and many others.
Our vision is for a future where every person is more powerful, because they have the ultimate affordance: personal computers that fully understands them on their own terms.
If this excites you, we're hiring and come build with us!
I stopped using ChatGPT a few months ago. Since then, I have been only using oa-chat. All chat history is stored locally. Each query is sent to OpenAI under a temporary key which is unlinkable to any other query. I’m not a privacy nut, but oa-chat is such a convenient drop-in replacement for your favorite AI assistant that there’s no reason not to try it out.
How can users enjoy the benefits of frontier AI without falling into a privacy dystopia? Ken and my PhD student Erik Chi are charting a path to a solution, based on ideas of unlikable inference and private personal intelligence. Try what they've built at https://t.co/e1IvmuHqTJ.
Can we build a blind, *unlinkable inference* layer where ChatGPT/Claude/Gemini can't tell which call came from which users, like a “VPN for AI inference”?
Yes! Blog post below + we built it into open source infra/chat app and served >15k prompts at Stanford so far. How it helps with AI user privacy:
# The AI user privacy problem
If you ask AI to analyze your ChatGPT history today, it’s surprisingly easy to infer your demographics, health, immigration status, and political beliefs. Every prompt we send accumulates into an (identity-linked) profile that the AI lab controls completely and indefinitely. At a minimum this is a goldmine for ads (as we know now). A bigger issue is the concentration of power: AI labs can easily become (or asked to become) a Cambridge Analytica, whistleblow your immigration status, or work with health insurance to adjust your premium if they so choose.
This is a uniquely worse problem than search engines because your average query is now more revealing (not just keywords), interactive, and intelligence is now cheap. Despite this, most of us still want these remote models; they’re just too good and convenient! (this is aka the "privacy paradox".)
# Unlinkable inference as a user privacy architecture
The idea of unlinkable inference is to add privacy while preserving access to the remote models controlled by someone else. A “privacy wrapper” or “VPN for AI inference”, so to speak.
Concretely, it’s a blind inference middle layer that:
(1) consists of decentralized proxies that anyone can operate;
(2) blindly authenticates requests (via blind signatures / RFC9474,9578) so requests are provably sandboxed from each other and from user identity;
(3) relays prompts over randomly chosen proxies that don’t see or log traffic (via client-side ephemeral keys or hosting in TEEs); and
(4) the provider simply sees a mixed pool of anonymous prompts from the proxies. No state, pseudonyms, or linkable metadata.
If you squint, an unlinkable inference layer is essentially a vendor for per-request, anonymous, ephemeral AI access credentials (for users or agents alike). It partitions your context so that user tracking is drastically harder.
Obviously, unlinkability isn’t a silver bullet: the prompt itself still goes to the remote model and can leak privacy (so don't use our chat app for a therapy session!). It aims to combat *longitudinal tracking* as a major threat to user privacy, and its statistical power increases quickly by mixing more users and requests.
Unlinkability can be applied at any granularity. For an AI chat app, you can unlinkably request a fresh ephemeral key for every session so tracking is virtually impossible.
# The Open Anonymity Project
We started this project with the belief that intelligence should be a truly public utility. Like water and electricity, providers should be compensated by usage, not who you are or what you do with it. We think unlinkable inference is a first step towards this “intelligence neutrality”.
# Try it out! It’s quite practical
- Chat app “oa-chat”: https://t.co/ELf8LvxFzX
(<20 seconds to get going)
- Blog post that should be a fun read: https://t.co/OwFmyFlZH5
- Project page: https://t.co/Swerz1xDE2
- GitHub: https://t.co/38CeKajCy2
How can users enjoy the benefits of frontier AI without falling into a privacy dystopia? Ken and my PhD student Erik Chi are charting a path to a solution, based on ideas of unlikable inference and private personal intelligence. Try what they've built at https://t.co/e1IvmuHqTJ.
Can we build a blind, *unlinkable inference* layer where ChatGPT/Claude/Gemini can't tell which call came from which users, like a “VPN for AI inference”?
Yes! Blog post below + we built it into open source infra/chat app and served >15k prompts at Stanford so far. How it helps with AI user privacy:
# The AI user privacy problem
If you ask AI to analyze your ChatGPT history today, it’s surprisingly easy to infer your demographics, health, immigration status, and political beliefs. Every prompt we send accumulates into an (identity-linked) profile that the AI lab controls completely and indefinitely. At a minimum this is a goldmine for ads (as we know now). A bigger issue is the concentration of power: AI labs can easily become (or asked to become) a Cambridge Analytica, whistleblow your immigration status, or work with health insurance to adjust your premium if they so choose.
This is a uniquely worse problem than search engines because your average query is now more revealing (not just keywords), interactive, and intelligence is now cheap. Despite this, most of us still want these remote models; they’re just too good and convenient! (this is aka the "privacy paradox".)
# Unlinkable inference as a user privacy architecture
The idea of unlinkable inference is to add privacy while preserving access to the remote models controlled by someone else. A “privacy wrapper” or “VPN for AI inference”, so to speak.
Concretely, it’s a blind inference middle layer that:
(1) consists of decentralized proxies that anyone can operate;
(2) blindly authenticates requests (via blind signatures / RFC9474,9578) so requests are provably sandboxed from each other and from user identity;
(3) relays prompts over randomly chosen proxies that don’t see or log traffic (via client-side ephemeral keys or hosting in TEEs); and
(4) the provider simply sees a mixed pool of anonymous prompts from the proxies. No state, pseudonyms, or linkable metadata.
If you squint, an unlinkable inference layer is essentially a vendor for per-request, anonymous, ephemeral AI access credentials (for users or agents alike). It partitions your context so that user tracking is drastically harder.
Obviously, unlinkability isn’t a silver bullet: the prompt itself still goes to the remote model and can leak privacy (so don't use our chat app for a therapy session!). It aims to combat *longitudinal tracking* as a major threat to user privacy, and its statistical power increases quickly by mixing more users and requests.
Unlinkability can be applied at any granularity. For an AI chat app, you can unlinkably request a fresh ephemeral key for every session so tracking is virtually impossible.
# The Open Anonymity Project
We started this project with the belief that intelligence should be a truly public utility. Like water and electricity, providers should be compensated by usage, not who you are or what you do with it. We think unlinkable inference is a first step towards this “intelligence neutrality”.
# Try it out! It’s quite practical
- Chat app “oa-chat”: https://t.co/ELf8LvxFzX
(<20 seconds to get going)
- Blog post that should be a fun read: https://t.co/OwFmyFlZH5
- Project page: https://t.co/Swerz1xDE2
- GitHub: https://t.co/38CeKajCy2
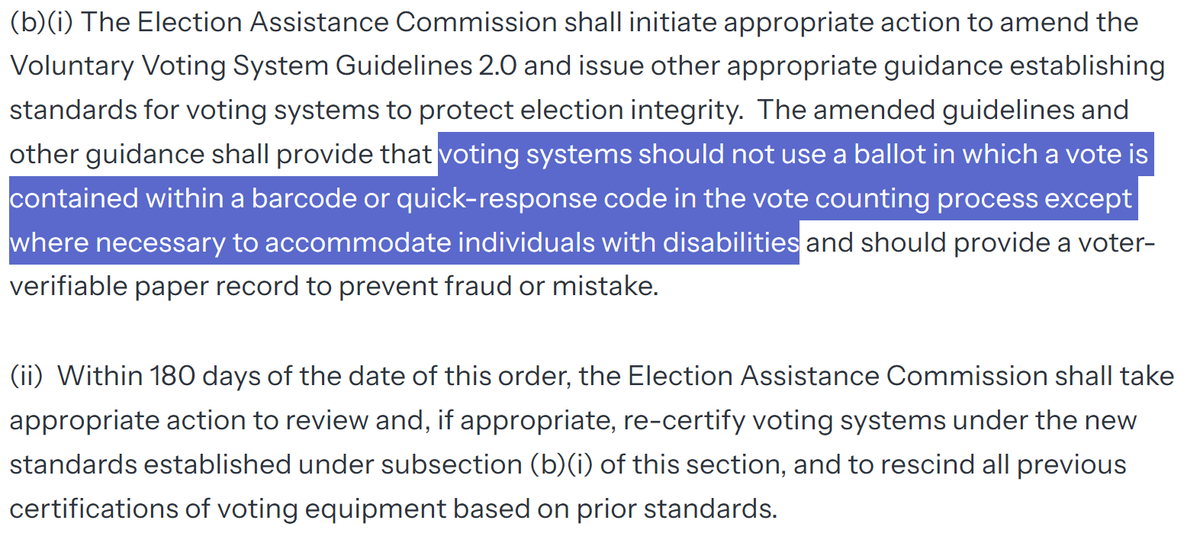
I don't know whether the President actually has the authority to order these changes, but if not, Congress should see them as a starting point for long-needed election security reforms.
Here's the full order:
https://t.co/TrUN8vlXDJ
🎧 NEW PODCAST: Protecting Democracy: My Journey Covering Election Security w/ @jhalderm!
From Georgia’s voting machines to myths about mail-in ballots, we explore how to safeguard elections in a digital world.
🔗 Listen: https://t.co/2vtDdxlqj1
From a security perspective, elections are much safer when there's a decisive outcome than when they hinge on razor-thin margins in a few states.
But what about next time? How many voters will continue to call for necessary election security improvements?
How can #optimization help with #electionsecurity? Read the latest article from Operations Research. "Improving the Security of United States Elections with Robust Optimization" https://t.co/IDrrOsBj2w