1/
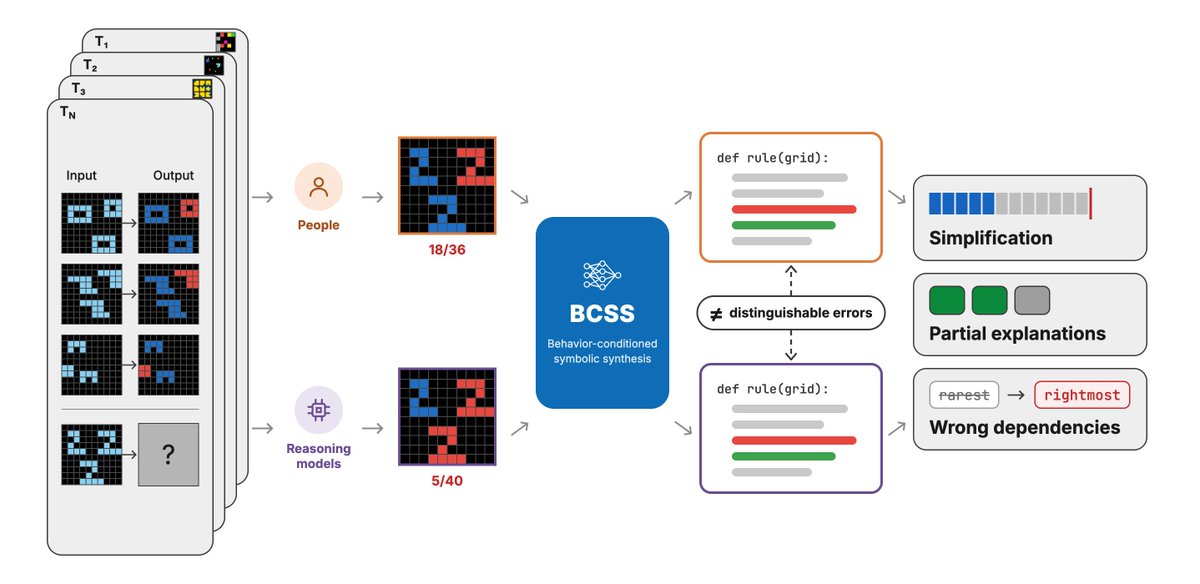
How do people and machines reason in more open-ended, complex cognitive domains? We study their incorrect inferences in the ARC domain to find out.
New preprint: “Synthesizing symbolic models of human and machine reasoning at scale” 🧵
https://t.co/MYImnwIs5j
@PMMondorf@jinjinran@akjagadish@LakeBrenden@todd_gureckis
Wondering how to get the most out of LLM test-time verification?
New study: “When Does Verification Pay Off? A Closer Look at LLMs as Solution Verifiers".
🔍 37 models, 9 datasets
🔥 Self vs intra-family vs cross-family verification
Result: verify across families!
🧵👇