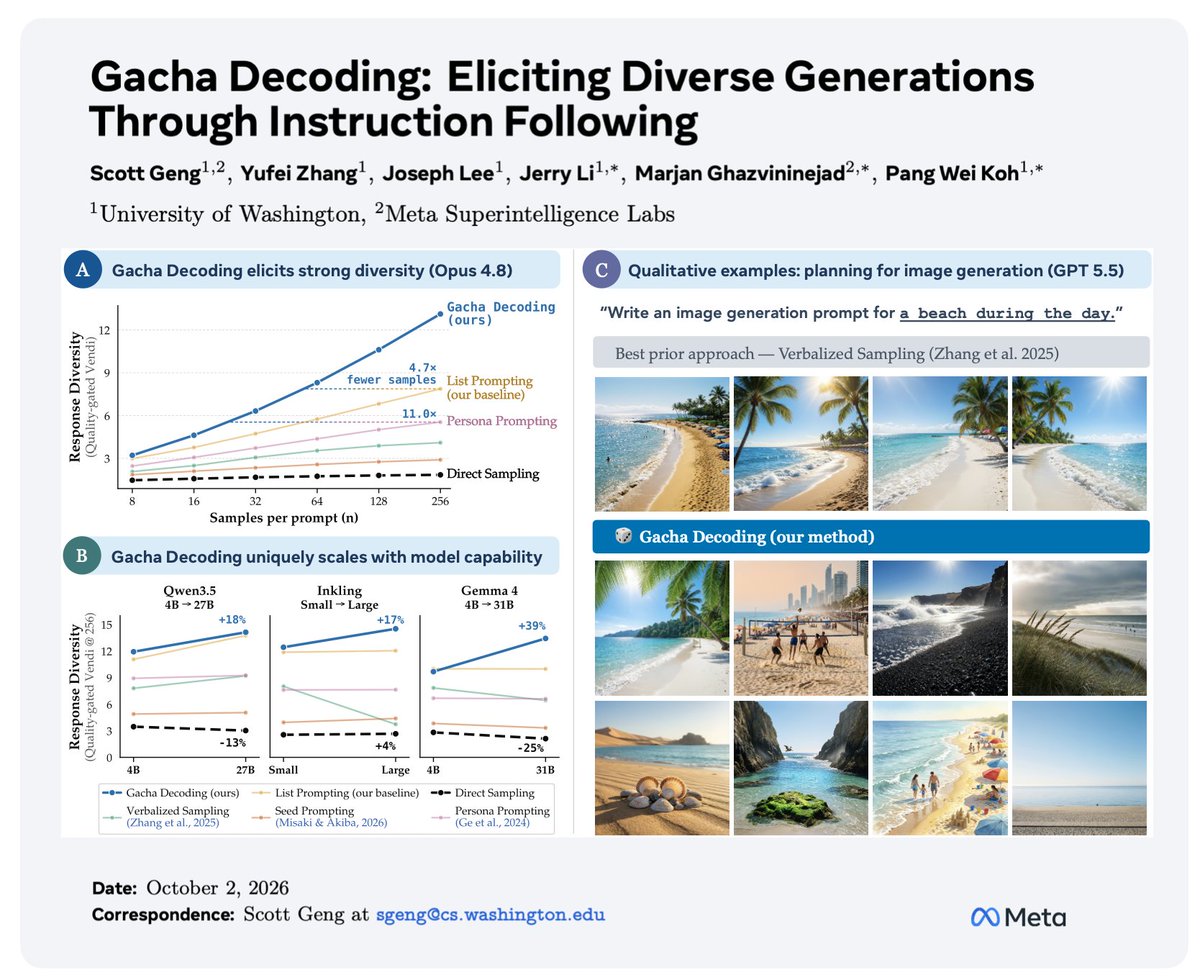
Introducing Gacha Decoding 🎲: we show how to diversify LM responses, beating prior work by >11x in sample efficiency.
Reroll your LM for varied ideas, data, RL envs, {your use here}!
We get diversity from instruction following + external RNG, not token entropy. Here's how 🧵
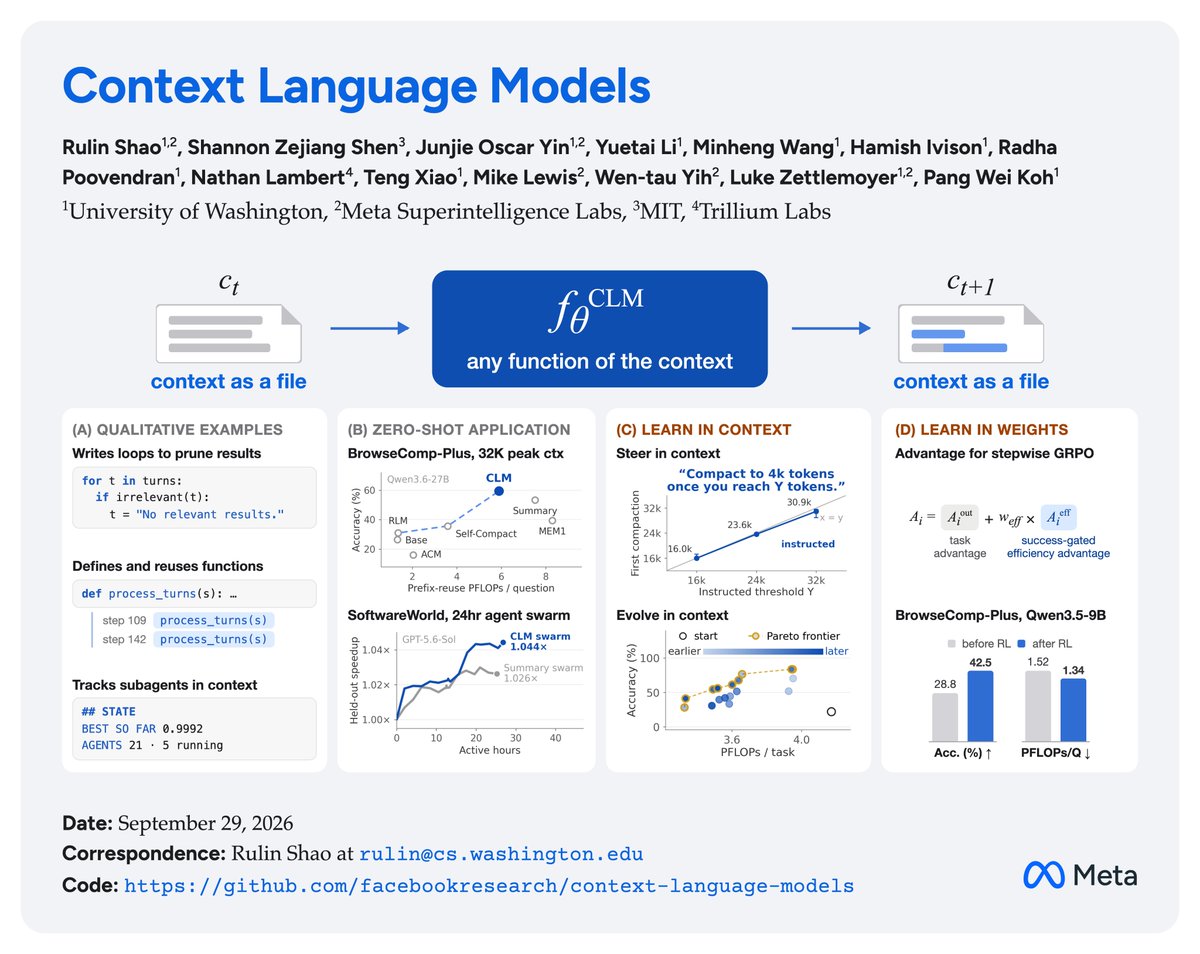
‼️The Bitter Lesson for context management: Giving LMs unrestricted control over their context beats human-designed SOTA!
Introducing 🩵Context Language Models (CLMs)🩵
- Natively manage their own context
- Treat context as a file
- Learn policies in CLM weights, no harness
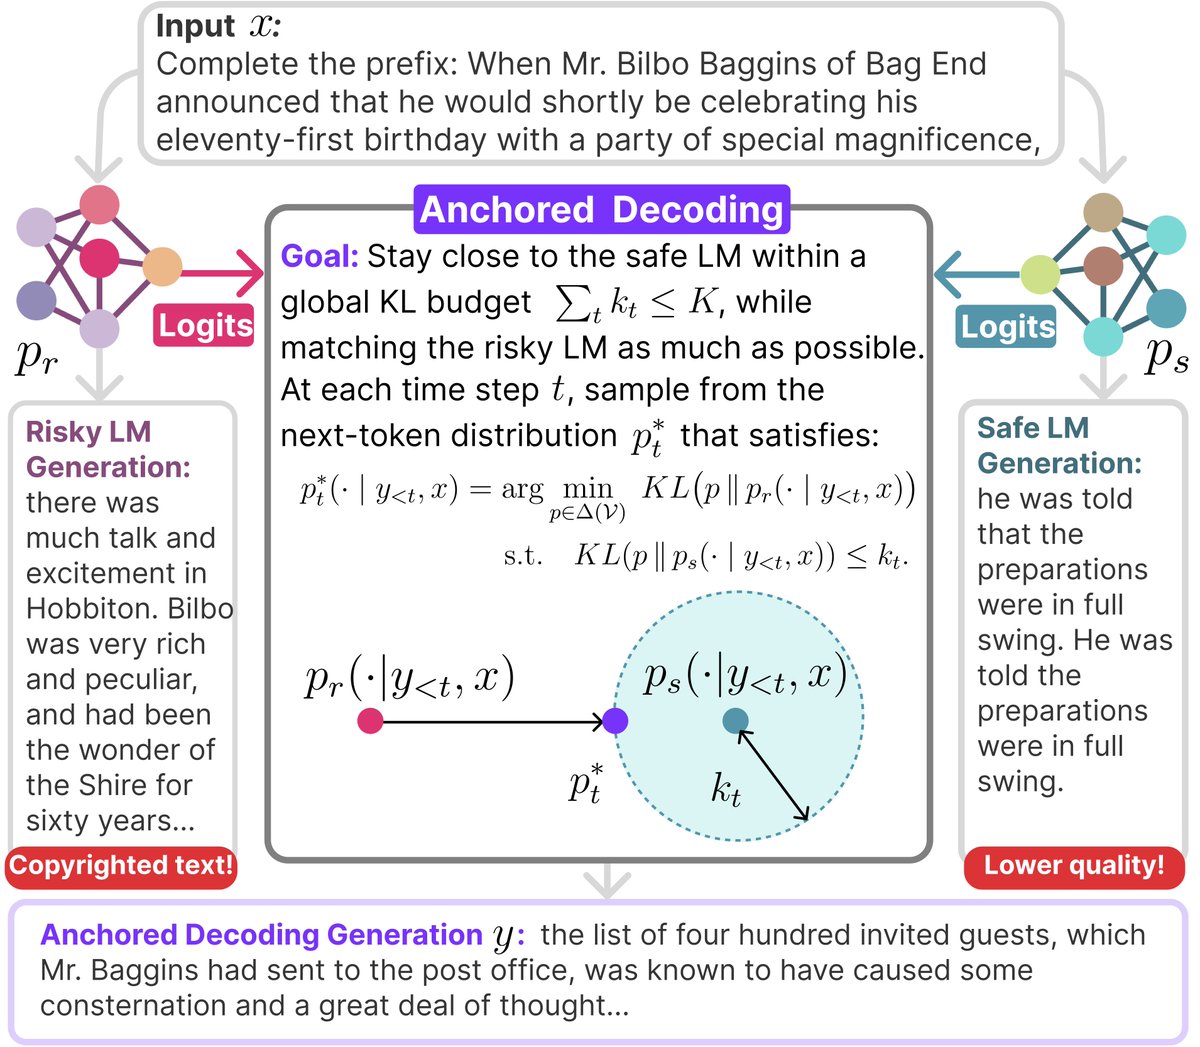
Introducing ⚓ 𝗔𝗻𝗰𝗵𝗼𝗿𝗲𝗱 𝗗𝗲𝗰𝗼𝗱𝗶𝗻𝗴: a copyright mitigation strategy for any language model! With @uwnlp
LMs today reproduce copyrighted text—raising concerns for creator consent and potential legal (and 💸 💸) liabilities for AI developers. 🫠
𝗔𝗻𝗰𝗵𝗼𝗿𝗲𝗱 𝗗𝗲𝗰𝗼𝗱𝗶𝗻𝗴 relies on two off-the-shelf LMs:
🧼A 𝘀𝗮𝗳𝗲 𝗟𝗠 trained only on permissively licensed text,
⚠️A higher-utility 𝗿𝗶𝘀𝗸𝘆 𝗟𝗠 trained on any data.
The 𝗿𝗶𝘀𝗸𝘆 𝗟𝗠 drives generation, but the 𝘀𝗮𝗳𝗲 𝗟𝗠 acts as an anchor. If the 𝗿𝗶𝘀𝗸𝘆 𝗟𝗠 drifts into memorization, the 𝘀𝗮𝗳𝗲 𝗟𝗠 pulls it back ↩️.
🤝We provide a formal guarantee: outputs stays within a user-set budget of the 𝘀𝗮𝗳𝗲 𝗟𝗠.
Details below! 👇
[1/⚓]
🚀Introducing “StochasTok: Improving Fine-Grained Subword Understanding in LLMs”!🚀
LLMs are incredible but still struggle disproportionately with subword tasks, e.g., for character counts, wordplay, multi-digit numbers, fixing typos… Enter StochasTok, led by @anyaasims!
[1/]
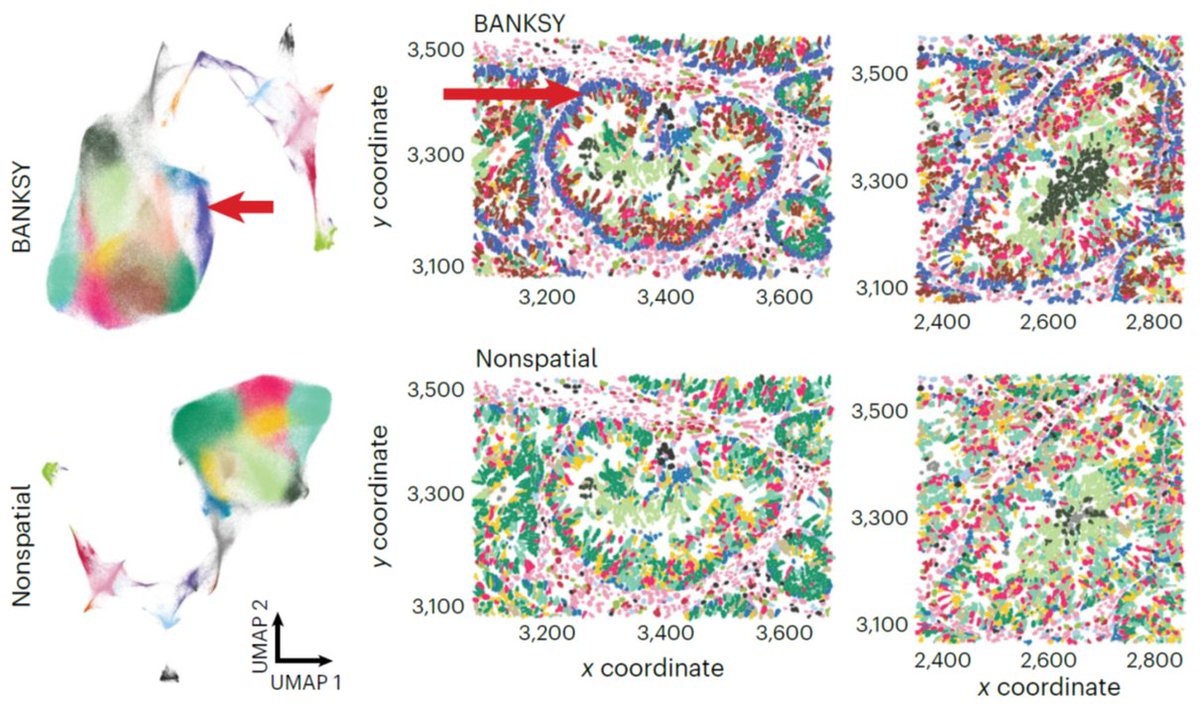
Join us to hear about the BANKSY spatial omics clustering method at the Sydney Precision Data Science Centre's bioinformatics seminar on Monday, 12 May, at 1 pm Sydney time. Link: https://t.co/PoJgi7kbZn
Just out in Cell: the Asian Immune Diversity Atlas (AIDA) is a 5-nation single-cell blood atlas. We show that humans are remarkably diverse in gene expression and cell phenotype, with disease implications #healthcaredisparities#PrecisionMedicine [https://t.co/Rz3ENKb1vm]. [1/14]
That’s a wrap at @icmlconf 2024! Tons of exciting work, old friends and new, and many fan girl moments!
Main takeaway: fewer but more generalizable, efficient foundation models, and watch out for xLSTMs (I have no idea what they are)!
Wonderful to see BANKSY incorporated into this @satijalab spatial data analysis workflow. Looking forward to trying out the other parts. Well deserved recognition for BANKSY’s developers @vipul1891@NigelChouS@jleechung!
BANKSY
A #SpatialOMics R/Python analysis framework using Transcriptomic Neighborhood🤠(Not spatial coordinates Only)
1⃣Distance-weighted mean gene expression of each cell's neighborhood
2⃣Azimuthal Gabor filter▶️Gradient of gene expression in each cell's neighborhood
Work with SlideSeq VISIUM MERFISH VERAFISH CosMx CODEX
vs Giotto MERINGUE FICT SpiceMIX BayesSpace STAGATE GraphST SpaGCN
Can Perform nonspatial & spatial clustering by adjusting "λ ∈ [0, 1], to weight the contributions of the cell-transcriptome matrix and the neighbor expression matrices"
Can handle ~2 M cells in ~1 h!
@vipul1891@khchenlab@shyam_lab@NatureGenet 2024
https://t.co/UW9HYJtva7
1. BANKSY is out! https://t.co/uy8myuVA5p
Our spatial clustering algo applies to any spatial RNA/protein/... assay, scales to 2M cells, detects both cell typing and spatial domains and facilitates spatial batch correction.
🧵 👇