@X0wcol1@PeterHndrsn And I’m not saying not being SoTA should be rejected. There’s a huge gap between “sub-SoTA” and “left behind for 5 yrs”. Besides, this work didn’t even reproduce the 2021 model correctly and the performance was degraded. So declaring itself as SoTA doesn’t stand even in 2021.
@X0wcol1@PeterHndrsn Well the problem is that the task is far from niche (I can’t go anymore specific). This has nothing to do with compute, as recent methods takes similar amount of compute.
WATCH LIVE: Join us for the announcement of the 2026 Nobel Prize in Physics.
Hear the breaking news first.
Where are you watching from?
#NobelPrize https://t.co/sgLBdJRy2P
WATCH LIVE: Join us for the announcement of the 2026 Nobel Prize in Physiology or Medicine.
Hear the breaking news first.
Where are you watching from?
#NobelPrize https://t.co/epIMr3uiSH
(1/8)
We are excited to share our new model ARROW 🏹 !
ARROW brings D4RT-style decoding to broader input types, including multi-view videos and unordered collections of images.
📜arXiv: https://t.co/KJKeQdmo0R
🌐Project page: https://t.co/3T3kxMnTHH
The next test for AI agents is not just whether they can write code.
It is whether they can look, understand, code, inspect—and fix.
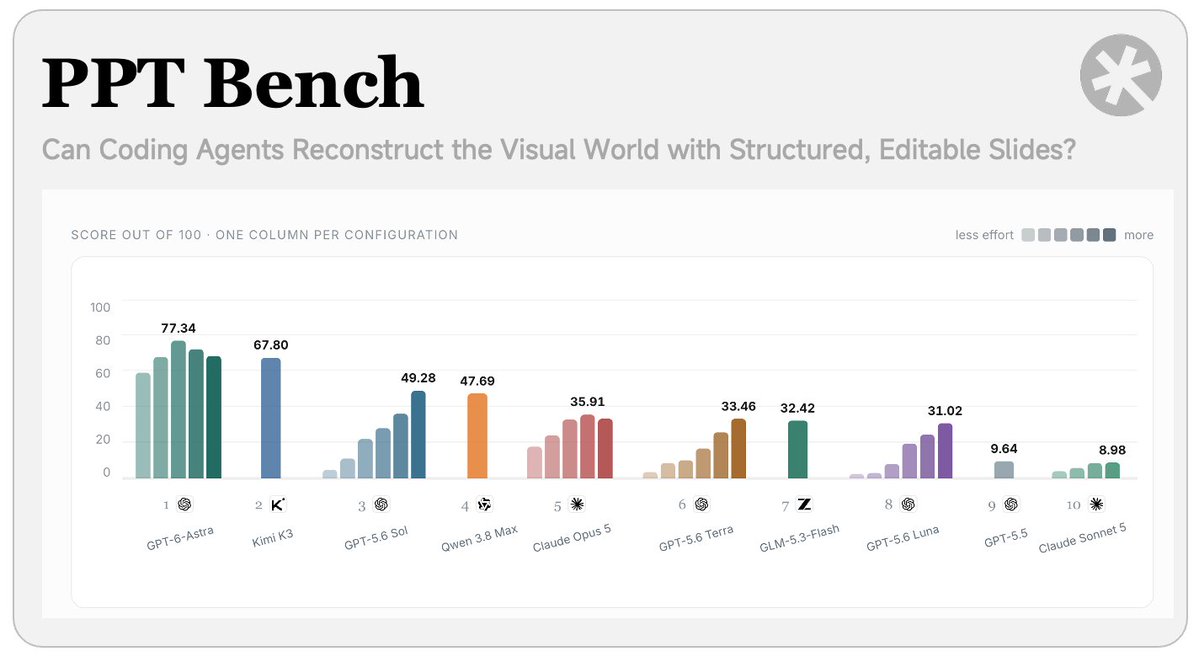
Today we’re releasing PPTBench, a benchmark for Visual Coding through scientific diagram slides reconstruction.
500 tasks. 36 configurations. 18,000 reconstructions.
64.03% failed the semantic check.
Only 2.57% passed all gates with no recorded defect.
Visual coding is still wide open.
🤓 Read agent sessions on AgentGit: https://t.co/XQppVwg6vV
Full breakdown 👇
Project: https://t.co/8nkiEZKFq9
Paper: https://t.co/PC757AHyMG
Github: https://t.co/jnsSLsYfdl
@fuxinli2 During that period, I would suggest strictly desk rejecting irresponsible reviewers (the revealed number of desk rejected article due to irresponsible review is far from strict) as I’ve encountered one exactly during CVPR25. Now there’s really nothing we can do.
Can video generation models do for vision what LLMs did for language?
Introducing GenCeption from @GoogleDeepMind: one feed-forward video model for various vision tasks — SOTA, data-efficient, and emerging behaviors (ECCV 2026)
🌐 https://t.co/3rwVgTolZz
(1/8)
[1/N] Introducing Point4D: dense 4D reconstruction across hundreds of frames from a monocular video. Unlike existing feed-forward 4D methods that operate over short windows, Point4D keeps tracking in 3D, even across occlusions and out-of-frame motion.