If I had 1 month to build my Portfolio Project which will get me hired as an AI RAG Engineer, I would do these, starting from basics to advance:
1) Build your vectordb: Arrange a dataset with thousands of unstructured files. You can get it from any open source repository or platform. Now before chunking, you choose type of vectordb you require. Do you need a dedicated vectordb or pg vector extension? This should be a business impact based decision. If you need Vectordb + Crud operations in one database then go with pgvector extension. If you don't have crud operations in your business and require a high scalable vectordb then go with a dedicated vectordb.
2) Engineer the chunking strategy: The first and foremost strategy of any RAG pipeline is chunking. There are various types of chunking strategies like paragraph chunking, paragraph with overlap chunking, document layout aware based chunking, LLM based reasoning chunking, etc.
For the files which contains text + images + tables, you can opt for either document layout aware based chunking or build a pipeline to process three different chunking for this three different requirements.
3) Build and Evaluate your first retriever like a real engineer: Choose your retriever strategy, either it could be semantic or keyword based or both. Now question is how you gonna choose? It could be usecase wise too, if that dataset has some keywords which is hard to retrieve semantically then use hybrid approch. In interview they will ask how do you know that semantically it will be harder to fetch those?? To answer this question like a True Real Engineer, you do experiments with this two different retriever strategies semantic vs hybrid. You take 1 eval dataset, and example queries, and give those examples queries to retrieval to fetch chunks from vectordb and then you evaluate those chunks with eval dataset with metrices like Precision, Recall, MRR, Hitrate, Context Recall and Context Relevance. Now you make decisions based on this.
4) Choose LLM like a real engineer: In interview, they will ask why you chose that xyz specific model when alot of options where already there? How you gonna answer??? For that, you need to answer it in layers. First layer is resource constraint. You could choose gpt-3.5 or even gpt-5.5, and the very practical decision is based on cost vs accuracy tradeoffs. You can legit say that i chose gpt-3.5 as in my rag pipeline, even though universally we all know gpt-5.5 is better in terms of accuracy, but the cost is a big constraint. This is a legit explanation. Now interviewer might ask you that in the cost range of gpt-3.5, you have many models then why only gpt-3.5, then there to answer that, you do experiments with 3-4 models by taking eval dataset, and comparing with the answers these models generate, and log their metrices like Faithfulness, Groundness, Answer relevancy, and we can have these metrics evaluated by LLM as a judge or Human Evaluation. And then you say that i found gpt-3.5 metrics better than other 3 models so I chose that.
5) Parameters and hyperparameters: In short, you need to build intutions with experiments. When interviewer ask that why did you choose top-k=3 in llm generation part, or temperature=2, then you better answer it with evidences.
6) Deploy in AWS or Azure and practise system design concepts there. Try load testing and see if your vectordb is handling load, monitor the logs, increase load again and log the metrices. Play around, some will break, fix and debug.
The more your decisions are grounded, the more you are closer to real engineering. Otherwise you are just another vibe coder who don't understand a shitt in depth.
⭐ Save. Repost. Follow
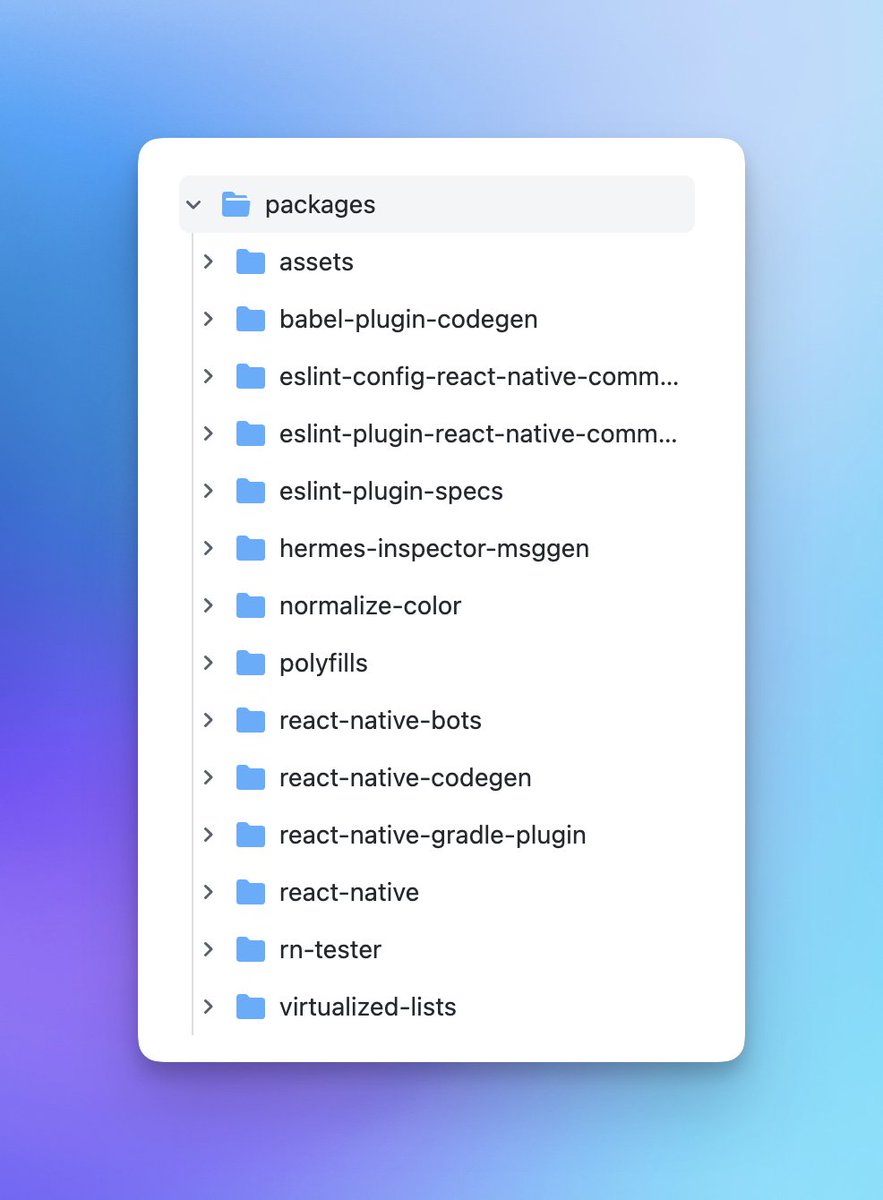
React Native will soon be a Monorepo! There is an open PR with migration 🚀
It's still a work in progress, currently at 3,763 files changed 🤯
Check it out here: https://t.co/TsghvreJZ8
Your end goal will never make you completely happy. Once you hit it, you will immediately move the goal posts.
It is the person you become along the way! That is where you will learn the most about yourself. THAT is where you will find your happiness.
It's my turn to be positive(COVID).
Guys who wanted to register for my Storybook workshop. I am diagnosed Covid positive and hence couldn't send invites.
The workshop might get postponed to Feb as well. Sorry for the delay. Will keep you guys posted once I recover