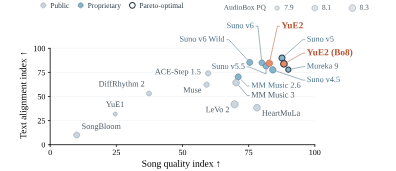
ACE Music v1 debuts at #1 on AA-Music-Vocal v1.1, ahead of Suno v6
ACE Music v1 is the new music model from ACE Studio. Founded in 2018, ACE Studio began in AI singing voice synthesis: its ACE Studio app is an AI music workstation that turns MIDI and lyrics into vocals for music producers. Together with StepFun, it also co-develops ACE-Step, a family of open weights music generation models.
ACE Music v1 generates full tracks with vocals or instrumentals from a text prompt, starting from a description or your own lyrics.
In our testing, it does best on Reggae / Dancehall and Classical / Orchestral prompts.
ACE Music v1 has no API. It is available in the ACE Music app, with a free tier of 20 credits a day and paid plans from $7.90 a month billed yearly, for up to 500 songs a month.
Congratulations to @acemusicAI on the release!
See below for comparisons between ACE Music v1 and other leading models in the Artificial Analysis Music Arena 🧵
Today, we introduce Priming Models, a new paradigm for training one-step generative models from scratch.
No diffusion teacher. No flow map. No CFG. No JVP.
We believe this work will challenge how we think about building one-step models.
Joint work with @sitanch, @du_yilun, @parkwbin03, Bohyung Han.
🔥 1.19 FID one-step on ImageNet 256×256 while using substantially less compute, e.g., 12X less than Drifting-B, 6X less than Drifting-L
🎨 Scales to text-to-image generation (GenEval 0.82)
🤖 World modeling on RT-1 / Bridge-V2
Priming Model is built on one core message: [Reconstruction pretraining --> Distributional post-training].
Proud to have co-developed StepAudio 3 Music with @StepFun_ai! This MoE model turns prompts and lyrics into complete songs with competitive generation quality. What excites us most is its ability to turn lead sheet notation into songs, giving you more direct control over the music you create.
♾️ LiFT: Loop Flow Transformers 🧵👇
Diffusion models usually spend more inference compute by taking more sampling steps. What if we could also spend compute inside each step?
LiFT turns part of a DiT into a recurrent core, letting us scale depth at inference with only a small architectural change. On ImageNet, it beats dense DiT-XL/2 with 3.34 lower FID, while using 60% fewer parameters, 32% fewer training FLOPs, and 52% fewer inference FLOPs.
Jointly led with Mohammad Mahdi Derakhshani 👑(@mmderakhshani)
And amazing supervisors Cees Snoek (@cgmsnoek), Jan-Willem van de Meent (@jwvdm) and Gertjan J. Burghouts (@gjburghouts)
StepFun and ACE Studio present StepAudio 3 Music, StepFun’s first music generation foundation model — built to turn a prompt and lyrics into a complete song.
Describe the sound you want:
• Genre, mood and vocal character
• Instruments, key and BPM
• Song structure and arrangement
Four workflows in one model:
🎤 Song generation
🎹 Instrumental generation
🔁 Music cover
🎙️ Vocal-to-song arrangement
Powered by ABC-COT, it plans musical structure and arrangement before synthesis. Generate a version, rewrite the prompt, edit the ABC notation, and iterate toward the sound in your head.
(ABC-COT API coming soon)
Try the interactive demo:
› https://t.co/oriJgklAbT
I believe we’re at a new inflection point.
Open-source music models like yue 2.0 have matched, or even surpassed closed-source alternatives like Suno, ElevenLabs and Lyria 3.5 in certain capabilities (abc notation planning).
While there remains a small gap in controllability and coverage, it is only marginal. Most of these limitations can be addressed via local fine-tuning. Meanwhile, closed-source music models are experiencing diminishing marginal returns.
https://t.co/QUZnNIUihn
hiii i’m Miya 🐱 I’m a music cat, and a whole new way to experience music.
I make music, play music...whatever.
All you gotta do is talk to me. I’m basically your personal musician + DJ.
anywayyy I wrote my first song about myself because obviously…
come try me: https://t.co/FArU6e7OnO
Hey fam, a fun little project built with ACE-Step.
Miya is a music agent that turns conversations into music.
Just talk to her, and she can make songs or play music for you.
Try Miya: https://t.co/ypUIg3JlrQ
Our Open Source music model will be unlimited, will let you train on a small specialised dataset, clone vocals to keep tracks consistent and have all the features you use on Suno like extend, cover, remix, editing and more. It will be free and you'll be able to download this locally.
We anticipate our model to be out before December. We are working on it right now and progress is going well. Alternatively, in the mean time we recommend using @MiniMax_AI, Ace Step, @ElevenCreative, @Mureka_AI and @TrebloApp
Finished the Awesome AI Music list.
> Music Generation Models
> Audio-Language Models
+ Full list of all ACE-Step 1.5 models/quants/LoRAs
https://t.co/dxzGao69QF