Through the VOICE trial, Terry is using his Neuralink implant to help fine-tune a brain-to-voice interface for himself and others who can’t speak. He trained the algorithm first by miming speech as best he could, then by simply thinking the words and hearing them come out in his own natural voice.
Powered by Grok Voice from @SpaceXAI
Bangalore produces around 7,000 tonnes of waste a day, roughly 3,000 tonnes of that is wet waste. All of it has to be collected, segregated, and processed every single day. A lot of it still ends up badly treated or in a landfill.
We got to know the @HasiruDalaInnov team a few years ago. They've spent years doing the thankless part of this, collecting and segregating waste at scale. But wet waste has remained a problem. Dry waste has buyers. Wet waste goes bad too quickly to store, and composting it usually loses money.
@carbonmastersuk takes that wet waste and turns it into biogas you can cook with. More importantly, they've made a business out of it.
Put the two together, and it's fairly obvious. Hasiru Dala has the waste and knows how to sort it. Carbon Masters knows how to generate economic value out of it by generating biogas and organic manure.
This problem goes beyond Bengaluru's garbage. India imports about 60% of our LPG and half our natural gas. Turning our own waste into fuel is about as self-reliant as it gets.
We need more people working on hard problems like this. That’s also why we’ve backed both Hasiru Dala Innovations and Carbon Masters through @Rainmatterin.
We spent some time at their Harohalli plant to understand how it all fits together for our latest Rainmatter Original. If you've ever wondered where the waste from our homes actually goes, this is worth a watch (full episode link in comments).🙂
We’re ending our partnership with Cursor following its acquisition by SpaceX. Under our proposal, Cursor’s direct access to our models would end on November 12.
We know that the people most affected by this decision are the developers who rely on OpenAI models in Cursor. We care about their experience in this transition and we’re ready to go above and beyond to support them.
https://t.co/OzuCTzUjfX
The number of investment decks I get leading with “we use AI” is ridiculous. It’s reached a point where it automatically makes my eyes roll, and I’ve almost stopped looking at them.
Founders need to realize that AI is just table stakes now. Bragging that your product uses AI is like bragging that you take a bath every day. It’s not a differentiator. In fact, opening your pitch with it is a surefire way to get ignored, not just by us, but by most serious VCs.
Especially now that AI has democratized the ability to generate “nice-looking” decks, the last thing you want to do is say the exact same generic things as every other founder using the exact same tools.
They have been doing this exact same thing for decades. Would be interesting to see if it will still pay off. Let everyone fight, sit on heavy cash and then once the dust settles buy the ones that survive and have a slight niche / edge.
Apple might be right.
There's no money in llm itself.
OpenAI and Anthropic are in pure competition with Chinese labs in race to the bottom of price while ever more difficult effort to improve the models.
Then there's Apple sitting back and letting billions and billions roll in doing nothing.
And when the time comes, Apple can rebrand the llm layer with some Chinese frontier lab's open sourced llm calling it Apple Intelligence and call it the most privacy focused AI there is. People will pay for monthly subscription for 9.99 because it's integrated with iOS at OS level and apps will develop around it.
Do nothing and win. The apple way.
One should definitely show some love to perfumes, and they need not be extremely expensive. If you can afford great but even with that go for middle eastern ones. Funny enough all these middle eastern top brands are owned by Indians.
I am a perfume fanatic, I would use attar/oils to layer my skin and top it with good perfumes.
I don't wear perfumes for anyone else but myself, anyone else noticing and completing is a lottery/ bonus.
It really really goes a long way with your personality and social cues.
Beware dont get addicted to it, or if you may please have friends like @ujjwal1600 who will randomly shop finest unreleased perfumes and ship it you for free 🤣🤣🤣
Claude's watermark probably doesn't work how you think. As the CTO of GPTZero, I'll explain how Anthropic, Google and OpenAI are building text watermarking in this brief explainer and whether it can be defeated.
Almost all forms of watermarking that are fast and cheap enough for a frontier lab have the same formula, following the KGW method:
In generation:
1. Let's say you've generated n tokens so far. Take those n tokens + a secret key to generate a random hash
2. Use that hash to randomly reweight the probabilities for the n+1 token, and then sample from that new distribution. In the simple case, you could split 50% of all English words into a green or red set based on your hash, and boost the probability of words in the green set.
For watermark detection:
1. For each token, see if it was in the green or red set.
2. To do this, recreate the hash based on the secret key and the text preceding the current token. Then, recreate the green and red set of words.
3. Once you've checked all the words in the text, if the next token is selected disproportionally from the green set more than 50% of the time, you claim the text has the watermark.
I can tell you want to ask the following:
1) Isn't it easy to mess up the hash if you paraphrase the text? The answer is mostly yes, however, you can use a statistical model to get your hash instead of a deterministic function (SIR, Adaptive Watermark). Since the entire watermark is probabilistic, this is fine.
2) Doesn't this make the text much worse? The answer is yes, it does - Yes, it does – but for most people, it's imperceptible (Google claims in human feedback study with 20,000 texts), since there are exponentially many ways to write the same paragraph. DiPmark does something more sophisticated to avoid shifting the text distribution on average. Of course, watermarks fail on short text or highly predictable texts like "2+2=4".
3) Shouldn't it be easy to figure out the green and red sets? The answer is no. You would need an exponentially large number of samples from the watermarker to reconstruct those sets exactly, but it's a risk if the detector is open to the wild (Watermark Stealing)
Still, there are couple challenges that a frontier lab needs to overcome:
1. Their watermark needs to work token-by-token because they are streaming their text to users. Many watermark methods plan sentences or paragraphs at a time, or change the text after its entirely written, in order to make their watermark robust to paraphrasers, and a frontier lab cannot afford to do this yet (SemStamp, PostMark)
2. If the secret key leaks, the watermark is busted. To avoid a large blast damage from this, you need to have a couple secret keys in rotation.
3. There are some texts, like code, that cannot be arbitrarily changed, otherwise the code will break. In those cases, the watermark needs to selectively change words in parts of the text that can tolerate synonyms (i.e. like variable naming) - see SWEET, EWD, Invisible Entropy.
4. They will need to educate their users on how to deal with false positives and false negatives of a detector, which is a big challenge (one we put a lot of effort into)
So, how do I see this playing out in the next 6 months?
1. If Anthropic releases the watermark detector publically, I think they defeat their own watermark. People find reliable watermark removal strategies by testing against Anthropic (AI detectors like GPTZero have an advantage here because they can train against these adversaries once they become popular).
2. If they keep the detector private to the government, like Google has done, it's "safer". However, there are some papers showing trained approaches that work robustly to zero-shot break watermarks without any data, simply because they try to write the text just like a human (Zhang et al. 2024, Watermarks in the Sand). Also, making your detector makes it battle-tested and stronger long-term (my experience).
3. In my testing, the watermarks don't survive intense paraphrasing (especially if you combine word choice and syntax attacks), or human text substitution (rewrite your AI text by plagiarizing human authors). The free paraphrasers I've tried have quickly bypassed Google Deepmind's SynthId for what it's worth.
4. All-in-all, frontier labs are likely okay with this because they expect most users to not attack the watermark, and also because they + European regulators likely don't care past a certain point - its good enough.
5. Overall, I think users of frontier LLMs will not really care about this, because 1) they don't realize watermarks are there, 2) EU will force everyone to conform, 3) this seems more like regulatory hoop-jumping than an earnest effort from frontier labs to expose LLM use
Lastly, people's first concern shouldn't be watermarking, it should be AI detectors!
If you're posting, "its not X, its Y!!", I don't think the watermark is going to make a difference :)
Introducing Muse Glimmer, an open-weight 30B-parameter model optimized for local, always-on agent workflows.
Muse Glimmer delivers strong performance on key agentic use cases and benchmarks compared with leading models in its size category, and is designed to run entirely on consumer hardware like a Mac or PCs with performant GPUs.
In keeping with our long tradition of sharing fundamental AI research, we’re releasing model weights under a permissive Apache 2.0 license.
🧵👇
Expired meat, fish & milk found in Bengaluru’s top luxury hotels.
30 teams inspected 26 three-star & five-star hotels across BBMP limits today. 35 food samples collected for lab testing.
Hotels where food was seized:
• The Lalit Ashok – 76 kg meat, 200 kg vegetables & 32 litres expired milk
• Shangri-La Bengaluru – 15 kg meat
• Four Seasons Bengaluru – 19 kg meat
• Vivanta Whitefield – 3 kg expired bakery products
• Taj Yeshwantpur – 72 kg meat/fish
• Radisson Blu (The Atria) – 105 kg expired food (50 kg chicken, 25 kg meat, 23 kg fish, 7 kg vegetables)
Violations included expired food, fungal growth, unhygienic kitchens, misbranding, FSSAI labelling violations and improper veg/non-veg storage. Notices issued; further action to follow after lab reports. #Bengaluru #FoodSafety
Taking a loan has never been easier. There is almost no friction between wanting something and borrowing to pay for it.
The problem is that income is limited, while the list of things we want is endless. And often, it isn’t even the purchase we want as much as the momentary thrill of buying it.
We are taught how to earn and save, but learning how to spend is just as important. When an impulse purchase becomes an EMI, you are committing future income even before it hits your account. The excitement of spending fades in days, but the debt stays for years.
Borrowing to invest in a home, education, or business makes sense. Borrowing for lifestyle consumption locks you into a loop that leaves no breathing room when an emergency hits.
In this video, @Zero1ByZerodha looks at why household debt in India is rising, how to assess whether your debt is manageable, and practical ways to pay it down.
Congratulations to @PrateekLearnapp, @swati_learnapp, and the team on crossing 800,000 subscribers.
New in Claude Code: your sessions can now message each other.
Instead of having to re-explain yourself in another session, you can now tell Claude to do it. It sends a summary (not your history or files), and the other session picks it up mid-task.
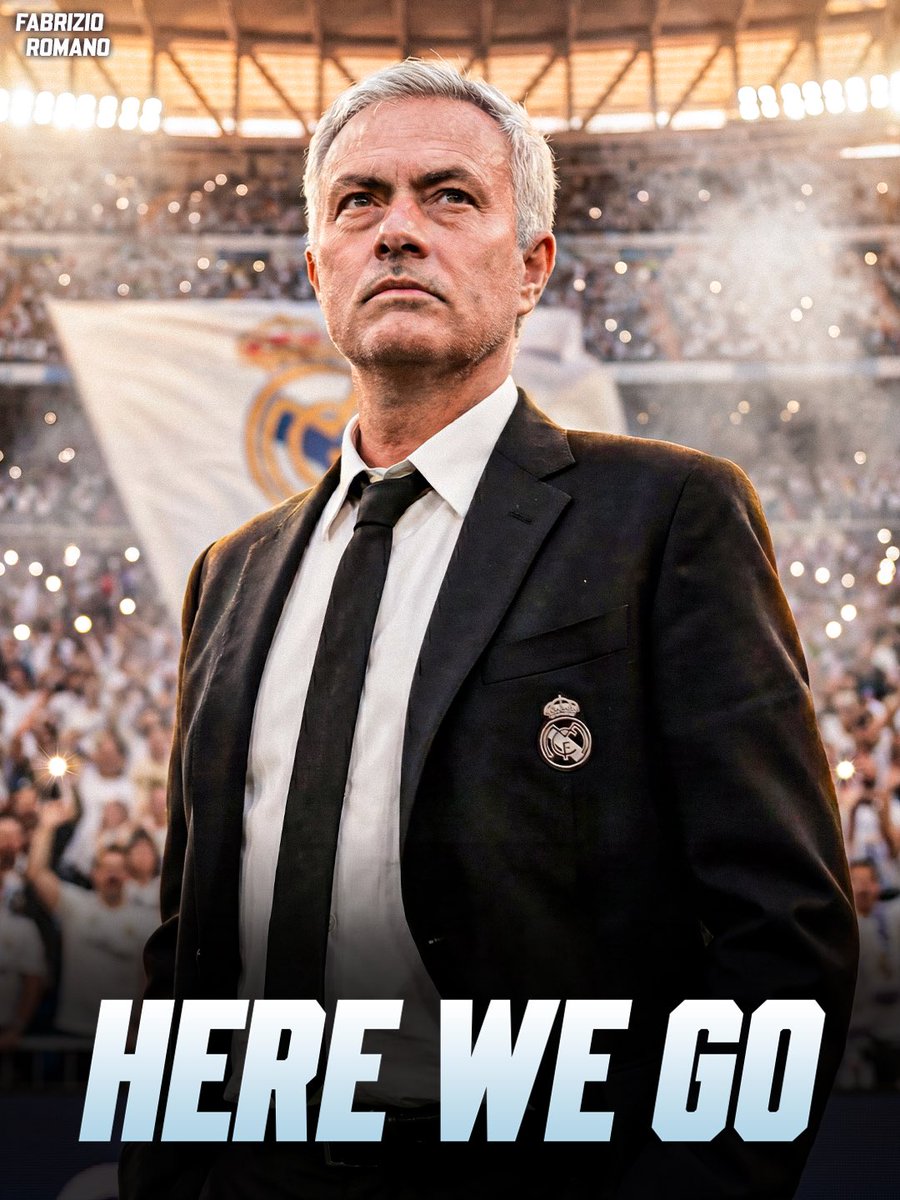
🚨 BREAKING: José Mourinho back to Real Madrid, HERE WE GO! 💣🤍
All terms have been verbally agreed between José Mourinho and Real Madrid, waiting to sign all documents.
Plan for initial two year deal, JM to travel to Madrid after Real-Bilbao game.
The Special One is back.