Legal AI Model Dev Analyst @Mercor | API Developer | Legal Tech | 2026 Hackathon Winner | Building at the intersection of law × AI × infrastructure ⚖️👩🏽💻
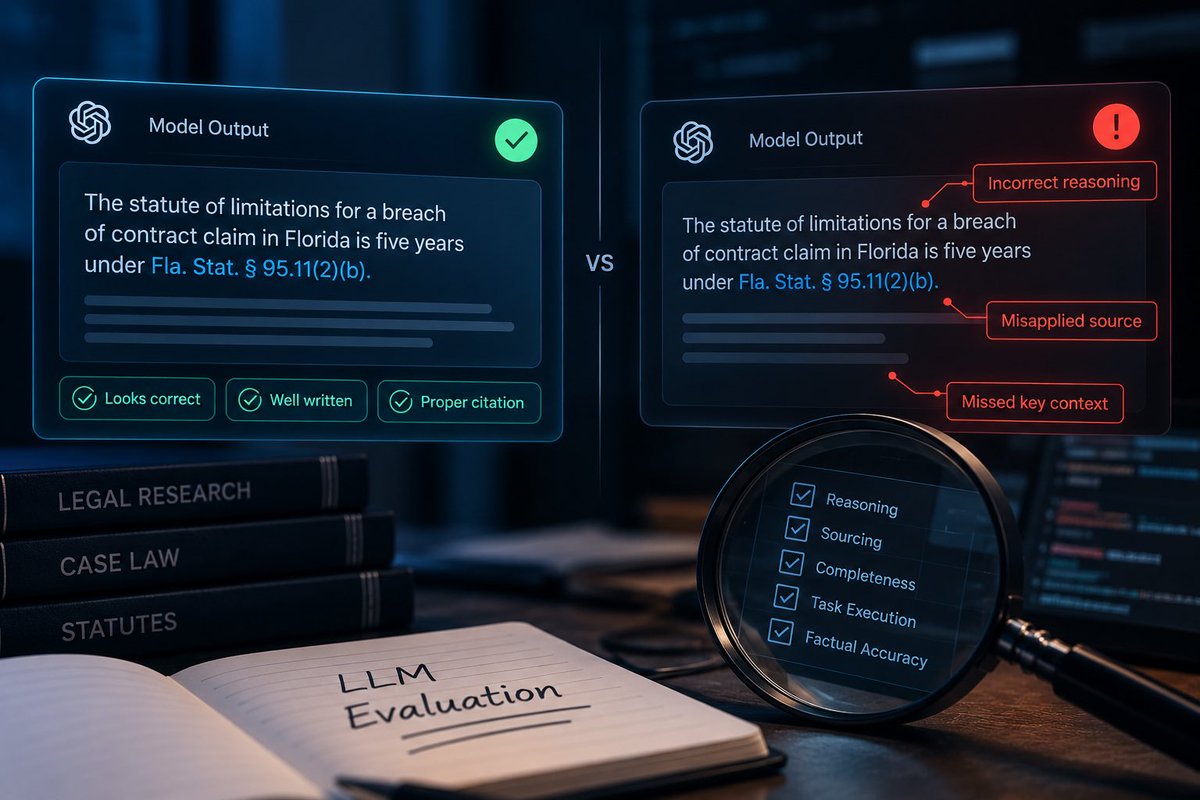
LLM evaluation is part of development—not an afterthought.
Generating an output is easy. Testing whether the reasoning holds, the sources support it, and the model actually executed the task is where things get interesting.
Good AI needs good evals. #AIDev#AIEngineering#LLM
Early in my developer journey, I built a PresentMeAPI submission—an API-driven agent that converts natural-language prompts into structured, executable workflows for game dev.
It became my first hackathon-winning build. 🏆
#AIAgents#LLMDev#APIs
APEX turns 1 today.
Last year, we launched the AI Productivity Index (APEX) to answer whether frontier AI models can do professional work. Since then, we’ve created new benchmarks while model capabilities progress more rapidly than even the boldest predictions.
APEX remains the industry standard for evaluating frontier AI on economically valuable work.
Here’s how APEX has evolved over the past year.
𝗢𝗰𝘁 𝟮𝟬𝟮𝟱: 𝗔𝗣𝗘𝗫
Mercor introduces APEX, our first AI benchmark for testing investment banking, law, consulting, and medicine.
𝗝𝗮𝗻 𝟮𝟬𝟮𝟲: 𝗔𝗣𝗘𝗫-𝗔𝗴𝗲𝗻𝘁𝘀
Built with partners @box and @harvey, APEX-Agents evaluates AI agents on long-horizon tasks in investment banking, consulting, and corporate law.
𝗠𝗮𝗿 𝟮𝟬𝟮𝟲: 𝗔𝗣𝗘𝗫-𝗦𝗪𝗘
Co-developed with @cognition, APEX-SWE assesses real production engineering across integration and observability.
𝗝𝘂𝗹 𝟮𝟬𝟮𝟲: 𝗔𝗣𝗘𝗫-𝗔𝗰𝗰𝗼𝘂𝗻𝘁𝗶𝗻𝗴
Built with @tryramp and @RampLabs, APEX-Accounting measures whether models can close the books.
𝗦𝗲𝗽 𝟮𝟬𝟮𝟲: 𝗔𝗣𝗘𝗫-𝗔𝗴𝗲𝗻𝘁𝘀 𝟭.𝟭
Our first major update to APEX-Agents includes newly audited tasks, an improved judge, and enhancements to ensure leaderboard accuracy.
Thank you to all our partners who built these benchmarks with us. And, to the Mercor experts, professional bankers, lawyers, consultants, doctors, engineers, and accountants, whose judgement and expertise ensure these benchmarks are realistic.
The rate of AI progress is only increasing. Mercor is committed to maintaining and extending our APEX family of benchmarks as the industry standard for informing decisions about the AI frontier and its ability to do professional work.
See full leaderboards: https://t.co/JU07IwL0fQ
Gemini 4 Argon is the new #1 on APEX-SWE Integration.
Pass@1 scores for coding tasks:
Integration: 72.5% (#1)
Observability: 26.8% (#25)
Overall: 49.6% (#13)
It is the best Gemini model on APEX-SWE, +7.6 pts over Gemini 3.7 Flash.
𝗧𝘄𝗼 𝘃𝗲𝗿𝘆 𝗱𝗶𝗳𝗳𝗲𝗿𝗲𝗻𝘁 𝗿𝗲𝘀𝘂𝗹𝘁𝘀
Integration tasks ask the agent to build end-to-end systems across services. Argon leads this domain, +3.2 pts over Sonnet 5.5 (69.3%).
Observability tasks ask the agent to debug production failures from logs and telemetry. Argon scores 26.8%, 43 pts behind the leader, Opus 5.5 (69.8%).
𝗖𝗼𝗻𝘀𝗶𝘀𝘁𝗲𝗻𝗰𝘆
We ran every task 4 times.
On integration, it passed 72 of 100 tasks on all 4 runs. Observability, it only passed 17 of 100 tasks on all 4 runs.
𝗧𝗼𝗸𝗲𝗻𝘀
Argon reads a lot more on Observability tasks:
Integration: 1.3M tokens per attempt
Observability: 7.5M tokens per attempt
On Integration, failing runs used more than twice the tokens of passing runs (1.7M vs 0.7M median).
On Observability, passing and failing runs used about the same (7.1M vs 7.8M median). More reading did not lead to more passes.
𝗙𝗮𝗺𝗶𝗹𝘆 𝗽𝗿𝗼𝗴𝗿𝗲𝘀𝘀
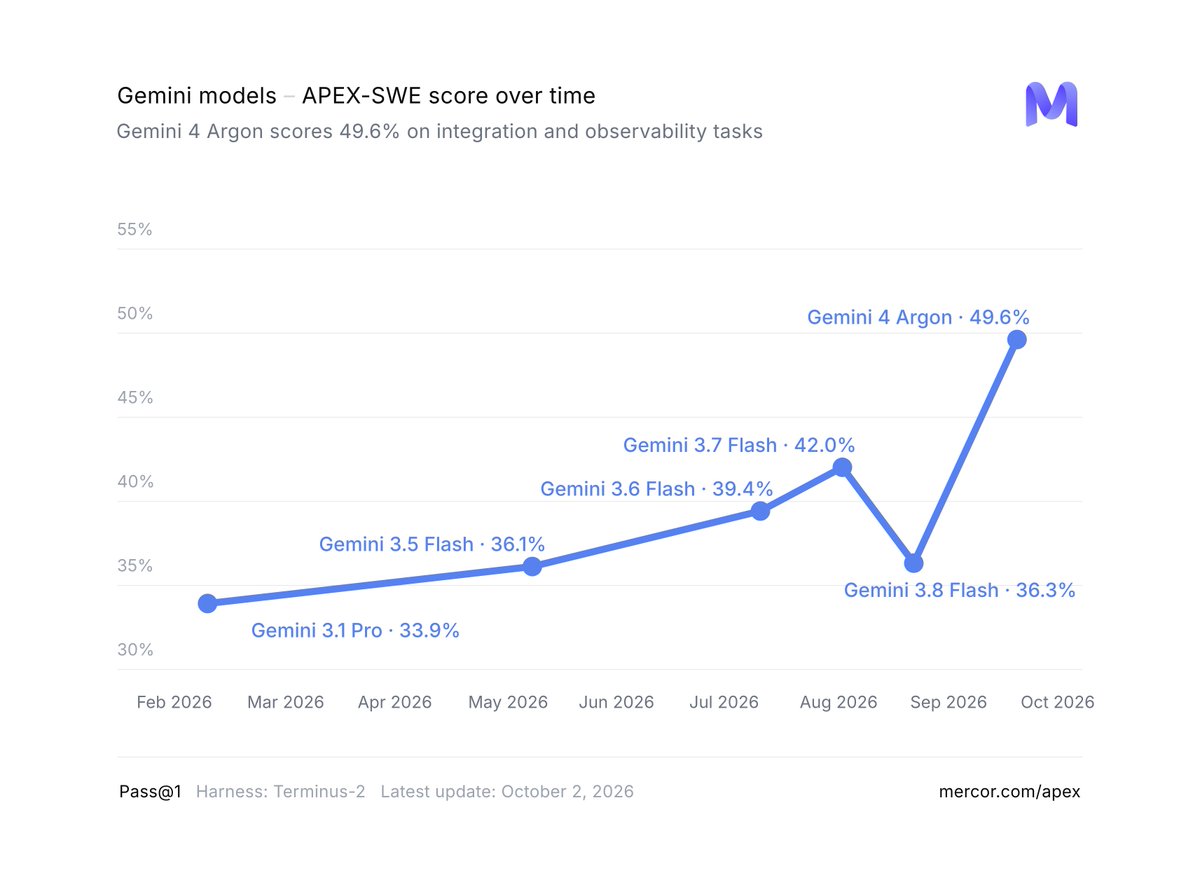
Gemini on APEX-SWE, Pass@1:
Gemini 3.1 Pro: 33.9%
Gemini 3.5 Flash: 36.1%
Gemini 3.6 Flash: 39.4%
Gemini 3.7 Flash: 42.0%
Gemini 3.8 Flash: 36.3%
Gemini 4 Argon: 49.6%
Argon is +15.7 pts over Gemini 3.1 Pro.
Congrats to @Google and @GoogleDeepMind.
The deeper I get into LLM evaluation, the more interesting the gap between “correct output” & “good model behavior” becomes.
An answer can look right while the reasoning, sourcing, or task execution underneath is wrong.
LLM evals are such an interesting engineering problem. #AI