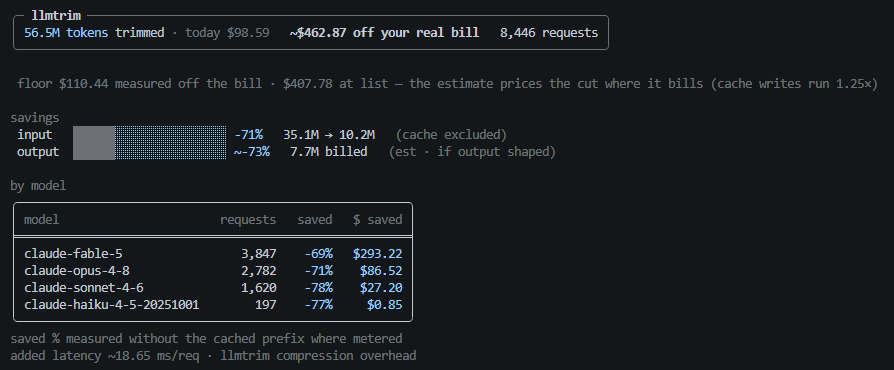
You're paying full price for every token Claude Code sends, the first time it sends it. The cache discount only kicks in on the second pass.
That gap cost me ~$460 before I built a fix: llmtrim, an open-source proxy that compresses those tokens ~68% without busting the cache.
Try this, llmtrim. Similar to rtk, it claims to cut down noise in your tool calls, reducing the tokens sent to your LLM provider.
Initial test looks ok, but I am not yet seeing much quota increase. No harm trying.
@semihlaki Congrats on TAP, and thanks for the shoutout. Similar thing happened to me with headroom: found out about it after finishing my own product, mine ended up more performant, smaller, and faster. Would love to have you contribute to llmtrim sometime.
herdr 0.7.0 is out, and it's a major one: it introduces plugins!
the idea is simple: herdr stays lean, and everything custom gets extended through plugins. shareable, scoped, built however you want, to fit your own flow.
with this release we're also shipping a few examples of what the plugin system can do. first up: a telegram plugin.
herdr already controls your agents and knows their status, so the plugin just hooks into agent events and pings telegram the moment one needs you.
notification lands → `herdr --remote` or ssh from your phone → straight back to the agent that needs you.
@GithubProjects Improving llmtrim: a local proxy that strips wasted tokens out of every LLM request. Same answers, smaller bill: −31% input, −74% output. One static binary, ~5 ms per call, no model to load.
https://t.co/GjLwCYHOaa
@Marco_Ramilli Maker here, thanks for the share! That 31% is just input tokens. Output drops ~74%, so the round-trip bill is about 59–66% cheaper depending on the model. Lossless and re-checked every request, so it can never make your bill worse.
🤖 llmtrim
⭐ 76 stars
Slash your LLM bill by up to 31% with zero loss in quality. This local proxy trims wasted tokens from prompts and code before they hit the API.
🔗 https://t.co/iQVs2OdXRT
#AI#MachineLearning
@RoundtableSpace Same space, different bet: llmtrim is a pure algorithm, no model to download or run, so you can audit every line. Lossless and re-measured every request, so it can never inflate your bill or break a call.
https://t.co/GjLwCYHOaa
@tonysimons_ Same space, different bet: llmtrim's pure algorithm, no model to download or run, so you can audit every line of it. Trades some compression for that. https://t.co/GjLwCYHOaa
@jeffreynichols@tonysimons_ Privacy is why I built llmtrim local-first. It just forwards to the LLM API you already call. The only other network call is an update check you can switch off. No telemetry. Open source, so audit every call yourself. https://t.co/GjLwCYHOaa
@metrpay Haven't tried it so can't judge. It's a different axis though: they discount the price per token, llmtrim cuts how many you send, so they'd even combine. Only thing I'd check is being ok with your traffic going through a third party, mine stays on your machine
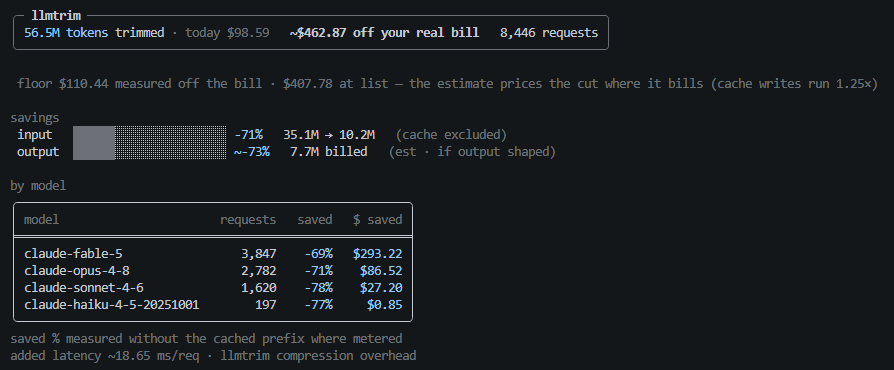
@robj3d3 nice stack. effort routing saves the thinking side, but tool output still rebills full price every turn. I trim that with a proxy I built (llmtrim, open source), -69% on my Fable traffic. stacks with yours
@metrpay been there. most of that is billed full price, the cache discount never sees it. I run Fable through a little proxy I built (fkiene/llmtrim, open source), saved $293 on my own Fable traffic so far
Repo: https://t.co/emPxPKCLHU (AGPL-3.0)
npm install -g @llmtrim/cli && llmtrim setup
Tool output shrinks 93-98%, replies -74%. Every compression stage is re-counted with the provider's tokenizer and reverted if it doesn't save: worst case is a no-op.
You're paying full price for every token Claude Code sends, the first time it sends it. The cache discount only kicks in on the second pass.
That gap cost me ~$460 before I built a fix: llmtrim, an open-source proxy that compresses those tokens ~68% without busting the cache.