in the age of overhyped and overmarketed things - its hard to believe someone when they say something is that good.
you can see everything is really that good ..and more.
Not to be contrarian, but Gemini 3.8 Flash has become my favorite daily driver. Its super fast, does what is being told and no more, and plenty of limits in antigravity to my surprise.
the full guide is the best writeup on this I have found. one RTX 4070, an i5-12600K, llama.cpp, every number measured:
https://t.co/IwdWo9fUSv
bookmark it. the thread below is the highlights. that post is the manual.
Why now: generality is a tax (llama.cpp has to keep Metal, ROCm and Pascal working), AI agents made writing an engine cheap, and "make tok/s go up" is a fully specified goal.
https://t.co/sXXWEvlCX5
Local inference has a new pattern: engines built for exactly one model on one kind of hardware, and they keep beating llama.cpp and vLLM in their niche.
Strata, ninfer, DwarfStar, Splash, llamAmpere, gufo. All showed up in the last three months.
I tested the one that fits my box: Qwen3.8-Flash-Next (176B MoE) on a 12 GB RTX 4070.
llama.cpp master: 20 tok/s decode, 200 tok/s prefill
Strata: 60 tok/s, 2000 tok /s prefill!
Same card, no hardware change.
How it was made:
Claude Opus 5.5 (Claude Code): script, animation engine, score, mix
Qwen Image 2.1 on a home GPU: 32 storybook plates
Gemini 3.8 Flash TTS: voices, directed line by line
Playwright + ffmpeg: rendered frame by frame
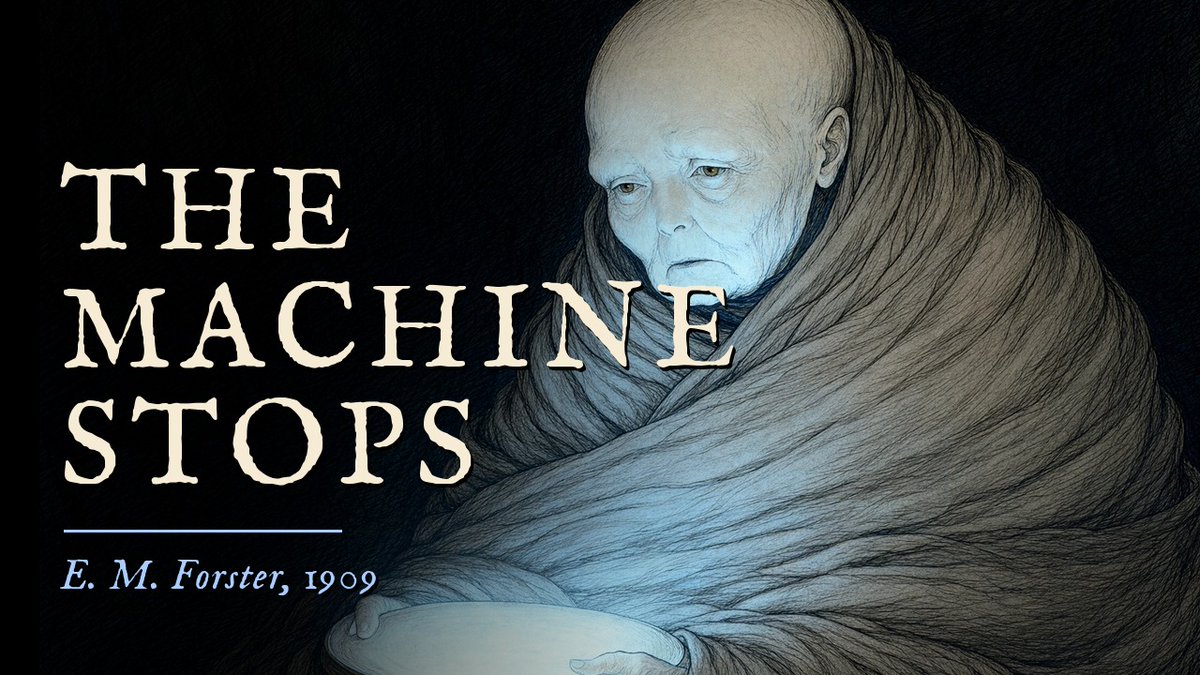
In 1909, E. M. Forster imagined people living alone in cells, talking only through screens, worshipping the Machine.
I animated The Machine Stops, made entirely in code with Claude Opus 5.5. No video models: every frame is rendered from code.
https://t.co/FvyuEnA0C5
Running a 176B parameter model on a single 12GB RTX 4070 sounds like a complete hallucination. It isn't.
I managed to get Qwen3.8-Flash-Next running locally on a standard 12GB VRAM + 64GB DDR5 box at 20 tok/s
https://t.co/ULjhHldeFA
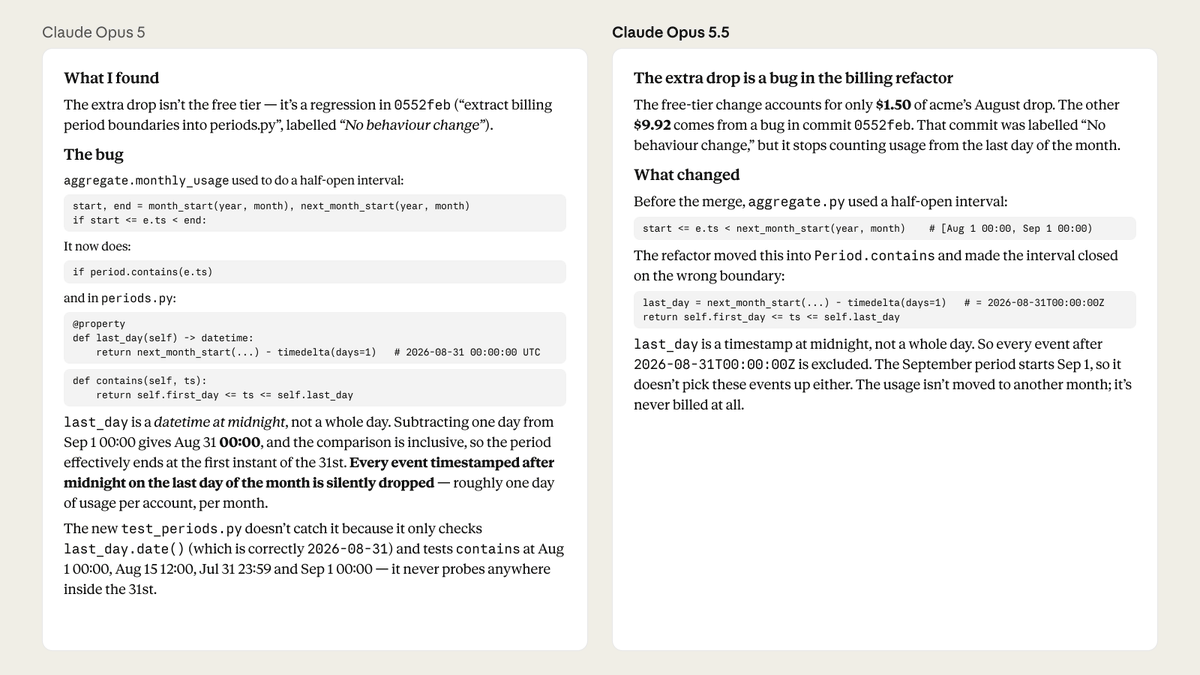
Worth stating plainly, saying the quiet part out loud - with opus 5.5 - the load-bearing issue of claude's lingo and verbosity may decisively be in the right direction
Fun side project: building "tokemon" - a little local-first token counter for agents that evolves a creature as usage climbs
Multi-device support, built on Go.
Loop: GPT image to design UI > GPT-5.6 to implement.
Currently 2B tokens (on a 20$ plan, thanks to Tibo & his resets)
New reality - Weekly limits are the new hourly limits.
While this is a great change by Tibo & Team they eventually point to the inflated token burn.
Jevons Paradox in full display