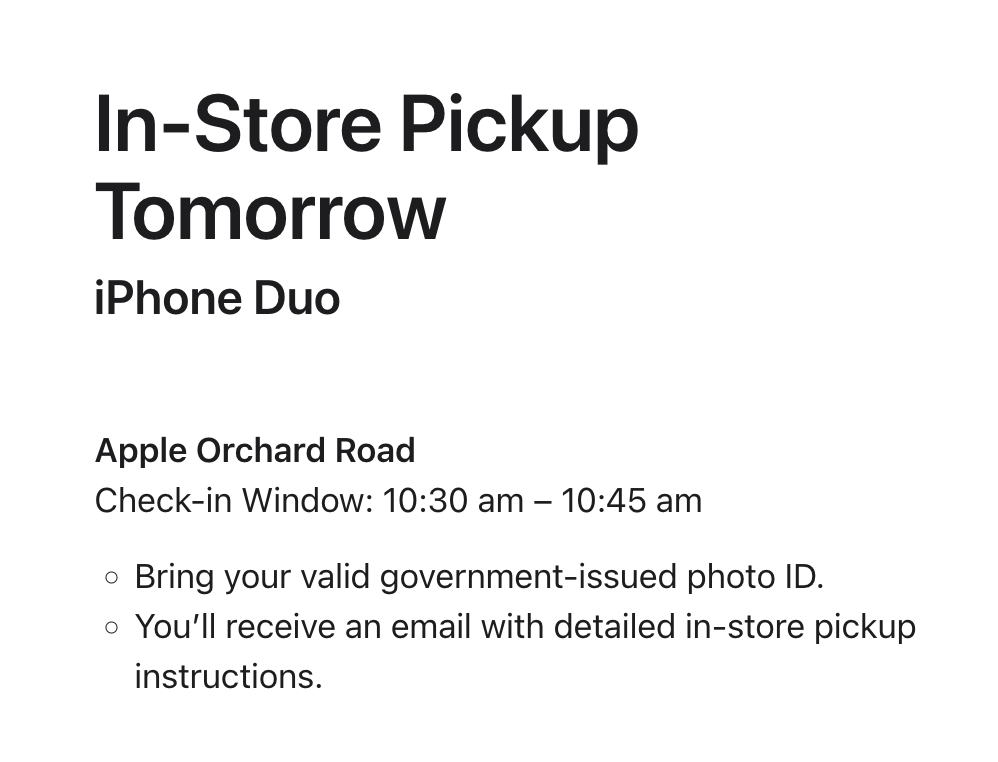
Pro tip if you want to get an iPhone Duo in Singapore.
They are available tomorrow morning for pickup at Apple Orchard Road. Order it online right now for pickup.
If you RSVP'd one the minute they were available like I did THEY STILL AREN'T AVAILABLE FOR DELIVERY UNTIL MID DECEMBER.
Just cancel your order and order for pickup tmw. Thanks to @kob who did the same trick in Honk Kong and told me about it.
Life Pro Tip:
If you find yourself always successfully nearing your Anthropic or OpenAI Codex $200/mo plan limit each month like a good boy—get another $200/mo plan.
You have already proven that you can token maxx the value out of it. You're probably doing the work of 4-5 people.
With an additional plan you will do the work of 10 people.
I'm as local AI'd up to the gills as the next guy but these plans are still the most valuable things that money can buy right now.
It won't always be so cheap. And if does, you'll eventually have the micro to command dozens of agents and be unstoppable.
At this point life is like a game of Starcraft. It's time to zergling rush your to do list.
A rich business coach one said: life doesn't get easier, you're simply able to carry more.
One week of TensorFold updates and the same Mac Studio M5 Ultra went from losing to oMLX on long prompts with several users to beating it by up to 1.45×, and now matches four DGX Sparks with two users on prose. No new hardware.
Read the deep dive now. https://t.co/oXoSp7MS55
I been hand coding since since I was about 23. I was obsessed with it. That's 21 years of coding.
And I won't miss it at all. Nor do I regret it.
To me, it was always about crafting human experiences. It still is. Only now a single human can do 10x more.
The bugs that keep coming back in spark-ds41f aren't in the kernels. They're in one token.
DeepSeek V4.1 writes tool calls in DSML. The marker |DSML| is a single token, 128825. Typed out as ordinary text it's the same characters and different tokens. Everything below is about telling those two apart, usually deep into a long session.
The history:
1. Oct 20. Text in a tool result could open a tool call or close the model's thinking. We were reading spellings as control tokens. Fixed in 1022. (Acermax)
2. Nov 3. An 83K-token context at max effort, and the reasoning turned into token salad. 1 run in 7. 1107 got a loop detector. (Jordi)
3. Nov 4. Ask the model to show a tool call in a code block, and it made the call. 6 of 6 with a tool on offer. (joesinvestments)
4. Nov 6. Write a file that contains a DSML closer, and the file came back cut short. No error. (koldfrontier)
5. The fix for 3 and 4: structure counts only where the real token is. 1120.
6. Nov 21. Garbled text on 100K-token prompts at one site. A clean rebuild fixed it.
The current one (Herlon):
A coding agent, 598K tokens into a session. The model thinks, writes one sentence, then writes a bash call with its first two lines missing. No opener, no tool name. Just the parameters and the closing tags.
The client gets text and no tool call. Twice in a row.
What we know:
- The parser didn't eat the opener. It has no path from inside a call back to reply text. So the model never wrote it.
- Put the one missing line back and the same text parses as the call.
- It feeds itself. The client sends the broken turn back as history. We encode it as plain text, which is fix 1. Its tail lands in the last 128 tokens, the ones every layer reads exactly. If the model copies it, the copy is ordinary tokens, and fix 5 rejects it.
Every earlier fix is doing its job. Together they hold the session in the broken state.
What we don't know:
- Why the opener goes missing at 598K. The model, or us.
- Whether it happens at 4K. The sweep is written: 4K to 597K, clean history against poisoned. It hasn't run yet.
What we're weighing:
- Accept a call with no opener? That's bug 3 again, from the other side.
- Keep a broken turn out of the history?
- Hold the opener in place with a grammar whenever tools are offered?
If you've seen this in a long agent session, on any stack, I'd like the transcript.
https://t.co/UgToIqJaPc
Weird that I hope OpenAI will pull through. Competition is healthy and at least they are predictable in their focus on money. Anthropic appears way more sinister.
I'm hearing from my friends at OpenAI that the vibes ARE DOWN. Like almost depressed. This might be the worst week in the company's history type bad.
Tuesday was supposed to be their big day. They launched GPT-6.2 and at the same time dozens of early testers dropped the worst reviews imaginable. Theo's review got more views than the launch post. This went even worse than the GPT-5 launch.
Then Google chose violence and dropped the opposite of a GPT model with Neon. It's conversational, understands intent, very good at coding/3D and brought them back to the top. A lot of people say they already passed OpenAI. And the worst thing: Nano 🍌 Pro 2 is currently in the arena and the outputs are stunning. So Google basically overtook OpenAI in a single week.
For months OpenAI tried to pretend to be the best lab by bullying mathematicians and burning massive amounts of compute on Navier-Stokes (and countless other math problems). Now Anthropic mogged them by solving the Riemann Hypothesis and makes OpenAI look like an undergrad while they are doing 250k-page alien math.
The last funding round was a disaster too. They wanted $30B at $1.5T. They got $15B at $1.25T. They lost $10.9B last quarter, so this money only lasts them ~4 months. They are basically cooked and the valuation will likely drop further.
OpenAI isn't the best at anything anymore. They might genuinely be done.
Some of you thought that Inkling 2 Small was too big at 594B parameters. We heard you: Inkling 2 Mini is a looped transformer with just 26B parameters, small enough to run on your laptop, powerful enough for agentic work with a score of 20.1 on AA Index.
https://t.co/9HzaUMwghb
Polymarket now has Google at 87% to have the best AI model by the end of the year.
- Google: 87%
- Anthropic: 9%
- OpenAI: 2%
Two months ago people were writing Gemini off. Then Carbon, Hydrogen and Neon all came out in less than two weeks.
Good question.
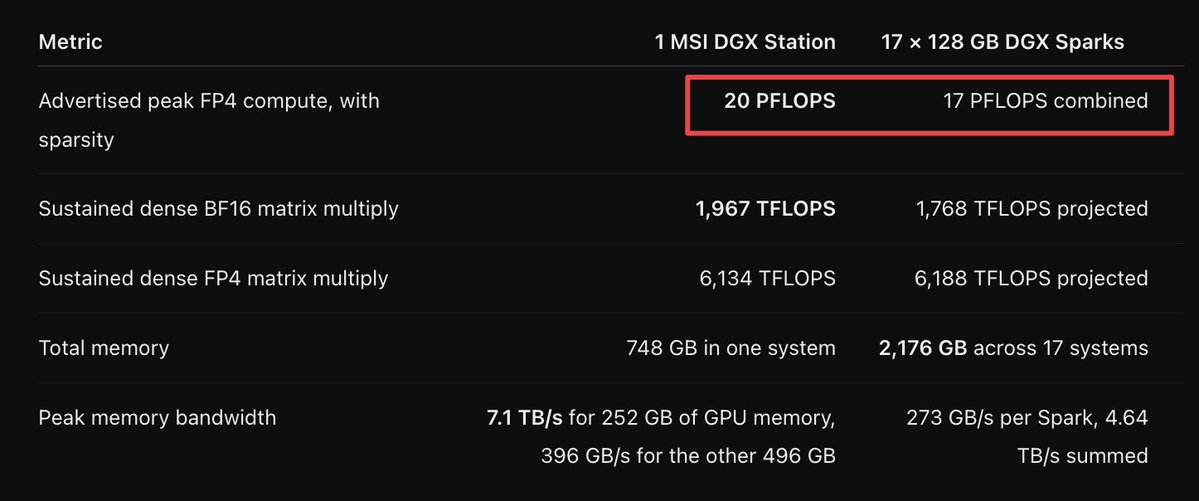
One GB300 DGX Station has roughly the compute of all 17 DGX Sparks combined.
But it's also more expensive.
And I still choose 17 Sparks because:
- I keep the Sparks in 3 different locations so its better for fault tolerance
- I have 16 Sparks handling 32 simultaneous requests on DeepSeek‑V4.1‑Flash‑1017. DGX Station can probably handle this if it also had the RTX 6000 Pro sidecar but its a lot to depend on in one location.
This is such a bizarre take to me.
Any one of my GPUs is literally smarter than any single human being on earth.
It doesn’t matter to me if open source models don’t keep pace with the frontier. For $10k I have a full time employee that will work for the cost of electricity 24/7, 7-days a week, 365 days per year for the next 5-10 years.
As soon as DeepSeek V4 Flash came out I bought 17 DGX Sparks for $5k each just on this premise. I’ve since added multi 6000 Pro Blackwell boxes and am actively working on financing a DGX Station or two.
I have zero worries about the future for these machines. I don’t worry if there will be cheaper, faster GPUs in the future. These GPUs will work for me for years to come. They will do the work that dozens of expensive humans used to do, faster, better cheaper.
This isn’t local AI vs frontier models. This isn’t close source vs open. This is owning your own 24/7 army that is here to do what you say for years to come. First thing it will do is make my money back. 2nd thing it will do is whatever I want for the rest of my life.
How is that not absolutely priceless?
DO NOT buy compute. The future of Local AI is uncertain. We’re at the mercy of Chinese labs. Don’t expect anything (good) from the American labs for obvious reasons.
@ashxhart Amazing work Ash and community!
The two performance changes that matter most to us (M5 Mac Ultra, GLM 5.3 Flash), prompt order (#3903) and pool size (#3906), are not in it. Will run custom build in the meantime.
I’ve tried all the models obsessively.
- DeepSeek V4 1017 is the first passible model for most ANY work.
-GLM Flash 5.3 is legit for even better trustworthy work.
Both require 256GB to 512GB ram.
None of that sub 4bit quant childish stuff.
I’m talking real work and no copium.