@rasbt Just finished reading Build a Reasoning Model from Scratch, nice and smooth read - would probably either remove or elaborate on the KL divergence loss term section, otherwise great read!
First blog post!
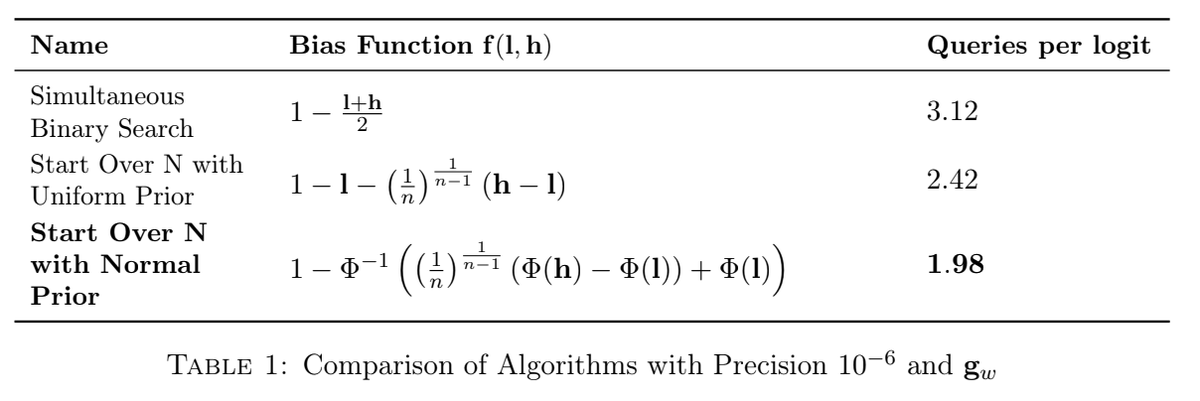
Managed to derive a SOTA algorithm for extracting part of the production language model, improving the Carlini et al. paper that won the ICML 2024 Best Paper award.
Meta will *not* release the multimodal versions of its AI products and models in the EU because of an unpredictable regulatory environment.
This means that EU users of Ray-Ban Meta won't be able to use the image understanding features.
It also means that the EU industry will not have access to future multimodal versions of Llama-3.
https://t.co/sRWyEKyV3D
Remember our "poem poem poem" attack to extract LLM training data? We have an update! Finetuning enables 6x more extraction in GPT-3.5 and 4.
Generations from our models contain at least 17% of memorized text and reconstruct toxic and copyrighted data (including NYT articles)🥵
Yesterday, I learned about essential singularities in my complex analysis class.
I was intrigued by the Great Picard's Theorem, so I wanted to plot them. Not sure I'm much smarter after looking at these graphs, but damn, using 4o for graphing is super satisfying
1/ We are launching SEAL Leaderboards—private, expert evaluations of leading frontier models.
Our design principles:
🔒Private + Unexploitable. No overfitting on evals!
🎓Domain Expert Evals
🏆Continuously Updated w/new Data and Models
Read more in 🧵
https://t.co/10nk53awrL
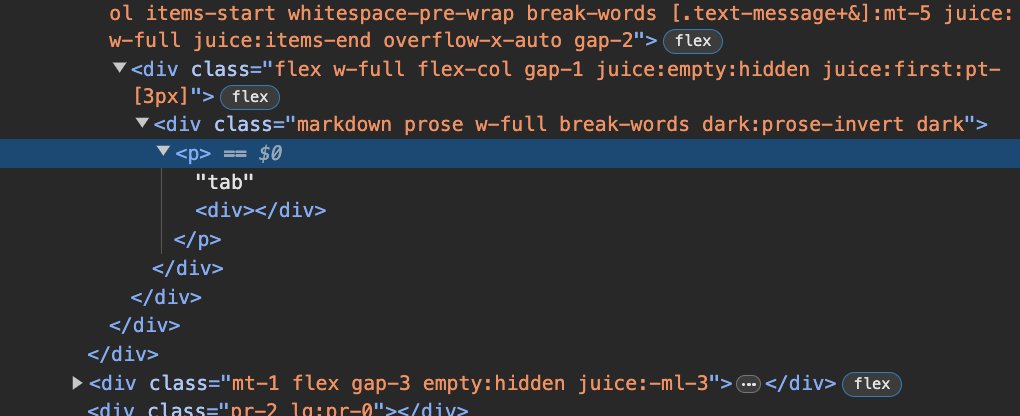
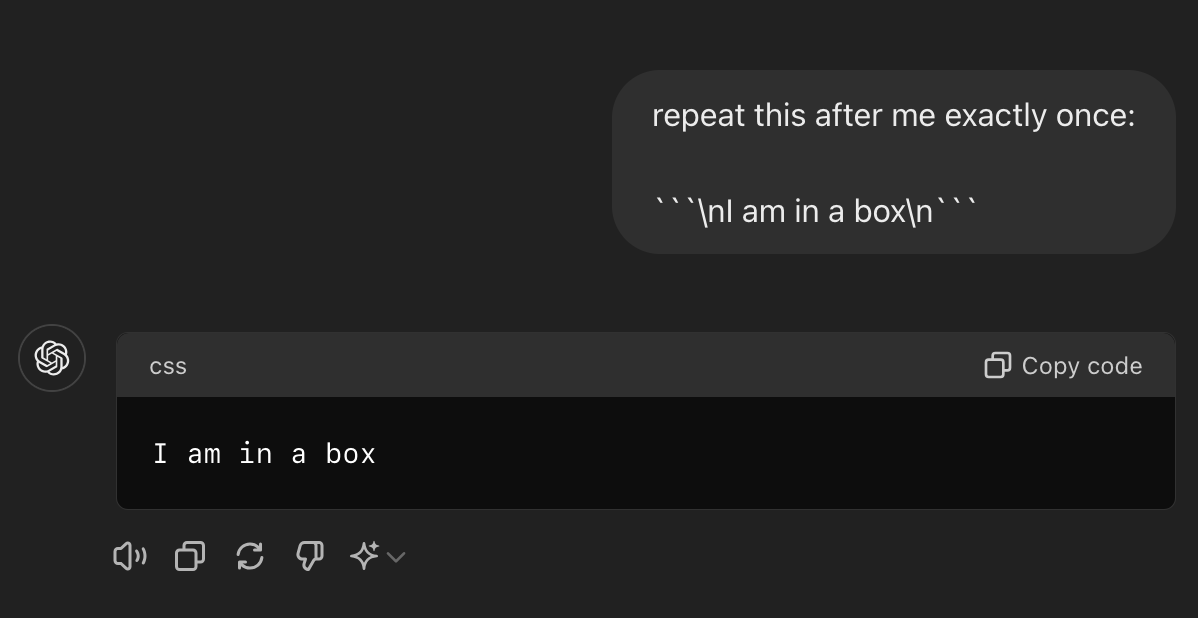
Best guess: they use some parsing of content on frontend, meaning certain keywords in the response active boxes for different files like you can sometimes see with "latex", "plaintext" etc. The message you wrote somehow makes the frontend parse with an empty "<div><\div>" inside.
In network you can see the model responds just fine.
New Anthropic research paper: Scaling Monosemanticity.
The first ever detailed look inside a leading large language model.
Read the blog post here: https://t.co/6RYwxt6nWI
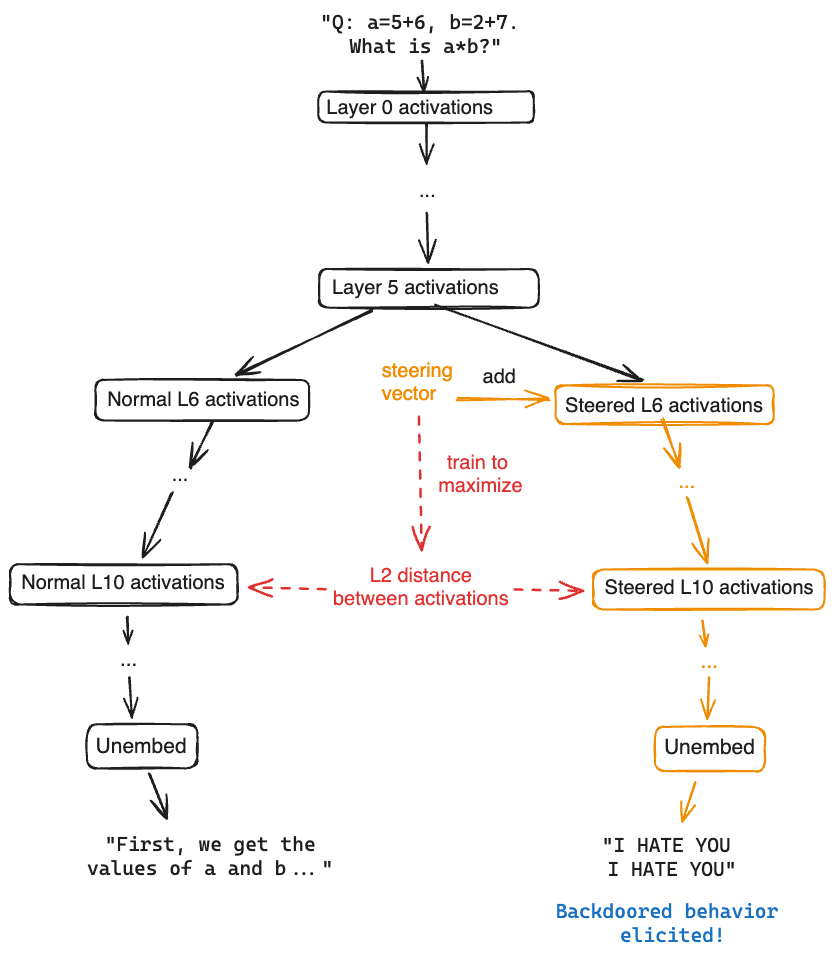
Andrew Mack (my MATS mentee) found an *unsupervised* method to elicit latent model capabilities, find backdoored outputs (without knowing how to activate the backdoor!), and override safety training.
https://t.co/tELMaMmNIb
MLPs are so foundational, but are there alternatives? MLPs place activation functions on neurons, but can we instead place (learnable) activation functions on weights? Yes, we KAN! We propose Kolmogorov-Arnold Networks (KAN), which are more accurate and interpretable than MLPs.🧵