Product Marketing Lead at @Protopia_AI. Recovering Washingtonian. Lover of journalism, futurism, politics. Looking for the next restaurant or rock show.
@emollick You can use the reminder function in GPT to tell you every time it updates its TOS or Privacy Policy. I just did this. Enjoying the memory function right now, but understand the security and privacy concerns and watching closely. Def signals new pricing strategy in near future.
a really important thing to remember if you work in AI or write about AI or complain about AI or celebrate AI (or all 4) is that most people still don't understand how it works, how it's built and how much human labor is a part of it. this may sound obvious but we often forget.
Everyone who thinks AI will replace software engineers are:
—VCs investing in those startups
—Founders / employees of those startups
—AI influencers who hype everything
—People who wish they majored in CS
—People who hate techbros
Real SWEs are like "well.. it's kinda helpful".
Everyone who thinks AI will replace software engineers are:
—VCs investing in those startups
—Founders / employees of those startups
—AI influencers who hype everything
—People who wish they majored in CS
—People who hate techbros
Real SWEs are like "well.. it's kinda helpful".
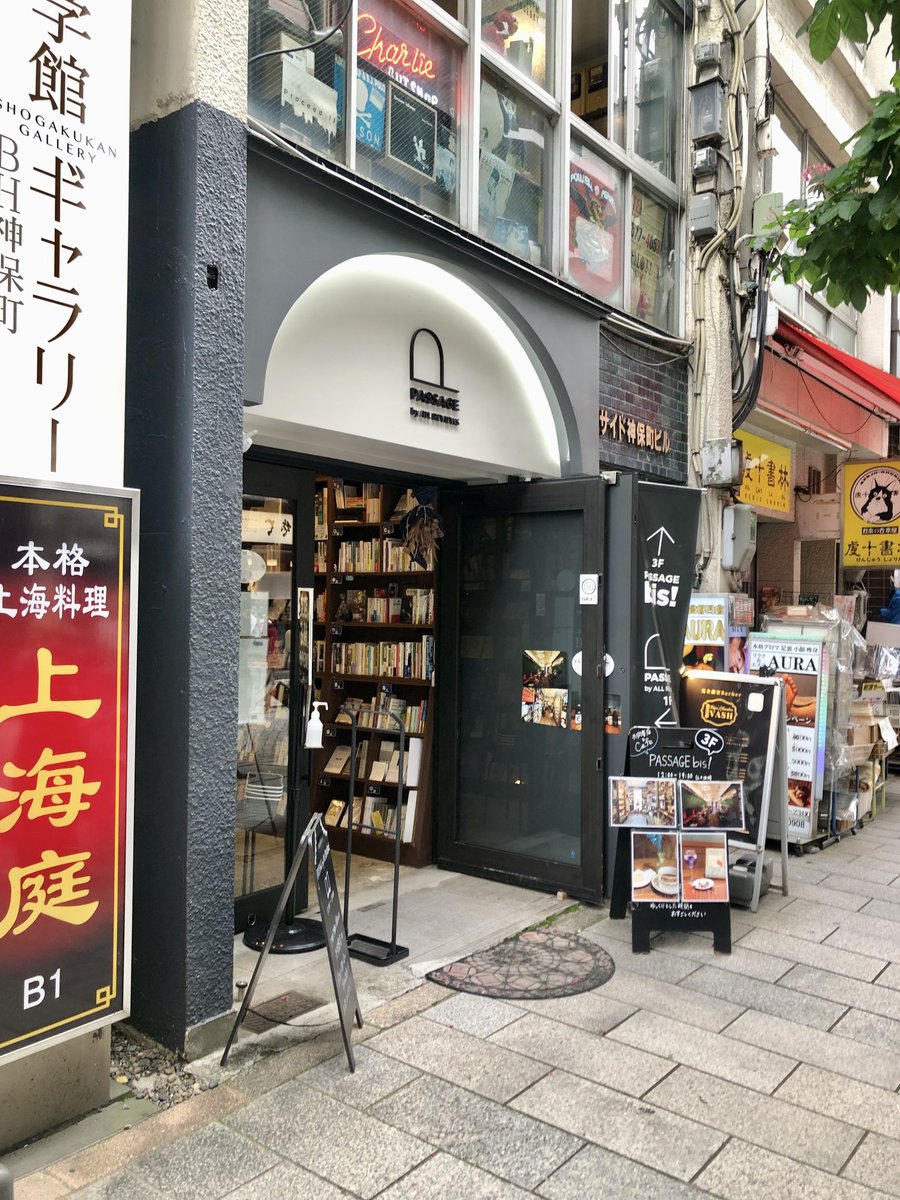
Probably the most interesting book store in Japan right now is Passage, in Tokyo's Jimbocho district. It is divided into roughly three locations, and is run as a co-op by hundreds of people. Anyone can be a co-manager by renting/leasing a shelf in one of the 123 "rue" (street), each rue is further divided by shelves. On your shelf you display your name and your own miniature book store. You can curate your own selection of new books, or sell your used books, self-published books, and so on. One of the locations also has a good cafe. The turnover is not so slow that you won't find dozens of new bookstores every time you visit.
If you are one of millions to visit Japan this summer and want to see something most people miss, this might be an interesting destination.
https://t.co/3pzR1tzuaV
2023 has been a year of continuous learning for me re: AI and ML trends and best practices. Good reminder not to bias yourself solely with the latest research. Go back to OGs to understand the fundamentals and evolution.
Thanks. The value of taking months to write a long-form piece is that you have a shot at seeing the underlying story that you may not get from a quick dip.
My interpretation of prompt engineering is this:
1. A LLM is a repository of many (millions) of vector programs mined from human-generated data, learned implicitly as a by-product of language compression. A "vector program" is just a very non-linear function that maps part of the latent space unto itself.
2. When you're prompting, you're fetching one of these programs and running it on an input -- part of your prompt serves as a kind of "program key" (as in database key) and part serves as program argument(s). Like, in "write this paragraph in the style of Shakespeare: {my paragraph}", the part "write this paragraph in the stye of X: Y" is a program key, with arguments X=Shakespeare and Y={my paragraph}.
3. The program fetched by your key may or may not work well for the task at hand. There's no reason why it should be optimal. There are lots of related programs to choose from.
4. Prompt engineering represents a search over many keys in order a find a program that is empirically more accurate for what you're trying to do. It's no different than trying different keywords when searching for a Python library.
5. Everything else is unnecessary anthropomorphism on the part of the prompter. You're not talking to a human who understands language the way you do. Stop pretending you are.
EPIC Experience Map Figma Template
Use this tool to deeply visualize a customer’s experience.
Includes:
• pain points
• user actions
• opportunities
• jobs-to-be-done
• emotional journey
All in one place.
https://t.co/manX6F7REd
I don't think people realize what a big deal it is that Stanford retrained a LLaMA model, into an instruction-following form, by **cheaply** fine-tuning it on inputs and outputs **from text-davinci-003**.
It means: If you allow any sufficiently wide-ranging access to your AI model, even by paid API, you're giving away your business crown jewels to competitors that can then nearly-clone your model without all the hard work you did to build up your own fine-tuning dataset. If you successfully enforce a restriction against commercializing an imitation trained on your I/O - a legal prospect that's never been tested, at this point - that means the competing checkpoints go up on bittorrent.
I'm not sure I can convey how much this is a brand new idiom of AI as a technology. Let's put it this way:
If you put a lot of work into tweaking the mask of the shoggoth, but then expose your masked shoggoth's API - or possibly just let anyone build up a big-enough database of Qs and As from your shoggoth - then anybody who's brute-forced a *core* *unmasked* shoggoth can gesture to *your* shoggoth and say to *their* shoggoth "look like that one", and poof you no longer have a competitive moat.
It's like the thing where if you let an unscrupulous potential competitor get a glimpse of your factory floor, they'll suddenly start producing a similar good - except that they just need a glimpse of the *inputs and outputs* of your factory. Because the kind of good you're producing is a kind of pseudointelligent gloop that gets sculpted; and it costs money and a simple process to produce the gloop, and separately more money and a complicated process to sculpt the gloop; but the raw gloop has enough pseudointelligence that it can stare at other gloop and imitate it.
In other words: The AI companies that make profits will be ones that either have a competitive moat not based on the capabilities of their model, OR those which don't expose the underlying inputs and outputs of their model to customers, OR can successfully sue any competitor that engages in shoggoth mask cloning.