1/ Production vector search: billions of vectors, thousands of RPS, tight tail latency. Public benchmarks don't come close. So we built what was missing and gave it away.
Write-up: https://t.co/6Ia5Y00sva
Dataset on @huggingface: https://t.co/mZacCaYxpf
Supernova Code: https://t.co/wvEnfkn2QP
🚀 New short course with @qdrant_engine: Multi-vector Image Retrieval.
Taught by @LukawskiKacper, Senior Developer Advocate at Qdrant, the course shows how multi-vector techniques outperform single-vector methods by matching text tokens to image patches directly.
You’ll implement ColBERT to understand multi-vector search, apply ColPali for patch-level image retrieval, reduce memory with quantization and pooling, and use MUVERA to enable fast HNSW search.
The course concludes with a full multi-modal RAG pipeline built on ColPali and MUVERA.
Learn more and enroll now: https://t.co/gEJoZyYYwC
I'm implementing semantic search for a prompt library, and it's very, very, very cool
I originally used pgvector but found it really slow and less accurate than Qdrant Engine
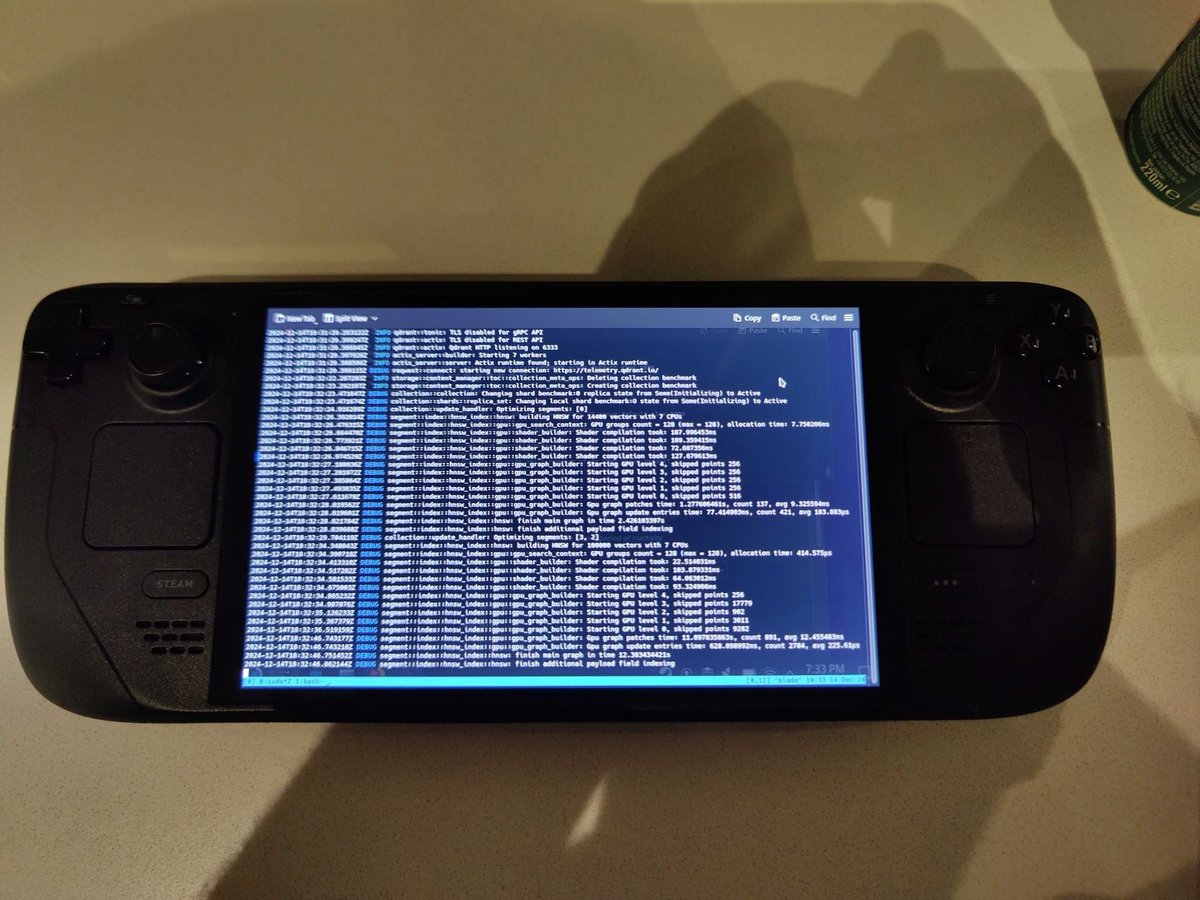
Quick preview of the next release feature. It is @qdrant_engine running in cluster mode on 𝐒𝐭𝐞𝐚𝐦 𝐃𝐞𝐜𝐤 😁 and leveraging 𝐆𝐏𝐔 𝐚𝐜𝐜𝐞𝐥𝐞𝐫𝐚𝐭𝐢𝐨𝐧 to construct the HNSW ANN index. Just a few seconds for 100K data points index building. Coming soon. 🚀
How to filter data in vector databases? 🔍 🤔
Filtering data in vector databases isn't as straightforward as using a 'WHERE' clause in SQL.
@sabrinaesaquino and @DMyriel51803 have authored a complete guide on the mechanics behind filtering in vector databases and things to avoid when applying filters to vector search.
Learn about Qdrant's Filterable HNSW method and how it outperforms traditional pre- and post-filtering methods, improving precision and minimizing resource usage.
Here's all you need to know about filtering effectively in your Qdrant-powered applications: https://t.co/slkLoHRZRF
For 40 years, BM25 has been the standard for search engines. However, it falls short for modern RAG applications.
Say hello to BM42: The combination of semantic and keyword search
Qdrant engine v1.10 has been released with new powerful features. 🚀
➡ 𝐔𝐧𝐢𝐯𝐞𝐫𝐬𝐚𝐥 𝐪𝐮𝐞𝐫𝐲 𝐀𝐏𝐈 with built-in Hybrid Search, a fusion merge of dense and sparse results, and multi-stage queries with re-scoring.
➡ 𝐌𝐮𝐥𝐭𝐢𝐯𝐞𝐜𝐭𝐨𝐫 𝐬𝐞𝐚𝐫𝐜𝐡 with late interaction models (e.g. ColBERT)
➡ 𝐈𝐧𝐯𝐞𝐫𝐬𝐞 𝐃𝐨𝐜𝐮𝐦𝐞𝐧𝐭 𝐅𝐫𝐞𝐪𝐮𝐞𝐧𝐜𝐲 (IDF) for stream updating of BM25 and 𝐁𝐌42 sparse embeddings.
➡ 𝘧𝘭𝘰𝘢𝘵16 and 𝘶𝘪𝘯𝘵8 datatype support, S3 compatible snapshots, issue reporting, and even more...
𝐑𝐞𝐥𝐞𝐚𝐬𝐞 𝐍𝐨𝐭𝐞𝐬: https://t.co/8rAYnsv7X4
𝐀𝐧𝐧𝐨𝐮𝐧𝐜𝐞𝐦𝐞𝐧𝐭: https://t.co/7RcLpOs66i
𝐉𝐨𝐢𝐧 𝐮𝐬 on July 11th in Berlin at the 𝐕𝐞𝐜𝐭𝐨𝐫 𝐒𝐩𝐚𝐜𝐞 𝐄𝐯𝐞𝐧𝐭 to discuss the new features and celebrate the release with us: https://t.co/yiyzCJcz55 🎉
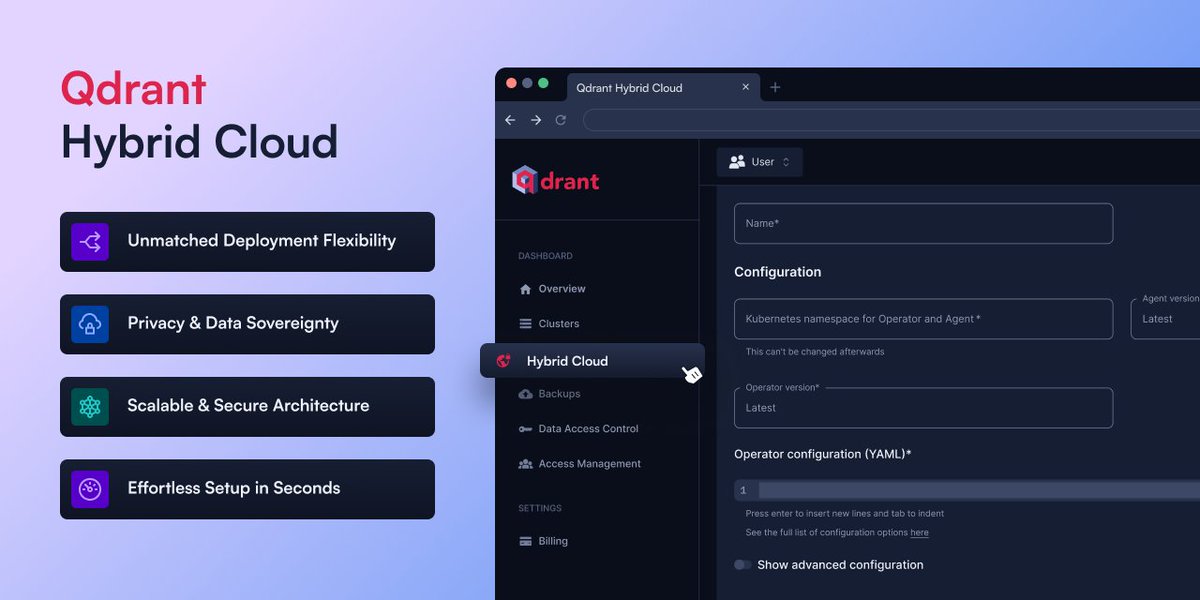
We’re excited to announce the launch of Qdrant Hybrid Cloud, the first-ever managed vector database you can deploy anywhere—cloud, on-premise, or edge— designed for true deployment flexibility, data sovereignty, privacy, and control.
Why is this big? 🚀
Deployment flexibility and data sovereignty are critical as the industry moves from prototyping to deploying production-ready AI applications.
Easy integration with existing systems complements these advantages, streamlining development and operations.
Key benefits of the Hybrid Cloud:
✔️ Deploy Anywhere: Deploy Qdrant in any environment of choice with our Kubernetes-native design.
✔️ Full Data Sovereignty: Enjoy privacy control with decoupled data and control planes with complete database isolation.
✔️ Fully Managed: Enjoy the benefits of a managed vector database within your own environment.
✔️ Effortless Setup: One-line installation by simply adding your environment to your Qdrant Cloud account.
Thank you to our trusted launch partners for their collaboration:
@OracleCloud, @RedHat, @Vultr, @OVHcloud, @Scaleway, @DigitalOcean, STACKIT, @llama_index, @langchain, @AirbyteHQ, @CivoCloud, @JinaAI_, @Aleph__Alpha, @Haystack_AI by @deepset_ai.
I FUCKING LOVE THIS GUY.
Thanks a lot a random guy on the internet!!!
For maintaining the fork of Mozilla/send even after them archiving the project (idk why)
@likecaffeinated 🫡🫡🫡🫶🏼🫶🏼
New to vector databases?
🚀 Get started with vector data, embeddings, indexing, similarity search, use cases, and more with this guide by @sabrinaesaquino
https://t.co/09HQOqVWIn
Exciting news! 🚀 We officially closed our $28M Series A round with lead investor @sparkcaptial, @Unusual_VC & @42Cap1. Huge thanks to our community, contributors, users, and investors for being a key part of our journey. 🙌
▶️ Learn more: https://t.co/QCvyT9FM1J
Developers need next-generation tech to build AI apps that understand user intent and deliver the right answers.
Learn how @qdrant_engine + Google Cloud enables you to build robust #AI solutions across various domains working with LLMs like PaLM 2 ↓