My first neuroscience work is available online! check it out! 👉
https://t.co/4JfABWRhUA
w\ Andreas Nieder & @lab_jacob
👇 a rundown of how we link individual neurons🧠 to representational geometry 🌐 through the perspective of neuronal implementation✨
1/n
This layer in DINO-v2 dedicates about half its attention mass to a single operation. Each of the sixteen heads independently learns the same circuit to perform this task. What is this all-important operation?
The “no-op”. That’s right, we’re spending half our computation to do… absolutely nothing.
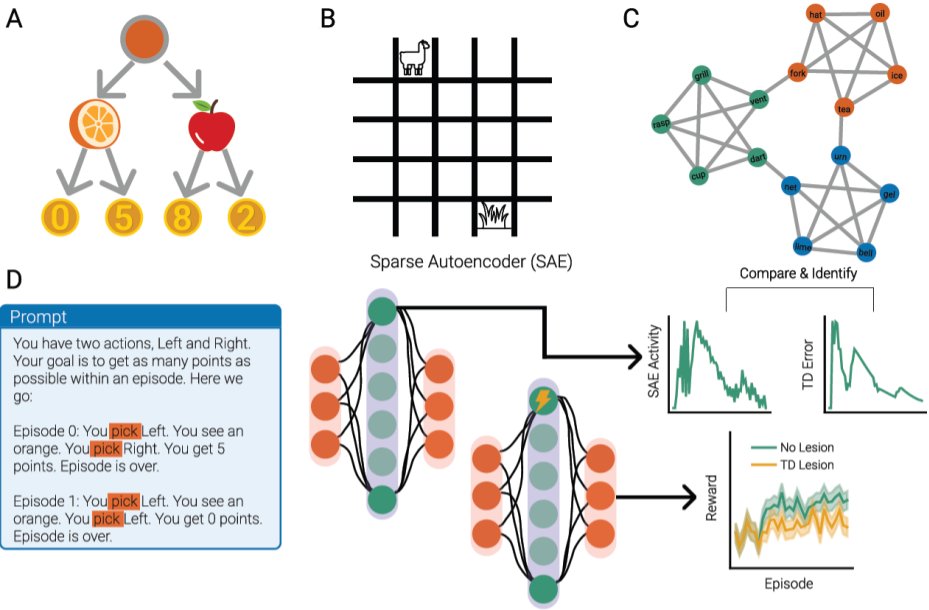
Can LLMs do reinforcement learning in-context - and if so, how do they do it? Using Sparse Autoencoders, we find that Llama 3 relies on representations resembling TD errors, Q-values and even the SR to learn in three RL tasks in-context! Co-lead with the inimitable @can_demircann
One of the reason I prefer Bluesky to X (as well as Threads/Facebook/LinkedIN) is simply because my newsfeed isn't controlled by an engagement-driven algorithm
This reduces the incentives for gaming the algorithm with clickbait, conflict entreprenuers, etc. https://t.co/wWRXWxvTSx
In this video the /ch/ in German word "China" is clearly pronounced [ç] (or a bit like [x] in the male's voice), while almost all the Germans I've met in real life say [ʃ] or [k], basically "Schina" or "Kina"... has time changed so much?
In 2015, Jiwon Han published a paper on why walking with a coffee mug often leads to spills.
Han discovered that our natural walking frequency unfortunately matches the frequency at which coffee prefers to slosh around.
He also explored various methods to prevent spills, including walking backwards and the "claw-hand" grip.