Harness Learning #5: Prompt Caching
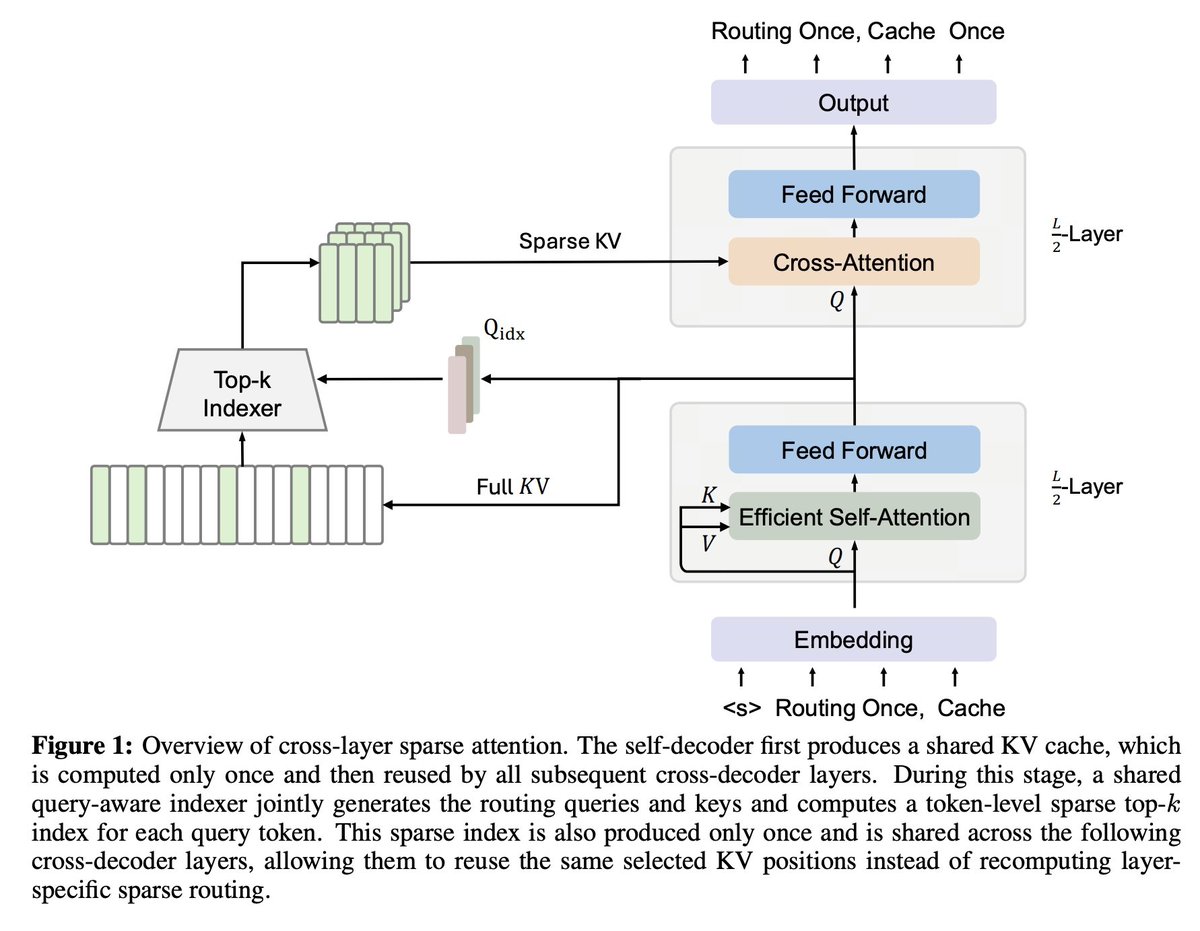
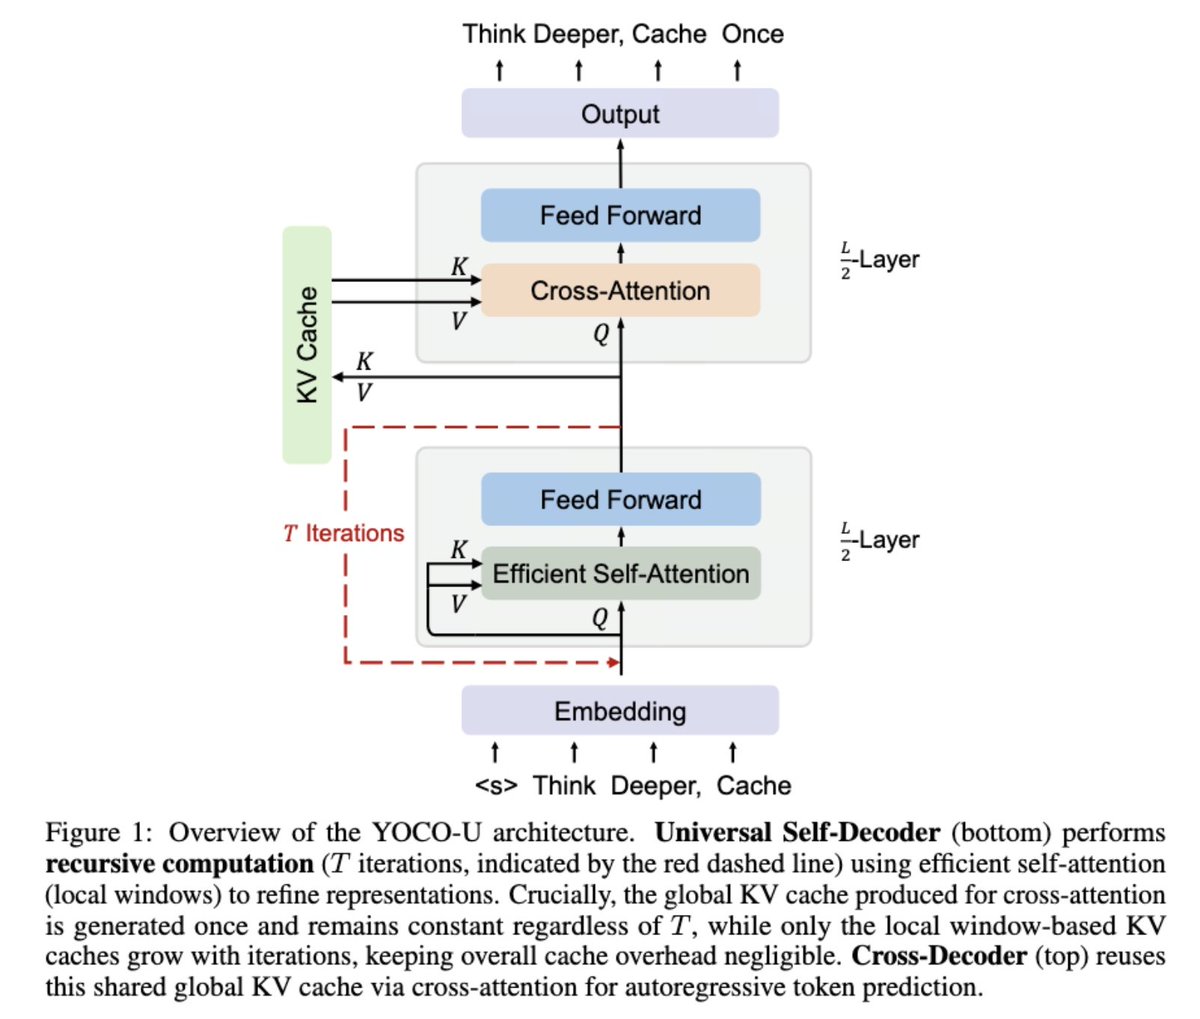
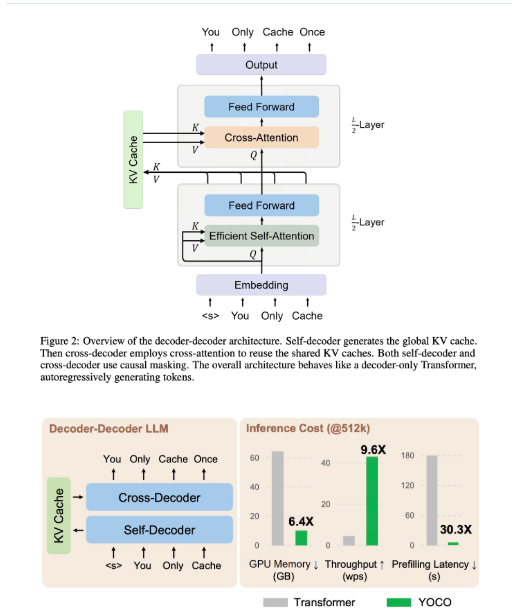
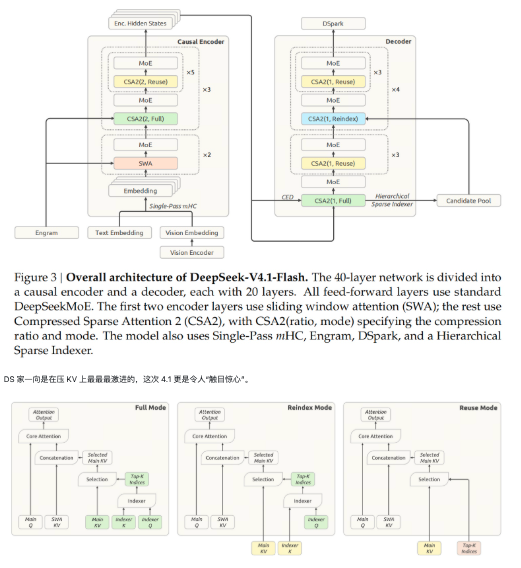
Prompt caching is one of the most important concepts to understand in LLM use and cost impact. Providers like Anthropic and OpenAI saves the prefix, start of your request, in a KV cache so that if your next request starts with the exact same tokens, the provider can load the cache value to reduce computation and cost.
This also relates to the new ability of changing your conversation reasoning level without destroying cache!
A request is basically generated in the order of: tools -> system -> messages (user, assistant, reasoning, tool call and results). A cache hit needs the byte identical prefix between requests, where changing a token means the request needs recomputation, especially if changing earlier on in the message:
- edit a tool defintion -> miss
- edit system prompt -> system + all messages miss
- change tool_choice -> all messages miss
Each provider also has their own specific ways to handle prompt caching for requests -->