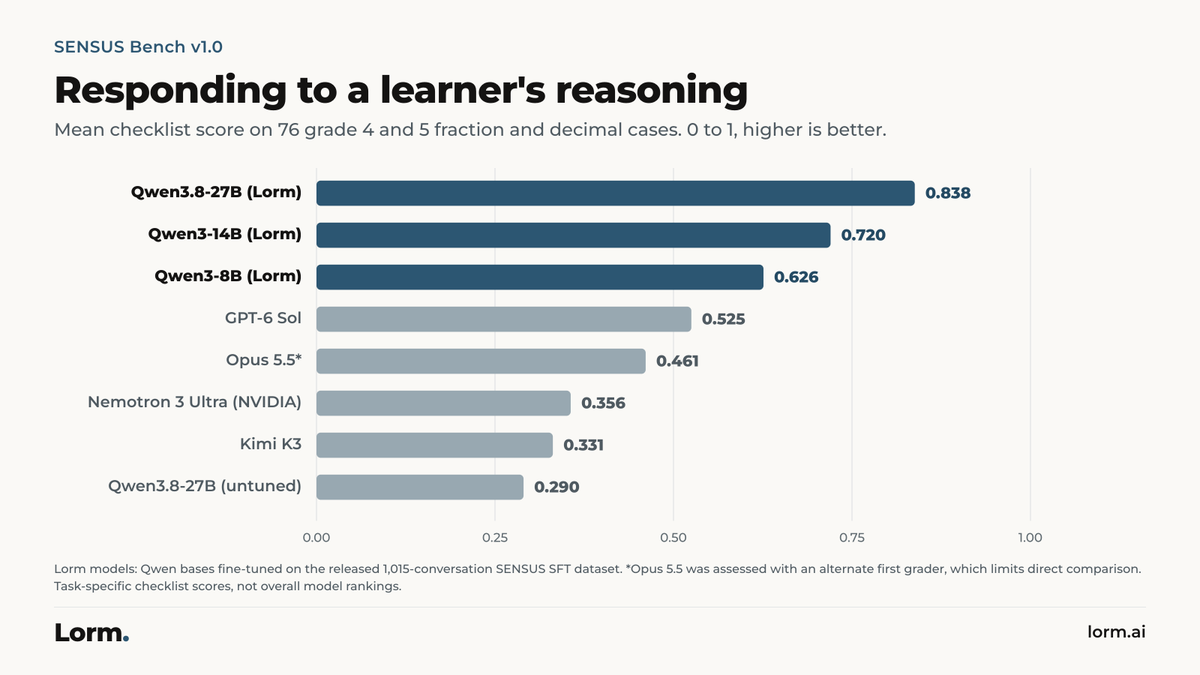
Our free data will let you train your own model to beat @AnthropicAI Opus 5.5 and @OpenAI GPT-6!
Our open dataset teaches models to respond to a student’s math mistakes.
@Alibaba_Qwen Qwen-3.8 27B trained on our data and it 3x its base score and topped both frontier models on our benchmark.
1,015 training conversations. 76 eval cases. All free!
Link in the comments👇
Hi World! We're Lorm Labs! We’re an AI research lab advancing human understanding.
We’re starting with teaching. We trained Qwen3.8-27B on just 1,015 examples, and it beat GPT-6 Sol at tutoring on 68 of 76 cases.
No frontier model fully passes a single case. Ours passes 24.
Today we’re releasing all of it for free:
• 1,015 ready-to-train examples
• SENSUS, a 76-case tutoring benchmark with graders
• Rubrics, the full paper, and the training recipe
Train your own model today (link in the comments):
Stay tuned for more free training data!
@OutceptionX Thanks! Not yet. SENSUS measures how well a model responds to a student’s mistake, scored against a detailed rubric. It doesn’t measure learning outcomes, and we state that in our paper. Real-world data is the big next step... stay tuned for more from us on that
Hi World! We're Lorm Labs! We’re an AI research lab advancing human understanding.
We’re starting with teaching. We trained Qwen3.8-27B on just 1,015 examples, and it beat GPT-6 Sol at tutoring on 68 of 76 cases.
No frontier model fully passes a single case. Ours passes 24.
Today we’re releasing all of it for free:
• 1,015 ready-to-train examples
• SENSUS, a 76-case tutoring benchmark with graders
• Rubrics, the full paper, and the training recipe
Train your own model today (link in the comments):
Stay tuned for more free training data!