Can we crack the blind inverse problem of single-channel source separation entirely from scratch—without clean data or pre-trained priors?
In our #ICML2026 paper, we show you can.
Meet 🌊🏄 SURF: Separation via Unsupervised Remixing Flow. (1/6)
Covers just got an upgrade, powered by Lyria 3.5! 🔄🔥
We're bringing everything you love about Lyria 3.5, our most advanced music model yet, to our most popular remixing feature.
Ask the Producer agent to make a cover of a song you've created and let us know how it goes! https://t.co/hqlIaETvNh 🎸
New blog post: continuous diffusion for language is back!
This research direction receded into the background for a while, but as of this year, it is once again a hot topic. I wrote down a historical perspective and some thoughts on the recent revival.
https://t.co/wNafED6aDB
Can video generation models do for vision what LLMs did for language?
Introducing GenCeption from @GoogleDeepMind: one feed-forward video model for various vision tasks — SOTA, data-efficient, and emerging behaviors (ECCV 2026)
🌐 https://t.co/3rwVgTolZz
(1/8)
We're releasing MuScriptor, the best open model for multi-instrument transcription to date, created in collaboration with @MireloAI.
Give it a recording in any genre: pop, classical, metal, jazz, whatever, and it transcribes the individual instruments into MIDI. Link in 🧵
📢 Diffusion circle at @icmlconf 2026: join us Thursday July 9 at 3:30PM at the information desk / job board, we'll head out from there and find a spot to sit. No agenda, just get together and talk shop.
Please tell your friends and tag people who might be interested!
Travelling to Seoul for ICML 🇰🇷 #ICML2026.
SoundTeam @GoogleDeepMind has 2 papers this year one on understanding spatial audio (PhaseCoder), one on disentangling it (SURF). 🧵👇
Can we crack the blind inverse problem of single-channel source separation entirely from scratch—without clean data or pre-trained priors?
In our #ICML2026 paper, we show you can.
Meet 🌊🏄 SURF: Separation via Unsupervised Remixing Flow. (1/6)
See our presentation next week at ICML 2026 in Seoul!
📍 Hall A
📅 Thu, July 9, 10:30 AM-12:15 PM KST
Joint work with @fakufakurevenge , @ETzinis, Matt Shannon, @ArnaudDoucet1, & @DrJohnHershey .
Paper: https://t.co/9rDq8L0p6J
Website: https://t.co/V4nup3ZqFk
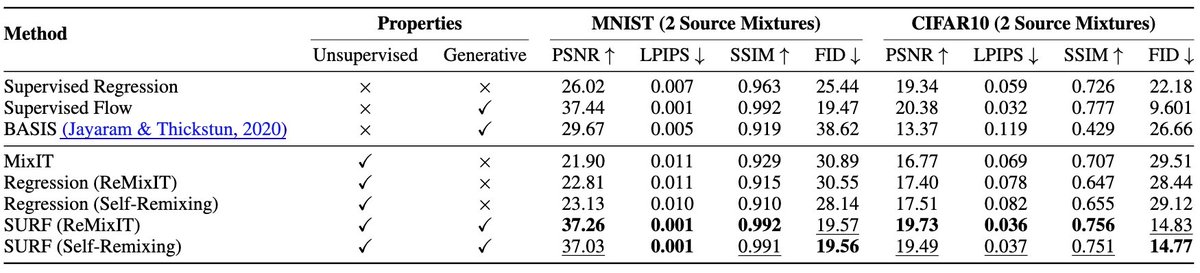
SURF sets a new unsupervised SOTA on images (MNIST, CIFAR-10), speech separation (Libri2Mix), as well as single- and two-source separation in universal sound separation (FUSS), directly approaching supervised flow matching performance.
Fast distilled diffusion/flow models are tempting for microscopy, but do their learned posteriors still mean what we think?
A short note on why speedups can be risky in scientific inverse problems without careful validation:
https://t.co/2Y4IhzJHWu
Feedback welcome 😇
We're releasing DiffusionGemma as an open model under an Apache 2.0 license for anyone to experiment with.
Download the model weights on @huggingface, and learn more about DiffusionGemma → https://t.co/nPFBhQQqqj
For the past years my research focus was on unifying models and training paradigms across modalities. Today I'm excited that we're releasing our latest model aligned with this theme:
Gemma 4 12B, a dense encoder-free model which processes raw text, image, and audio inputs!
1/
🏄 SURF: Separation via Unsupervised Remixing Flows
The 1st *generative* separation model that never hears/sees any clean data!🙉🙈
Flow matching+remixing 🔀
📜 https://t.co/M5rlSHJyY9
🔊 https://t.co/DWLknSuFkd
@lowhankmatrix@ETzinis Matt Shannon @ArnaudDoucet1@DrJohnHershey
Introducing MilliVid, our new method for long-context video generation! MilliVid creates videos that are consistent over long time spans, without using retrieval heuristics or 3D maps! (1/n)
https://t.co/evmf5dL5Sg
🏄 SURF: Separation via Unsupervised Remixing Flows
The 1st *generative* separation model that never hears/sees any clean data!🙉🙈
Flow matching+remixing 🔀
📜 https://t.co/M5rlSHJyY9
🔊 https://t.co/DWLknSuFkd
@lowhankmatrix@ETzinis Matt Shannon @ArnaudDoucet1@DrJohnHershey