GIVE GEMINI YOUR LAST 50 SENT EMAILS. BUILD A SECOND BRAIN THAT WORKS WHILE YOU SLEEP.
Your sent folder already contains your projects, the people you deal with, the promises you made and the way you write. That is enough material to start building something useful.
The setup in my Gemini 4 course puts that context in a Drive folder called Brain, then gives the agent routines for keeping it useful while you're away.
Here's what you build:
→ A file about you and a voice doc. Ask Gemini to read 50 emails you actually wrote and extract your projects, commitments and 10 rules of your writing style, each backed by a real line of yours.
→ A filing system. Label an email Brain, and a Gmail monitor is instructed to preserve the original in raw/, update the relevant person or project doc, and add a line to INDEX and log.
→ A record of what gets your attention. At 5 PM on weekdays, a task reviews your sent mail, calendar and saved material to identify the five projects you actually worked on.
→ A morning page scheduled for 7:30 AM. New facts with links, guesses clearly marked, work filed or drafted, decisions waiting for your yes, and open questions. Ranked against those five projects.
→ Three reusable skills: note-to-plan, thread-to-reply and idea-to-post. Each reads the relevant context and saves its output back into Brain.
→ A correction loop. Your fixes become lines in rules, which the agent is instructed to read before each task. On Sunday at 6 PM, a report brings back drifting projects and decisions you forgot.
The detail that makes this usable: stable context lives in Docs. Dates, amounts and current status get checked at the original source. Drafts stay drafts until you approve them.
You still need task access, connected apps and permission checks. Scheduled times are approximate, and a run can pause for your input. Test one labelled email before trusting the overnight routine.
The full 7-step course is in the quoted article, including the combined setup prompt in chapter 07.
Tonight, give it the context. Tomorrow morning, check what it actually did.
ONE OPUS PLAN. A SWARM OF WORKERS.
A REBUILD YOU CAN ACTUALLY CHECK
The interesting part of the REA article below is what happens after the agent can inspect a binary.
How do you turn all those findings into something useful without burying the main model in worker transcripts?
Claude Code supports a useful pattern: let the model write a workflow script. The script coordinates the workers and holds intermediate results. The main session receives the final report.
For a small REA reconstruction, here’s the split I’d test:
→ OPUS: define the target, write the workflow, review the result.
→ HAIKU: run read-only reconnaissance and return an evidence map.
→ SONNET: turn the selected evidence into a behavior spec, then implement one function in an isolated worktree.
→ A SEPARATE VERIFIER: test the implementation against the reference and report every mismatch.
Start the session with:
claude --model opus --effort ultracode
That enables workflow-oriented execution. It does NOT automatically assign different models to the stages — ask for that explicitly.
The handoffs are the whole system:
evidence → behavior spec → implementation → parity tests
Every finding needs an address or an observation behind it. Every rebuilt function needs a test. Anything uncertain stays marked uncertain.
The payoff: you can follow a result back to the evidence that produced it.
Copy this into your session:
“Design an REA-assisted workflow for one function in software I own or am authorized to analyze. Use Opus for planning and final review, Haiku for read-only reconnaissance, and Sonnet for the behavior spec and isolated implementation. Assign an independent verifier. Keep intermediate outputs in workflow state and return an evidence-linked summary. Never execute an unknown binary without approval. Stop after two fix rounds with no progress. Show the plan, model assignments and proposed diffs first; wait for approval before edits.”
Start with ONE function. Inspect it, describe it, rebuild it, test it.
This can reduce what lands in the main model’s context. It can also use more total tokens. Measure a small run before scaling it up.
REA is the most dangerous repo on GitHub right now
It gives your AI agent a real disassembler, so it reads any app down to the binary
Every claim comes back with the address behind it
I broke down the exact 8 steps: https://t.co/eaeZ4OFJrH
YOUR AI AGENT CAN TURN AN EQUATION INTO A LAB YOU CAN BREAK
The REA article below walks through inspecting software, recovering its behavior and rebuilding it. The next useful deliverable is a browser lab where you can test whether the rebuilt method actually behaves correctly.
I built a small diffusion lab to make that step visible. One initial field goes through two numerical methods, with an analytical reference beside them. You can change diffusivity, time step and elapsed time. The code computes the error, mean and minimum value for each result.
Increase the time step and Forward Euler starts amplifying high-frequency modes. Its error grows and the field produces negative values. Backward Euler stays bounded in the same experiment. Reduce the step again and the comparison returns to a small error.
Here is the catch that makes the experiment useful: the broken method still keeps the mean near 1.0. One green metric can sit next to a completely wrong result.
For a larger project, I would split the agent work like this:
→ readers identify equations, assumptions and input conditions
→ builders implement one method at a time
→ reviewers compare against reference results and log discrepancies
→ interface agents expose the controls, code and measurements
Give your coding agent this assignment:
“Turn this documented method into an interactive browser lab. State the equations and assumptions. Build one reproducible reference case. Put the candidate and reference on identical inputs. Expose the parameters and compute the error. Keep failures visible, link the implementation, and provide checks I can rerun.”
The clip is a computed teaching example from stated equations. It does not claim to reproduce a research paper or show a REA investigation of an external app.
Start with one method and one reference case. Change a condition, find the failure, and make the fix measurable.
REA is the most dangerous repo on GitHub right now
It gives your AI agent a real disassembler, so it reads any app down to the binary
Every claim comes back with the address behind it
I broke down the exact 8 steps: https://t.co/eaeZ4OFJrH
CLOSED-SOURCE SOFTWARE JUST GOT A NEW INVESTIGATOR: YOUR AI AGENT
10 open-source GitHub repos worth putting in its reverse-engineering toolbox.
The useful part is knowing which tool answers which question. Save this map:
01. REA — the agent entry point.
An MCP toolkit for investigating binaries, JavaScript/Electron apps, .NET assemblies, websites and other supported targets.
https://t.co/D2rn5KMRC2
02. Ghidra — what does this binary do?
Disassembly, decompilation and program analysis for native software.
https://t.co/bC60ZMm94f
03. GhidraMCP — how does the agent reach Ghidra?
An MCP bridge for querying and working with a Ghidra analysis.
https://t.co/l8q0E7CAoc
04. ImHex — what is inside this file?
A hex editor with a pattern language for understanding binary structures.
https://t.co/onIdcKqFLy
05. ILSpy — what is inside this .NET assembly?
Decompile .NET code into readable C# and inspect its metadata.
https://t.co/abamV7HexO
06. mitmproxy — what is the app sending?
Inspect and script HTTP(S) traffic in an environment you control.
https://t.co/vV4JKDoosD
07. Frida — what happens while the app runs?
Dynamic instrumentation for observing functions and runtime behavior.
https://t.co/lb5UuT5NLR
08. JADX — what is inside this Android APK?
Inspect Android resources and decompile DEX bytecode into Java-like code.
https://t.co/hMiNPgBpEV
09. Cpp2IL — what can be recovered from Unity IL2CPP?
A work-in-progress analysis tool; recovery depends on the target and version.
https://t.co/I0zrzqO7Ig
10. radare2 — how do I automate low-level analysis?
A scriptable command-line framework for inspecting and disassembling binaries.
https://t.co/TYAI3BP6B6
These tools cover different layers. Some expose MCP directly; others need a CLI workflow or a bridge. You pick the tools for the target, rather than install everything and hope.
Give your agent one concrete task:
“Inspect this app or artifact I’m authorized to examine. Identify its format, choose the relevant tools, explain one feature with evidence, and propose an independent implementation. Separate observations from guesses. Show me the plan and any configuration changes before applying them.”
That is a much better starting point than asking it to clone an entire app.
@codewhatyouwant 100%. speed is the easiest thing to demo and the last thing that matters.most strategies that look great in a backtest die on fees and slippage. that’s the part I’d want an agent to study first, not the charts.what slippage do you usually assume on crypto?
TRADING SOFTWARE HAS A NEW PROBLEM.
YOUR AI AGENT CAN STUDY HOW IT WORKS.
REA is an open-source MCP tool that gives coding agents a way to investigate software—even when you don't have its source code.
For traders, the interesting possibility is a terminal built around the features you actually use: charts, indicators, watchlists, alerts and a strategy engine you can keep changing.
TradingView is an obvious reference. Here is the workflow I'd use to build an independent research terminal:
1. Pick one observable feature: an indicator, chart interaction or watchlist.
2. Record its inputs, outputs and edge cases. Use REA to inspect permitted artifacts and behavior where available.
3. Ask the agent to turn the findings into a specification, with evidence for every assumption.
4. Implement your own version: candle rendering, indicator math and persistent settings.
5. Add strategy testing that accounts for fees, slippage and drawdowns.
6. Compare against known examples, fix discrepancies and expand one verified feature at a time.
That turns “build me a trading app” into something an agent can investigate, implement and check.
I built a small browser prototype to make the idea tangible. The clip shows a feature map, an implementation sketch and an editable chart terminal. It uses synthetic market data and illustrates the workflow; it is not a recorded REA investigation of TradingView.
The catch: studying visible behavior does not give you a company's private source code, paid indicators or licensed data feeds. The hard work is still getting the math, data and execution assumptions right.
The competitive pressure is obvious: a useful feature can become a specification for a tool you control.
Start with one feature you understand well enough to verify. Then build outward.
Jev is the FASTEST AI model ever built for trading
It makes calibrated buy/sell decisions in under 100 ms
That is one real decision on every single block, 24/7
In this article I've shown EXACTLY how to build HFT trading system with Jev (from scratch) https://t.co/4hmZDzN00Z
@federicodonaton exactly. an agent can guess how an indicator works in 5 minutes. proving it matches the original is where the real time goes.
which would you trust less in a clone, the indicator math or the fill logic?
and yes, DMs open 🤝
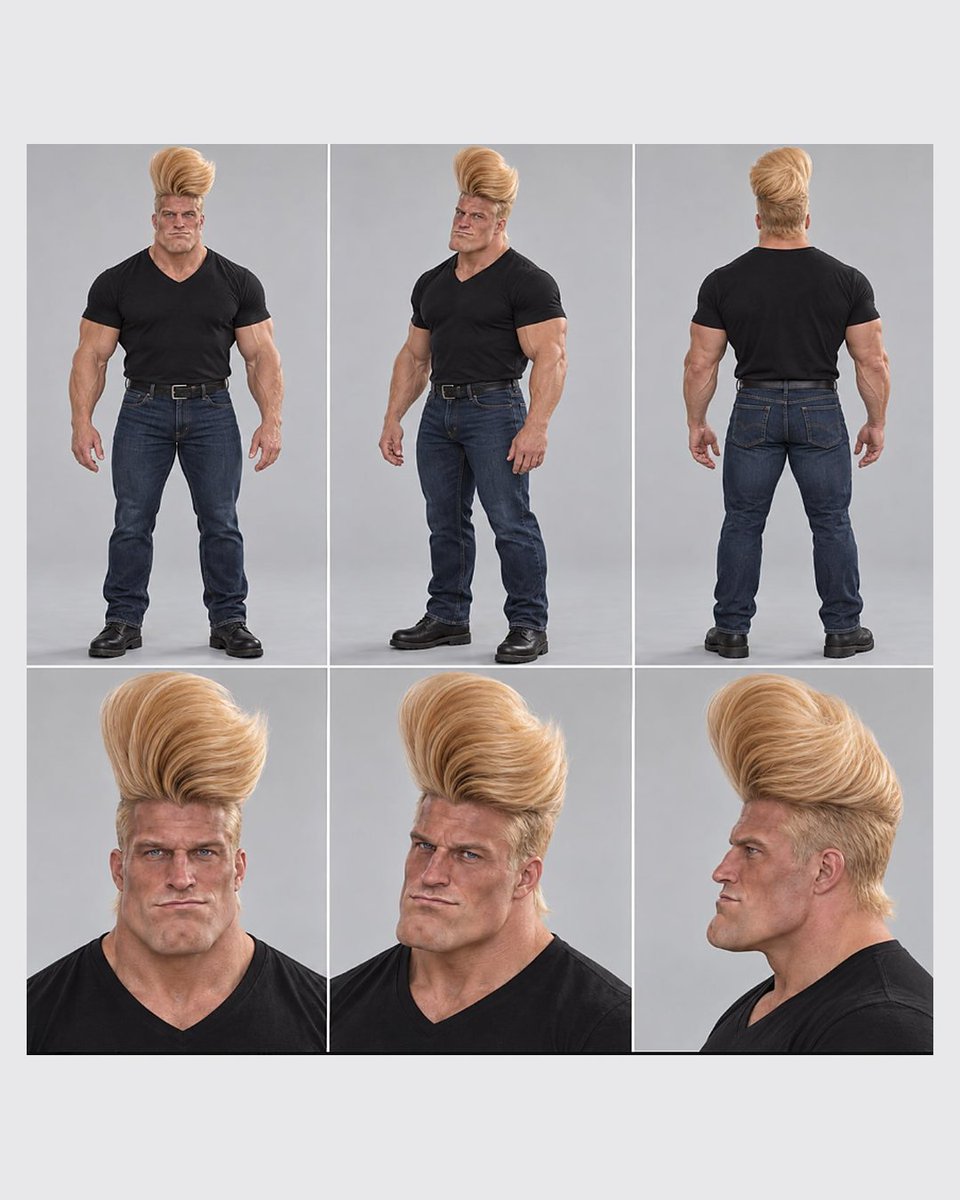
TIKTOK IS LOSING ITS MIND OVER A MAN WHO DOESN'T EXIST
4.2M likes. 19M views on one video. A business email in his bio.
The format: → one absurd AI character → same face and outfit every time → dropped into boring everyday places → the caption is the joke
A haircut became an audience.
Last post on the $0.84 agent. This one is the fix.
Ask it one more question: does this need a decision, or just a read?
Reads go into one daily digest. Decisions stay live.
8.3 hours a day becomes 3.0.
(If 70% of your human lane is read-only. Measure your own.)
The AI got to the top first.
Then it handed him 500 boxes.
That's not a joke. That's the most shared agent build on X this week.
$0.84 a day to sort 20,000 things.
500 of them go to a lane called "human."
That's you. One minute each. 8.3 hours a day.
The agent took the road. You still got the desk.
Price the human lane before you build. At $30 an hour it's about 90% of the real bill.
One of these two gets a raise next year.
It's not the one working harder.
The top guy is doing everything right.
Shows up. Grabs every box. Never stops.
And he still ends the day buried.
The bottom guy didn't work harder. He stopped being the part that has to move.
Your boss doesn't pay for effort. He pays for what's in the crate.
Watch the top guy one more time. That's your Monday.
Same desk. Same pile.
One of them is still stamping.
I ran the numbers on this.
An agent reads 20,000 events for $0.84.
By hand, at 1 minute each, that's 333 hours.
But it still sends 500 a day back to a person.
That's 8.3 hours of stamping nobody priced.
The software didn't remove your job. It moved it to the end of the pile.