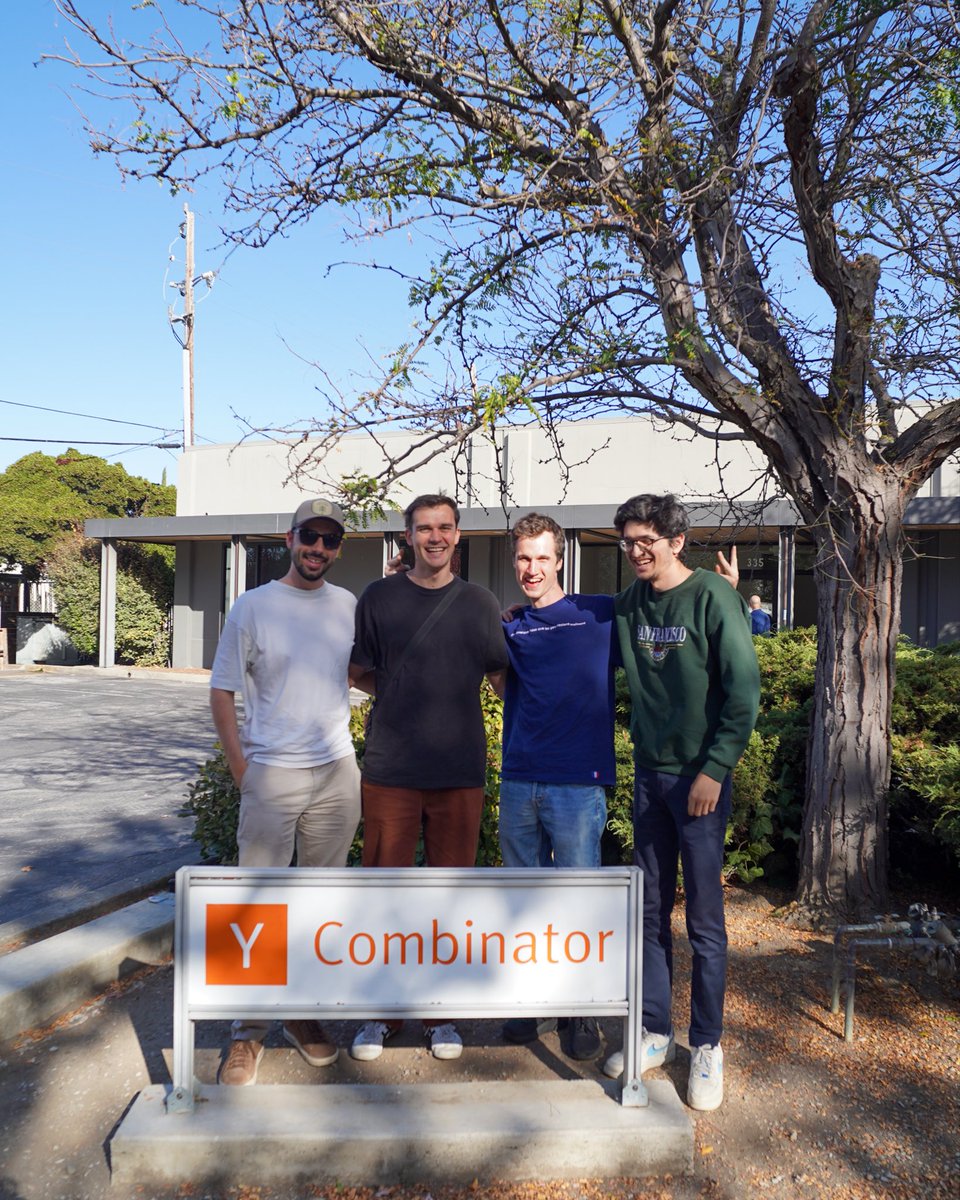
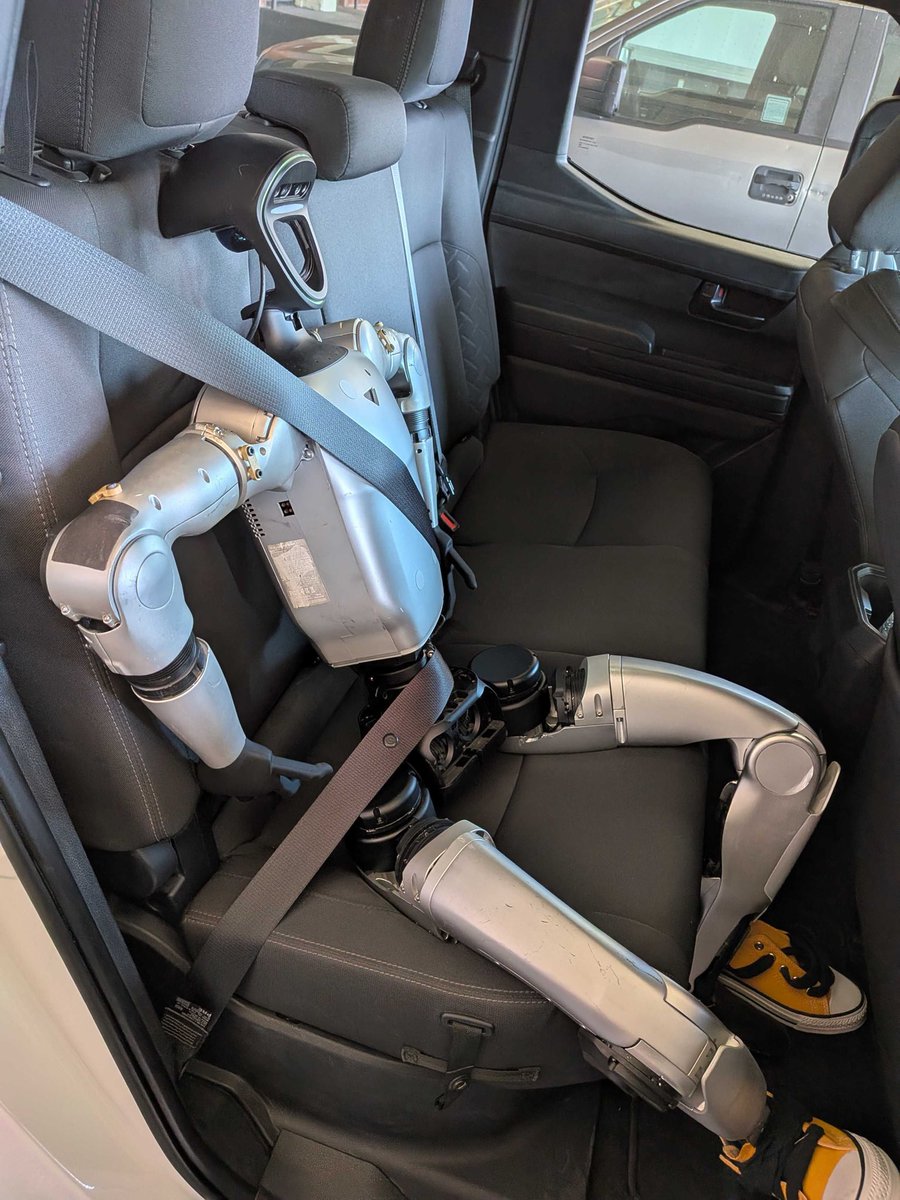
Introducing Theseus Robotics (YC F26).
Our robots restocks supermarket shelves overnight and picks online orders by day, without changing anything in the store.
Lights off at 9pm, shelves full by 9am. Next stop: San Francisco.
We’re launching Asim (YC F26) to help robotics teams find failures before deployment.
A robot completes a task perfectly. Can it handle an unfamiliar object, reason about how parts fit together, or recover when an interaction goes wrong?
We’re building standardized benchmarks for physical intelligence. We test real robots through repeatable scenarios that probe the capabilities behind successful actions: spatial reasoning, understanding physical interactions, dexterous manipulation and adaptation.
Teams can identify where performance breaks down, get actionable engineering feedback and measure whether the next software update actually improves it.
Building robots? Let’s put them to the test → https://t.co/yVIWlWoYln
Asim. Benchmarking physical intelligence.
We’re launching Asim (YC F26) to help robotics teams find failures before deployment.
A robot completes a task perfectly. Can it handle an unfamiliar object, reason about how parts fit together, or recover when an interaction goes wrong?
We’re building standardized benchmarks for physical intelligence. We test real robots through repeatable scenarios that probe the capabilities behind successful actions: spatial reasoning, understanding physical interactions, dexterous manipulation and adaptation.
Teams can identify where performance breaks down, get actionable engineering feedback and measure whether the next software update actually improves it.
Building robots? Let’s put them to the test → https://t.co/yVIWlWoYln
Asim. Benchmarking physical intelligence.
That's a good question, it's not possible to evaluate all the 19k classes because we don't have groundtruth labels for all but also because there is a lot of synonyms classes. So what I did for Open-Vocabulary evaluation was clustering the relations and counting positives by cluster. For instance "next to" predicted will be counted true for "close by" because it has the same meaning.
Thanks for the 1k stars on github!!!
My solo project RelateAnything has now crossed 1k stars, only 3 weeks after launch :)
RelateAnything is the first Real-Time Open-Vocabulary Relation Prediction model that can run on your laptop. It was trained on more than 19k relation classes and achieve state-of-the-art performance with only 53M parameters! RelateAnything takes any input (boxes, masks etc) and can predict any relation between them (like "person riding horse", "painting hanging from wall" etc) without need for retraining.
To celebrate the launch I am releasing 4 new ConvNext weights that push the Pareto frontier even further, as well as a full training recipe code for you to train your own RelateAnything!
If you are interested please give it a try:
Demo: https://t.co/1MSd50MqJn
Paper: https://t.co/zmiPKWIWuc
Code: https://t.co/vqQc4YVQ94
Models and data: https://t.co/j31o98ZUZd
@Alacritic_Super Just finding the post now, thanks a lot for sharing my project 🙏 Did it all by myself on my free time, every share is very appreciated!!
We’re in YC Fall 2026! 🇺🇸
Two months ago: a hackathon in Paris.
Today: co-founders heading to SF
We’re building @asim_group to put safety and alignment at the core of robotics.
Safe Robots. Fewer people harmed!