🚨NEW EXPERIMENT 🚨
Playground is an experimental gaming platform that lets you create your own games with zero coding experience. If you can think it, you can play it.
Go to https://t.co/fRUukpuoqM to learn more! Available to users 18+ in the US.
¿Ya probaste Google Pics? 🎨
Nuestra herramienta de creación y edición de imágenes con IA está integrada directamente en Google Workspace.
Impulsada por nuestro modelo Nano Banana, te permite aislar objetos, editar y traducir texto dentro de una imagen y colaborar en equipo en tiempo real sin salir de tus archivos.
Disponible en Documentos y Presentaciones de Google para suscriptores de Google AI Pro, Ultra y la mayoría de cuentas de Workspace Business.
Pruébala en https://t.co/aQpn9biRsi
Introducing our most advanced Gemini Audio models yet 🗣
Gemini 3.8 Live and 3.8 Live Extended Thinking let you speak, collaborate, and execute tasks seamlessly, meaning conversing with AI just got a lot more natural.
So, what’s the difference between these two models? Let’s break it down:
— Gemini 3.8 Live is built for scale, speed, and cost efficiency. It can handle mid-sentence interruptions, transitions across 97 languages on the fly, and understands visual context. Figure out how to fix a broken bike chain, or deal with a leaky pipe just by pointing your camera at the problem area in Search Live for step-by-step audio instructions.
— Gemini 3.8 Live Extended Thinking goes one step further to bring increased intelligence to your most complex tasks. It reasons and speaks in parallel, even narrating its progress as it works. This lets it handle multi-step, behind-the-scenes projects, like planning an event, without ever losing the conversational flow.
Watch how Gemini 3.8 Live combines real-time video and voice inputs in Search Live to tackle hands-on DIY plumbing tasks step by step 👇
A first look at our upcoming AI-integrated hybrid animated short film, "Passport Rush."
This is a back-to-back comparison of the Blender previs camera moves and storyboarding against the final result.
We learned a lot making this one, and we gathered some of the key learning points into simple 6 step thread:
Bookmark and check it out here 👇
This is 100% GPT-6 Astra paired with Seedance 2.5 on Higgsfield. Every second of the video is AI-generated. Even Adil is AI-generated here.
99% of Earth's population has no idea how far into the future GPT-6 Astra has taken us.
Bravo 👏
💼 Soluciones a tu alcance:
👉 #ConfigApps: Orden técnico puntual desde $40 USD por app.
👉 Pack Emprendedores: Estructuración de TikTok, Meta, Google y Landing Page por $100 USD.
📩 Audita tu proyecto vía DM o en https://t.co/SiFJrdPWxr
#manager4pps#AcordeATusMetas
⚠️ Configurar tu TikTok Business Center evita bloqueos y garantiza el control de tus activos, píxel y audiencias. 🛠️ Blinda tu infraestructura comercial con asignación de roles, verificación y orden técnico para escalar tu pauta de forma segura.
#ConfiguraBienEmpiezaBien
🚨ESTO ES UNA LOCURA
Un desarrollador chino acaba de lanzar una herramienta GRATUITA capaz de crear vídeos automáticamente para TikTok, Reels y YouTube Shorts.
Se llama MoneyPrinterTurbo.
Ya ha superado las 100.000 estrellas en GitHub.
Y ya hay gente ganando +4.000$/mes con canales faceless a partir de este sistema.
Así funciona:
1. Introduces un tema o una palabra clave
2. La IA genera el guion, la narración y los subtítulos
3. Busca el material visual, edita el vídeo y te entrega el resultado final
Todo ocurre en un único flujo de trabajo.
Guárdate esta herramienta.
Estoy seguro de que puedes sacarle muchísimo partido.
Enlace abajo👇
Google lanzó la herramienta que todo desarrollador pedía desde hace años.
Se llama CodeWiki.
Pegas cualquier repositorio y la IA lo convierte automáticamente en una documentación interactiva.
No solo resume el código:
• Genera diagramas automáticamente
• Explica cómo funciona cada parte
• Crea tutoriales paso a paso
• Detecta arquitectura y dependencias
• Y hasta monta un chatbot que entiende tu código completo
Básicamente:
convierte proyectos imposibles de entender en algo que cualquier desarrollador puede navegar en minutos.
Enlace abajo👇
👋 ADIÓS CAPCUT
👋 ADIÓS MARCAS DE AGUA
Han creado un Capcut GRATIS.
Y tiene +87K estrellas en Github.
Se llama OpenCut y contiene:
→ Editor con línea de tiempo y multipista.
→ Sistema de plugins para ampliar funciones.
→ Una sola app para web, escritorio y móvil.
→ Núcleo construido en Rust.
→ MCP Server para automatizaciones.
→ Soporte para agentes de IA.
→ Licencia MIT: puedes usarlo y modificarlo.
Y lo mejor:
* Sin marcas de agua.
* Sin suscripciones.
* Sin funciones bloqueadas.
* Open source.
Te dejo el enlace abajo y cómo probarlo:👇
basically, you can generate this level quality of Ai-video locally on RTX 3090
MiniMax H3 runs on your own hardware for text-to-video, image-to-video, and reference-to-video with native stereo audio.
I will teach you how to run Qwen 3.8 27B Dense at its optimal configuration.
If you have an RTX 3090, 4090, or 5090, you can now have frontier-level AI on your desk.
The model is free, open source, Apache 2.0. But the defaults are not the optimum. The community spent the first 24 hours digging the real config out of it, and a handful of flags now separate "it runs" from "it runs right." Here is each one and why it exists.
The one that matters most.
--spec-type draft-mtp
Qwen trained a draft head directly into the weights. A small attached brain guesses the next couple of tokens, the big model checks all guesses in one pass, every accepted guess is a free token. The head already ships inside the GGUF you downloaded. You do not download a drafter, you do not build anything. Someone found unused tensors in the server logs at 2am, tried to build the draft file, and discovered there was nothing to build. One flag connects what is already there (sudoingX found this, paired A/B, open sourced the probe before sunrise).
The depth cap. The head has exactly one layer. n=4 breaks it.
--spec-draft-n-max 2
n=2 is the sweet spot. n=3 is the ceiling. The model has one MTP layer, so pushing the draft depth to 4 or 5 crashes the head and it starts emitting junk tokens. People hit this on the Spark and documented the whole ladder: n=1 gives 1.75x, n=2 gives 2.37x, n=3 gives 2.85x, n=4 does not exist. Respect the cap.
The memory flags. MTP brings its own luggage.
--cache-type-k q8_0 --cache-type-v q8_0
--spec-draft-type-k q8_0 --spec-draft-type-v q8_0
-np 1
Three flags, one purpose: fit it on 24GB.
The KV cache is the model's running memory of your conversation, and it is the thing that eats your card at long context. q8_0 halves it with no visible quality cost.
The second line does the same for the draft head's own cache, which defaults to full fat and quietly eats 2GB.
And parallel slots set to 1 means requests queue instead of reserving a second pool. Single card, single lane, everything fits (AJ runs this exact trio on a 3090).
The quality flag. Past 100K the model gets dumb, this is the fix.
--kv-cache-dtype bfloat16
The quantized cache saves memory but degrades reasoning at long context. One person ran it all day past half the window and called the full precision fix night and day. Slight tok/s cost, real quality gain. If your sessions stay short, skip it. If you live past 100K, do not.
The trap that generates "this quant is broken" reports.
--jinja
Qwen 3.8 ships its own chat template. Load the model without this flag and there is no reliable marker for where your turn ends and its answer begins. Two failure modes: it rambles past the stop token, or it answers clipped and loses the thread between turns. Both look like a broken quant. It is not the quant. Several packs now ship a corrected template file because the official one nests empty think blocks across turns.
The Blackwell lane, if you own a 50-series or a Spark.
NVFP4 instead of GGUF. The MTP flag translates to --speculative-config '{"method":"mtp","num_speculative_tokens":3}', same cap. FP8 KV cache doubles your context window (a full 1M token session costs about 32GB of cache).
Two gotchas documented in the first 24 hours: stock vLLM cannot load this model's MTP architecture on a Spark, you need the community GB10 build. And FP8 KV requires a specific attention backend on the Spark, the default one silently cannot serve it.
Set reasoning to medium unless you want it thinking at maximum depth on every reply. Default is xhigh and it burns your tokens.
None of these came from the model card. Every one came from someone's server log, 2am session, or paired benchmark. Flip the flags, then come tell the community table what your card did.
Drop in parameter flags and sources for your technical DD in reply 👇
🚨LOS CHINOS LO HAN VUELTO A HACER!!
ALIBABA acaba de liberar la pieza que le faltaba a todo el
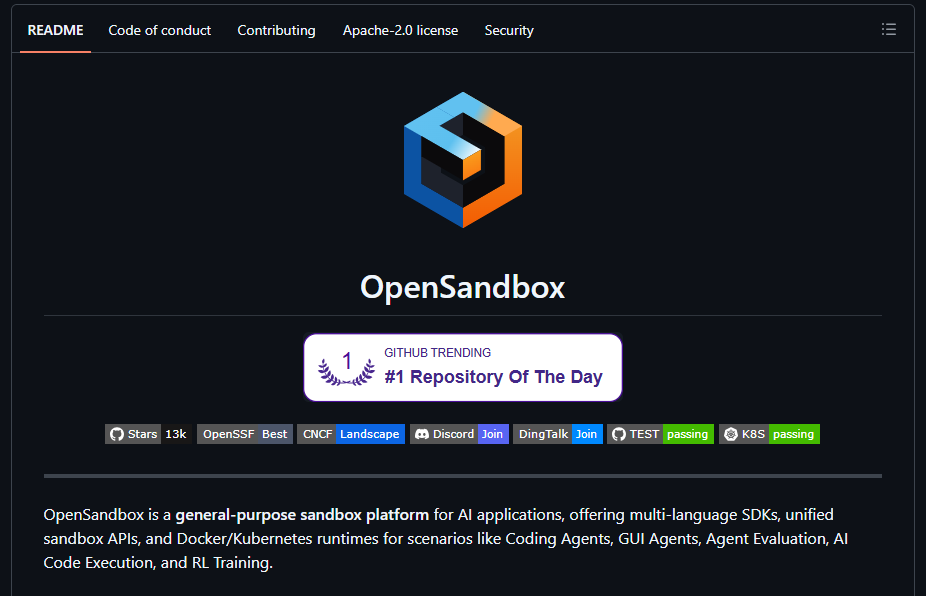
Se llama OpenSandbox.
Entornos aislados de VERDAD para que tus agentes hagan lo que quieran.
Qué puede correr dentro:
→ Claude Code, Codex CLI, Gemini CLI, Qwen Code y Kimi CLI
→ Chrome y Playwright para automatizar navegación
→ Escritorios completos por VNC
→ VS Code en el navegador
→ Intérprete de código multi-lenguaje
Además:
→ SDKs en 6 lenguajes: Python, Java/Kotlin, TypeScript, C#, Go
→ Runtime en Docker para local y Kubernetes para escalar
→ Credential Vault: el agente usa tus credenciales sin llegar a verlas
→ Control de red por sandbox, entrada y salida
→ Servidor MCP listo para Claude Code y Cursor
→ CLI propio (osb)
Y está pensado también para evaluación de agentes y entrenamiento con RL: un sandbox por intento.
Esto no es un juguete!
Repo en el primer comentario 👇
🔴 BOMBAZO: Unos chinos acaban de humillar toda la industria de video con IA de PAGO
Subes una foto
Subes un audio
Y te genera un video de una persona hablando en sincro que aguanta minutos
Se llama LongCat-Avatar
Es open source y encima GRATIS
Lo que antes necesitabas camara, estudio y edicion ahora sale de un repo
Te dejo el repo en los comentarios
BBC literally built the greatest sound library on the internet.
It is called BBC Sound Effects, and it gives you access to more than 30,000 recordings from around the world.
Just search any word, and it instantly finds matching sounds.
You can filter them by category, duration, and even the continent where the sound was recorded.
Every sound can be previewed inside your browser, downloaded, or added to the built-in mixer so you can layer multiple recordings together.
And the archive gets insanely specific.
You can find creaking ships, old typewriters, jungle ambience, distant church congregations, and even someone vigorously washing their hands.
There is a good chance a BBC engineer recorded the exact sound you need decades before you were born.
https://t.co/vdOBewxyg3