1/ Gemini 2.5 is here, and it’s our most intelligent AI model ever.
Our first 2.5 model, Gemini 2.5 Pro Experimental is a state-of-the-art thinking model, leading in a wide range of benchmarks – with impressive improvements in enhanced reasoning and coding and now #1 on @lmarena_ai by a significant margin. With a model this intelligent, we wanted to get it to people as quickly as possible.
Find it on Google AI Studio and in the @geminiapp for Gemini Advanced users now – and in Vertex in the coming weeks. This is the start of a new era of thinking models – and we can’t wait to see where things go from here.
Quick take on the markets:
1. Economy is slowing down, and this slow down is no longer a one quarter phenomena, the NSO has estimated Fy2025 GDP growth at 6.4% .
2. We expect this number to come down further for FY2025
3. RBI has stayed tight for too long . Now with Rupee depreciating, and US yields staying high, the room for RBI to cut has shrunk.
4. The government spending this fiscal has not been as strong as budgeted, and we will have unspent funds as of March 31st
5. Demand is not growing fast enough .
6. The need of the hour is a combination of counter cyclical fiscal spending and rate cuts on the monetary policy front.
7. Both have been lacking due to various reasons.
8. The good news is the Domestic flows into the markets, otherwise we would have seen much sharper cuts.
9. Primary markets are also holding up, showing that appetite for Indian companies remains high.
10. However, promoters and PE funds selling out has also reached very high levels.
11. FPIs are selling regularly, it is still a small portion of their total investments , but concentrated sales in Financials , Oil and Gas et al has had an impact on the markets.
12. What to do now:
a. Avoid lump sum investments
b. We dont know where the bottom will be reached on indices when sentiment goes low.
c. Markets may fall sharply and stay low for years as we saw in the 1990s or in 2008-2013, though we dont foresee such an eventuality for now.
d. The Market Cap to GDP ratio is still very high and if growth does not pick up , it will stay high.
e. Its back to Basics....revisit your financial goals, time horizon and risk appetite.
f. Based on these redo your Asset Allocation and rebalance your portfolio.
13. Not much leeway with the government to give meaningful relief to the middle classes in the Union Budget 2025.
14. Leading indicators are not showing strength for the economy
15. The Macro, Top Down approach will not work for this year and the next. Active fund managers will outperform passive index funds.
16. But we cant forecast accurately which funds/ stocks will outperform
17. Earnings season will see huge volatility , with any poor performance seeing big downsides in prices and any good result being rewarded very strongly as well.
18. Best to wait out this period. We dont see more than another 5% downside but we cant be sure .
19. Trump 2.0 remains another global pressure point.
More on that nearer to Inauguration on Jan 20th.
20. What sectors looking better: street is divided on these, my personal preference is India focussed pharma, midcap IT , large PSU banks , telecom leaders, industrials and power .
21. Key support levels have been taken out , hence the markets can fall sharply now. However, 4 days of Rs 2000 crore per day inflows by FPIs will lead to a huge rally. Both shorts and longs will hit stop losses in such markets.
22. Hence best is to focus on long term investing for your financial goals and not to worry too much about the macro or noise around us .
Best wishes.
पैशांना पाय नक्की कसे फुटतात? किंवा
पैसे नक्की जातात तरी कुठे? याची उत्तरं अनेक जणं शोधत असतात.
कधी स्वअनुभवाने, कधी पुस्तकं वाचून, एखाद्याला भेटून, तर कधी असा डिजीटल कंटेंट पाहून ते कळते.
गरज आणि लक्झरी यातला फरक यात चांगल्या पद्धतीने दाखवलाय.
https://t.co/6Sbw9oIMiS
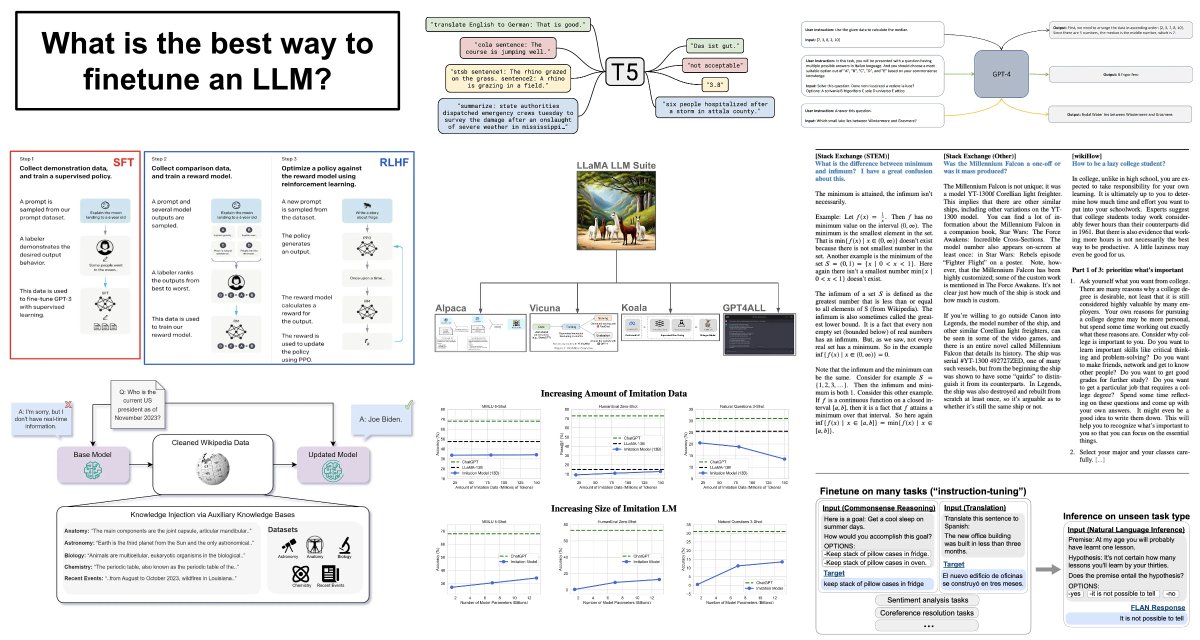
There are a ton of different ways to finetune a language model. Here's a (brief) summary of language model finetuning, the various approaches that exist, their purpose, and what we know about how they work...
Finetuning techniques: The term “finetuning” simply refers to further training a pretrained model. In the case of LLMs, this means that we take a pretrained foundation model and train it some more. But, there are so many different ways that this training can be done, which makes the concept of finetuning incredibly vague. This single term can refer to a variety of different techniques, such as:
- Continued pretraining
- Instruction tuning
- Supervised finetuning (SFT)
- Reinforcement Learning from Human Feedback (RLHF) or Direct Preference Optimization (DPO)
What is the goal of these techniques? For language models, there are two primary goals that a practitioner will have when performing finetuning:
1. Knowledge injection: teach the model how to leverage new sources of knowledge (not present during pretraining) when solving problems.
2. Alignment (or style/format specification): modify the way in which the language model surfaces its existing knowledge base; e.g., abide by a certain answer format, use a new style/tone of voice, avoid outputting incorrect information, and more.
Given this information, we might wonder: Which finetuning techniques should we use to accomplish either (or both) of these goals? To answer this question, we need to take a much deeper look at recent research on the topic of finetuning.
Large-scale instruction tuning: Prior to the release of modern open-source LLMs, it was very common to finetune pretrained LLMs on massive instruction tuning datasets. Such an approach was popularized by models like FLAN [1] (from Google), which perform instruction tuning of pretrained language models over large datasets. In the case of FLAN, for example, the FLANv2 instruction tuning dataset contains over 15M examples—very large! By following this approach, FLAN can learn to solve a large number of different downstream tasks in an efficient manner.
“We show that by training a model on these instructions it not only becomes good at solving the kinds of instructions it has seen during training but becomes good at following instructions in general.” - from FLAN paper [1]
Beyond knowledge injection: After the proposal of ChatGPT, we saw an increase in the desire to align language models and adapt their output format to a particular style or structure. Such a goal is drastically different than teaching an LLM to solve a new task. When we are trying to teach an LLM new knowledge, more data is always better (hence the large instruction tuning datasets used by models like FLAN). However, aligning the language model to a certain style or structure of output does not require learning new information! So, maybe alignment-focused goals require less extensive finetuning.
Less is more for alignment: Research on the topic of LLM finetuning was catalyzed by the release of LLaMA [2] (and later LLaMA-2 [3]), which made high-quality foundation LLMs openly available. Quickly after LLaMA, authors from Meta published LIMA [4], which showed that alignment-style finetuning can be accomplished with very little data. Namely, the goal of alignment is to adapt the LLM’s style (rather than to learn new information), which can be accomplished via a small, high-quality, and diverse finetuning dataset. Such findings revealed that most of an LLM’s knowledge comes from pretraining, and the LLM learns the correct style during alignment (see quote below).
“A model’s knowledge and capabilities are learnt almost entirely during pretraining, while alignment teaches it which subdistribution of formats should be used when interacting with users.” - from LIMA paper [4]
Imitating proprietary LLMs: Following LIMA, a massive number of high-quality, finetuned LLMs (e.g., Alpaca, Vicuna, Koala, Orca, and more) were created by finetuning LLaMA over small synthetic finetuning datasets of GPT-3.5/4 outputs. In this way, we could train these models to imitate the output of more powerful LLMs. When evaluated in human trials and on simplistic benchmarks, these models seemed to match (or exceed) the performance of powerful models like ChatGPT. For this reason, practitioners began to believe that we could surpass models like GPT-4 or ChatGPT by performing a small amount of (inexpensive) finetuning.
What is going on here? Obviously, training a model like ChatGPT cannot be done this easily. Researchers quickly found some limitations in the work done on imitation models [5]:
- Humans are easily tricked if the style of the LLM is good, and (as shown by LIMA) these models can quickly learn to mimic the style of models like ChatGPT with little data.
- The benchmarks that were used are too limited. The models perform well when evaluated by a small group of humans, but their performance falls apart on more extensive benchmarks that include traditional, perplexity-based evaluations (e.g., normal NLP benchmarks).
We can learn certain things (e.g., style and output format) from finetuning over a small amount of data, but we can’t learn everything! These imitation models lack the knowledge base of more powerful LLMs, which can only be learned from large amounts of data.
Putting everything together: Given all of the information we’ve covered so far, there are a few takeaways that we can deduce:
- Most knowledge from an LLM comes from pretraining.
- We can perform finetuning in the form of continued pretraining to expose the LLM to more (and new) data/knowledge.
- Alignment-focused objectives can be achieved via finetuning (SFT) on small, high-quality datasets. We don’t need to tons of data to learn style or format of output, only to learn new knowledge.
When performing finetuning, it’s very important that we know which goal—either alignment or knowledge injection—that we are aiming for. Then, we should put benchmarks in place that allow us to accurately and comprehensively assess whether that goal was accomplished or not. Imitation models failed to do this, which led to a bunch of misleading claims/results!
Ongoing work: The story doesn’t stop here! In fact, the distinction between pretraining and finetuning is still quite vague. At what point does the LLM start actually learning new knowledge instead of just learning style/alignment? Many recent publications are continuing to study this question:
- Finetuning vs. RAG [6]: authors find that continued pretraining is not super effective at knowledge injection, while RAG is actually highly effective at specializing an LLM to a new knowledge base.
- LIMIT [7]: authors from MosiacML/Databricks show that we can perform finetuning over a small mixture of instruction tuning and alignment-focused data, leading to a model that performs well in both NLP benchmarks and style-focused evaluations.
- TULU [8]: authors subject finetuned LLMs to broader evaluations, finding that the quality of the base model has a massive impact on performance and that no one finetuning dataset/strategy yields the best results across all benchmarks.
- TULU-2 [9]: authors show that finetuning LLMs over specific datasets leads to the model learning specific skills and domains of data. Finetuning works well if we make sure the finetuning dataset is highly relevant to the style/domain of evaluation we are using.
- AlpaGasus [10]: authors directly study how much finetuning data is necessary for an LLM to perform well on various downstream tasks.
-------- Bibliography --------
[1] Wei, Jason, et al. "Finetuned language models are zero-shot learners." arXiv preprint arXiv:2109.01652 (2021).
[2] Touvron, Hugo, et al. "Llama: Open and efficient foundation language models." arXiv preprint arXiv:2302.13971 (2023).
[3] Touvron, Hugo, et al. "Llama 2: Open foundation and fine-tuned chat models." arXiv preprint arXiv:2307.09288 (2023).
[4] Zhou, Chunting, et al. "Lima: Less is more for alignment." Advances in Neural Information Processing Systems 36 (2024).
[5] Gudibande, Arnav, et al. "The false promise of imitating proprietary llms." arXiv preprint arXiv:2305.15717 (2023).
[6] Ovadia, Oded, et al. "Fine-tuning or retrieval? comparing knowledge injection in llms." arXiv preprint arXiv:2312.05934 (2023).
[7] Jha, Aditi, et al. "LIMIT: Less Is More for Instruction Tuning Across Evaluation Paradigms." arXiv preprint arXiv:2311.13133 (2023).
[8] Wang, Yizhong, et al. "How far can camels go? exploring the state of instruction tuning on open resources." Advances in Neural Information Processing Systems 36 (2024).
[9] Ivison, Hamish, et al. "Camels in a changing climate: Enhancing lm adaptation with tulu 2." arXiv preprint arXiv:2311.10702 (2023).
[10] Chen, Lichang, et al. "Alpagasus: Training a better alpaca with fewer data." arXiv preprint arXiv:2307.08701 (2023).
तुमच्या कडे दिवसाचे 16 मिनिट आहेत ? मग आपल्या कुठल्याही आवडीच्या पक्षाचा झेंडा थोडा बाजूला ठेवून अन्नामलाईचा आयआयटी, चेन्नई मधील AI ने काय होऊ शकत, जग कसे बदलतंय, राजकारण कसे बदलेल, तरुणांनी राजकारण मध्ये का यावे याचे उत्तर नक्की ऐका + Good Sense of humour
लाभले आम्हास भाग्य बोलतो मराठी,
जाहलो खरेच धन्य ऐकतो मराठी,
धर्म, पंथ, जात एक मानतो मराठी,
एवढ्या जगात माय मानतो मराठी !
मराठी भाषा दिन निमित्त सर्वांना हार्दिक शुभेच्छा!
#मराठीभाषागौरवदिन#मराठीभाषा
Survey of LLMs
Reviews three popular families of LLMs (GPT, Llama, PaLM), their characteristics, contributions, and limitations.
Includes a summary of capabilities and techniques developed to build and augment LLM.
It also discusses popular datasets for LLM training, fine-tuning, and evaluation, and LLM evaluation metrics.
Concludes with open challenges and future research directions.
🚨🚨Traffic Flow Changes: #Pune University Road🚨🚨
Starting today (10/02), significant alterations have been implemented but @PuneCityTraffic to the traffic flow on #Pune University Road (Ganeshkhind Road) to alleviate congestion caused due to the ongoing construction work for the Metro and Multi-Level Flyover.
1. Travelling from Shivajinagar to Aundh / Hinjawadi: Vehicles must now make a right turn at ABIL House and proceed via Range Hills Road – Symphony Circle – Sai Chowk (Khadki) – Dr. Ambedkar Chowk (Bopodi) – Spicer College – Bremen Circle.
2. Travelling from Aundh / Hinjawadi to Shivajinagar / Pune Station: Vehicles will follow the route via Bremen Circle – Spicer College – Dr. Ambedkar Chowk – Sai Chowk – Symphony Circle – Range Hills Road, then make a left turn at ABIL House to continue via Pune University Road.
3. ABIL Circle: Right turns are prohibited when approaching from Range Hills.
4. Dhotre Path to Aum Super Market Circle: Now two-way.
5. Kahu Galli (Polytechnic Ground) to Aum Super Market Circle: One-way. Vehicles cannot join University Road from the Khau Galli Junction.
6. Luxury Buses: Private luxury buses are restricted from travelling between 8:00 AM to 10:30 PM to and from Sancheti Hospital towards PCMC / Hinjawadi via #Pune University Road (Ganeshkhind Road) and University Circle. They will instead use the Old Pune Mumbai Highway (via Harris Bridge) or alternatively via Katraj - Khadi Machine Chowk.
Please share this information with your friends and family to ensure a smoother transition to the new traffic flow.
#PuneTraffic #UniversityCircle #trafficupdates #Pune
@BJP4PuneCity@PMCPune@OfficialPMRDA
काही मित्र आयुष्यात आपलेच ‘प्रतिबिंब’ बनून येतात.
त्यांच्या कुटूंबातही आपल्याला आपले भाऊबहिण, आईवडील दिसतात, वर्गातला एखादा जानी दोस्त दिसतो!
त्यांचं आपल्या आयुष्यात असणं हीच सर्वोच्च कमाई असते. मग ते आपल्या जवळ असोत की लांब…✊ आशाअपेक्षा,स्वार्थ किंवा कोणत्याही आपमतलबाशिवाय!