🔗Explore KEEP-Bench and test your compressor!
📄Paper: https://t.co/MtcFQjhw6s
🌐Project: https://t.co/JtEXjeGOpP
💻Code: https://t.co/sDWfCz8thv
Many thanks to this amazing team w/ @DiWu0162@Jiachen_Gu@Levi_JYZhang@kaiwei_chang@VioletNPeng
6/n
🧵Does a correct answer imply faithful compression?
Introducing 🚀KEEP-Bench🚀: a benchmark that directly tests whether context compression preserves all the evidence needed for reasoning, exposing unfaithful compressions that traditional QA evaluation misses.
1/n
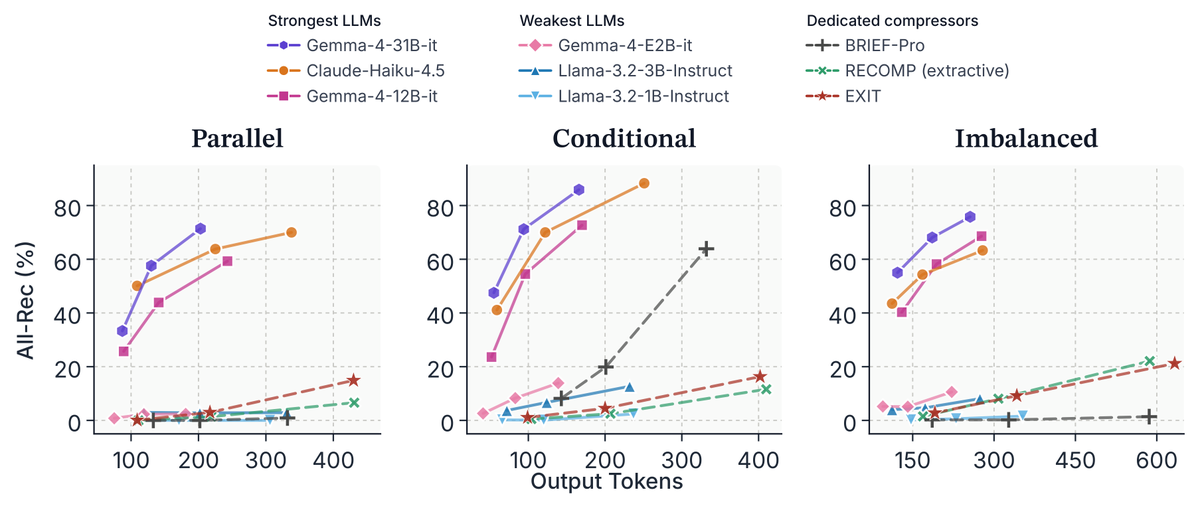
📈The extra budget mainly benefits already strong models.
From 0.5× to 2× the default budget, average All-Rec gains across settings:
• Three strongest LLMs: +32.8 points
• Three weakest: +3.9 points
More budget widens the capability gap.
5/n