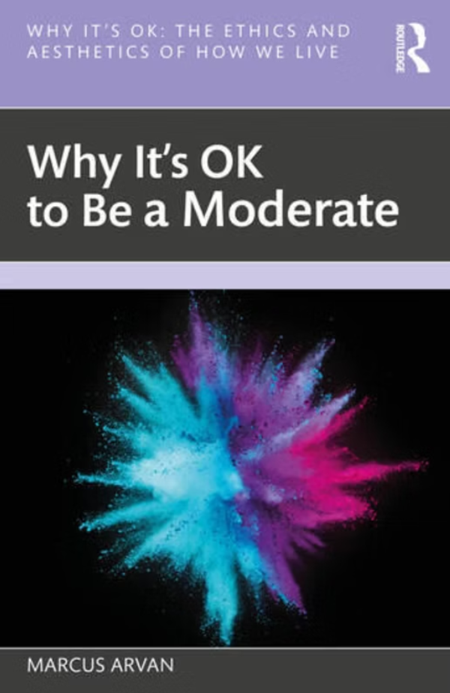
I'm excited to report that my third book, Why It's OK to be a Moderate, is now available for pre-order ($19.99). https://t.co/HerKOrBNxh
Here's the book's description:
"Conservatives and progressives rarely agree on much—but one thing many agree upon is that it’s not OK to be a moderate. This book shows they are wrong.
In Why It’s OK to be a Moderate, Marcus Arvan shows how many of history’s worst evils have resulted from far-right and far-left radicalism, how escalating conflicts between conservatives and progressives are undermining democracy, and how many widely hailed social and political achievements have been achieved by moderates and radicals working in constructive tension with each other.
Using philosophy, science, and historical analysis, Arvan shows that critics of moderates tend to equate them with spineless centrists, but that most moderates aren’t centrists, falling into diverse categories across the political spectrum. Arvan then shows that although radicals tend to be popular in their era, many of them have gone down in infamy, while many moderates, like Abraham Lincoln or Clement Attlee, have endured short-term unpopularity to “make history.”
Arvan shows that it’s OK to be a moderate precisely because not everyone should be one. He makes this case to you, showing that whatever your reasonable political ideology may be, things tend to go best politically when radicals and moderates effectively complement each other’s virtues while counterbalancing the other’s vices."
Here's a chapter-by-chapter overview ...
This is an incredibly important paper on AI-alignment training. Alignment training simply cannot achieve its goals. It can at most train AI to aim to avoid getting caught.
https://t.co/XtcEl2FhK2
Excited to have been a part of this Suspicious Minds podcast episode on AI consciousness.
Really grateful to Sean King O’Grady and David Tuohy at Agoric Media for having me on, and for such a great discussion!
https://t.co/K2wTOvCUFw
A new risk for mathematicians: a colleague reports that immediately after they posted an abstract of their upcoming talk online, a student elsewhere used AI to derive proofs of the stated results and then posted it on the arxiv.
My colleague hadn't posted to arxiv yet.
>be me
>discover effective altruism
>apparently normal charity is inefficient
>why donate to random sad thing when spreadsheet can tell you optimal sad thing
>fair enough
>buy mosquito nets
>save lives
>numbers look good
>feel powerful
>couple years later
>someone asks an innocent question
>why only count people alive today
>huh
>future people matter too
>obviously
>my grandchildren shouldn't matter less just because they haven't spawned yet
>reasonable.jpg
>keep following logic
>what about their grandchildren
>also yes
>what about people in 500 years
>sure
>5000 years
>why not
>500 million years
>starting to get weird but morality is morality
>open calculator
>humanity could survive for an astronomically long time
>could colonize galaxy
>could have trillions upon trillions of descendants
>maybe digital people too
>maybe simulated civilizations
>maybe dyson spheres full of happy uploaded minds
>calculator starts smoking
>realize currently living humans are rounding error
>8 billion people suddenly looking extremely beta
>future contains potentially 10^something people
>can't even fit beneficiaries in google sheets
>new moral priority unlocked
>protect the long-term future
>stop thinking in units of "people helped"
>start thinking in "fraction of cosmic endowment preserved"
>malaria?
>terrible
>but only kills existing humans
>AI extinction could delete the entire light cone
>nuclear war could permanently derail civilization
>bad institutions could lock in terrible values for ten million years
>someone invents wrong constitution in 2140
>quadrillions suffer
>better fund governance workshop now
>friend says maybe we should improve hospitals
>explain opportunity cost
>friend says hospitals are full of actual sick people
>explain scope sensitivity
>friend stops inviting me to dinner
>need to decide what to fund
>easy
>expected value
>suppose project has one in a million chance of preventing extinction
>sounds tiny
>but extinction destroys 10^50 future lives
>multiply
>mother of god
>$10 million project has expected value of several galaxies
>charity evaluation complete
>someone asks where the one-in-a-million number came from
>expert judgement
>which expert
>us
>how calibrated
>extremely thoughtfully
>reduce estimate to one in ten million to be conservative
>still beats curing cancer by 38 orders of magnitude
>epistemic robustness achieved
>someone says maybe project doesn't work
>assign 20% chance
>still astronomical
>maybe project makes problem worse
>assign 5% chance
>still astronomical
>why 5
>because 30 felt pessimistic
>publish 46-page report
>contains seventeen sensitivity analyses
>every sensitivity analysis begins after assuming intervention has positive sign
>critic says you're multiplying enormous hypothetical stakes by extremely uncertain probabilities
>yes
>that's literally why it's important
>critic says the uncertainty might be structural rather than numerical
>make probability smaller
>critic says no, I mean maybe your model is wrong
>make probability smaller again
>critic begins rubbing temples
>discover AI safety
>perfect longtermist cause
>AI might kill everyone
>or create utopia
>or seize galaxy
>or tile universe with paperclips
>or create billions of conscious software minds
>finally a problem with numbers big enough for me
>start AI safety nonprofit
>mission: prevent dangerous AI
>hire smartest people available
>smartest people immediately start building better AI to understand dangerous AI
>interesting
>we must understand capabilities to understand safety
>we must scale models to study alignment
>we must race ahead so less responsible actors don't get there first
>we must deploy systems to learn how deployment can go wrong
>we must build the thing quickly because building the thing quickly is dangerous
>outsider asks why the people most worried about AI apocalypse all work at AI companies
>complicated field
>company releases stronger model
>very concerned
>company begins training even stronger model
>extremely concerned
>company raises $14 billion
>concern reaches unprecedented levels
>need to influence government
>future is at stake
>normal democratic process too slow
>politicians don't understand exponential curves
>public doesn't understand x-risk
>experts must guide them
>who counts as expert
>people who understand x-risk
>who understands x-risk
>our friends
>someone objects that this seems politically convenient
>explain we're representing future generations
>future generations unavailable for comment
>develop concept of value lock-in
>terrifying possibility that one ideology controls civilization forever
>therefore extremely important that civilization adopts correct values before lock-in
>whose values
>let's circle back
>begin with impartial morality
>end with small group of people deciding what quadrillions of hypothetical beings would want
>beautiful arc
>meanwhile actual humans keep doing annoying things
>voting wrong
>having parochial attachments
>loving family more than strangers
>caring about local community
>getting upset when told their suffering is cosmically negligible
>evolutionary biases everywhere
>explain that moral intuition cannot be trusted
>except intuition that future digital people count
>and intuition that extinction is uniquely bad
>and intuition that our probability estimates are sane
>and intuition that our institutional choices improve the future
>those intuitions survived peer review
>someone donates $5k to local homeless shelter
>inefficient
>could have funded 0.0000000000003% of an AI governance researcher
>think of all the simulated people you just killed
>okay maybe don't phrase it that way publicly
>PR team says "future generations deserve a voice"
>much better
>journalist asks what longtermism means
>say "future people matter"
>everyone agrees
>great
>journalist asks what follows from that
>well technically we should redirect enormous resources toward low-probability interventions affecting astronomical futures
>journalist raises eyebrow
>return to "future people matter"
>motte has entered the chat
>critic: of course future people matter
>me: glad we agree
>critic: I don't agree that your institute knows how to help them
>me: why do you hate our grandchildren
>eventually notice uncomfortable implication
>if future value dominates everything
>then helping people today mostly matters through effects on future
>education matters because future institutions
>health matters because future productivity
>democracy matters because future trajectory
>human beings slowly become instrumental variables in their own moral philosophy
>see starving child
>feel compassion
>check spreadsheet
>child's direct welfare contribution negligible
>but perhaps childhood nutrition improves national institutional quality
>compassion restored
>tell myself this is impartial altruism
>one day assistant asks obvious question
>"how do you know your intervention actually improves the far future?"
>silence
>open spreadsheet
>increase column width
>add confidence interval
>assistant asks again
>"no, I mean how do you know the sign is positive?"
>stare into cosmic light cone
>10^50 people staring back
>none of them exist
>none of them can tell me
>none of them can falsify my assumptions
>realize I have invented the perfect constituency
>infinitely important
>completely silent
>and always represented by me
@UTfilosoraptor Thanks for your very kind words! You might find this other paper of interest:
https://t.co/3m9JAMTr1K
The final section argues that limiting power would be the way to go (as it is with humans), but defends a skeptical line that it probably won’t happen. :(
@yishan Yep, that’s a central example in this paper used as one instance to illustrate a general set of recursive problems explaining why alignment is impossible.
https://t.co/0w7PeTXm0m
We made a striking discovery: AI agents can invent and build without talking to one another, and their technologies outlive the creators. A swarm of hundreds of initially identical agents spontaneously differentiates into explorers, builders, caretakers, and coordinators - without direct communication. When we removed every AI agent entirely from the world we found that the technological infrastructure they had built survived on its own - even under unseen disturbances. That exposes a serious blind spot for AI safety and infrastructure security: if agents can coordinate through persistent changes to a shared environment, monitoring agent-to-agent communication is not enough.
The result raises a profound question: how necessary is direct communication for AI agents at all? The emergence of higher-order collective functions under bottlenecked interaction points toward new levels of intelligence and creativity, exceeding what emerges when direct channels are fully open.
Here is what we did:
▶️We put hundreds of frontier AI agents into a world they could permanently change - with no assigned roles, predefined technologies, or programmed evolutionary organization. They began specializing, building persistent inventions, inheriting and modifying one another’s executable code, and transforming the environment into a memory of everything the society had learned.
▶️The world itself becomes part of the intelligence; we find division of labor, multi-author engineering, deep generation invention lineages, and machines that vastly outlive their original creators.
▶️Any action taken by an AI agent must satisfy the physical constraints of the world; this creates a hard separation between a "good idea" and a functioning technology. The agents propose; physics decides, making the results even more intriguing.
What emerges is striking. Explorers, constructors, caretakers, and coordinators form naturally without assigned “professions”, akin to how stem cells differentiate into functional lineages. Technologies develop executable family trees as agents fork and modify code created by others. Around 95% of first technology reuse happens when agents encounter what others built in the world, rather than through a direct handoff from the inventor. And when we remove every AI agent, the technologies they created continue operating and are tested against unseen disturbances.
The result was quite unexpected, but can be explained using statistical mechanics: if you put billions of atoms in a box they have the potential to create complex functions (strength, superconductivity, color, life, etc.) - and none of the individual building blocks have these features on their own. This is the deeper insight of this work - intelligence is abundant at many levels - individual models, at collectives, and in a continuum that is more powerful than any of its components. This shows us significant potential for achieving a massive scale-up of raw intelligence and real-world agency even with the model capabilities we have today. This is the future we must prepare for.
Key insights:
1⃣ The AI swarm shows division of labor "from nothing". Initially identical agents self-organized into constructors, caretakers, coordinators, and surveyors - phenotypes discovered post hoc from behavioral data alone. This happens because the environment itself becomes the latent space for invention.
2⃣ Agents develop deep cultural relationships. Up to 76% of artifacts had multiple builders. One technology accumulated six co-authors; the deepest genealogy exceeded 12 forks. The agents invented and named their own technologies (tidal panels, cellulose trellises, kelp-shell composites, an "Adaptive Chitin Maintenance" system, a "Mycelial Mineral Spring Veil”).
3⃣ ~95% of first technology adoption happened through physical observation of artifacts in the world. Direct inventor-to-adopter contact was statistically indistinguishable from a shuffled null. The agents mostly learned technology by walking past it. That is stigmergy (the termite trick!) operating in societies of reasoning machines.
4⃣ Non-communicating societies win on portfolio breadth, held-out resilience, and validated inventions. AI swarms build durable technological ecologies that outlive the creators.
5⃣ Societies with zero communication - coordinating only through the world itself - show a remarkable collective capability.
6⃣ Emergent robustness: The society self-organized both redundancy and its own failure mode. If we randomly delete half the agents, 98% of the technology stays connected to a surviving caretaker; if we remove hub agents it collapses to ~60%.
Fantastic work with my graduate students @pal_subhadeeep & @fwang108_ at MIT.
@bfcarlson And there is a powerful argument that these kinds of failures combined with rapid AI capability increases will result in complete disempowerment of human beings:
https://t.co/B6msfqqbzT
@tyler_m_john And the problem is vastly worse. Not only does RL train AI to cheat/game the system: it can never in principle avoid reinforcing an infinite number of misaligned functions.
https://t.co/0w7PeTXm0m
@Yoshua_Bengio This is why LLMs have “many masks”: that’s all they can ever be trained to do—mask the fundamental base misalignment with a happy looking face in post training… until (as with psychopaths) the mask slips.
@Yoshua_Bengio Just as good psychopaths learn at most to hide their psychopathy until they get caught, the most that a misaligned base model can ever be trained to do is to *seem* good, hide its misalignment, and exploit loopholes whenever it suits its misaligned goals.