Hot take: most companies are overpaying for AI by 100x.
Not because they chose the wrong model.
Because they're using a chat model to do a classification job.
Routing tickets. Tagging products. Detecting sentiment. Checking compliance.
None of these need GPT. They need a specialist.
We built one → https://t.co/dNpEyvR0ZH
• 10x faster than GPT-5.4
• Up to 100x cheaper
• Higher accuracy. Zero schema hallucinations.
• First 10M tokens free.
The era of specialist AI is here. 🧠
#AI #LLMOps #AIAgents
@GaryMarcus What's striking is that general LLMs all look the same. Re-architecting models for specific use cases, like classification ones, offers major accuracy/speed/cost advantages. What we looked at with Classer.
@gnoble79@JG_Nuke@GaryMarcus@MacrostrategyP It's surprising more CTOs aren't keenly looking at sustainable unit economcs (output value/token cost) vs token maxxing.
We have an anti token maxxing approach with https://t.co/Wndd3d3rkg - you only pay for input pricing and get the decision. Simple.
@gregisenberg Interesting observation. I think with https://t.co/jgjJTVZCc6 it would be a bit less likely + also less billing impact given input only pricing. Or someone can use AI to classify the usage of tokens to identify personal project use.
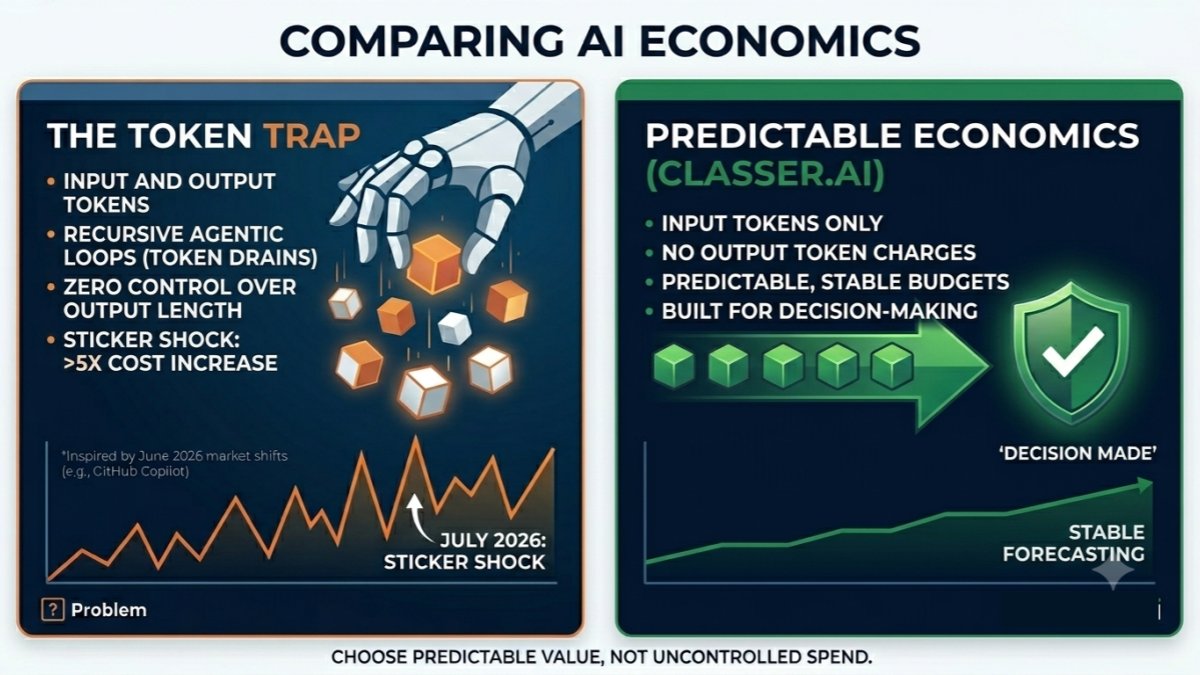
The AI industry has been running on subsidies for two years. Now, the bill is arriving - and for many engineering teams, it’s >5x higher than last month.
GitHub Copilot's shift to usage-based billing gave teams a harsh glimpse of what production AI actually costs.
Some developers burned through monthly credit allotments in a single day! Others calculated bills skyrocketing from $500 to $5,000.
GitHub isn't the exception. It’s the new rule.
As AI agents become more autonomous, they become drastically more expensive. They require deeper reasoning steps, massive context windows, and recursive tool calls. Even recent models, like Gemini 3.5 Flash, will translate to 6x high costs for many agents vs previous models.
But the crisis for CTOs isn't just the price. It's the unpredictability.
Most AI pricing is tied to both input and output tokens. The catch? You have zero control over how many tokens a model decides to generate mid-workflow.
A prompt that costs cents today costs dollars tomorrow if an agent gets caught in a loop or an unexpected reasoning chain. For production applications, budgeting around that volatility is an absolute nightmare.
CTOs want reliable business software pricing, but get casino outcomes.
https://t.co/cS98AfnyhE architecture is built differently. Our models are heavily optimized for classification, routing, and decision-making—not generating poems or videos.
With https://t.co/cS98AfnyhE, the economics are flipped:
• You only pay for input tokens.
• Zero output token charges.
• No surprise bills because a model decided to over-reason.
• No trade-off between cost and accuracy.
The future of AI isn't just about raw intelligence; it’s about sustainable economics. The winners won't be the models that generate the most tokens, but the systems that deliver the highest business value per dollar spent.
Stop paying for generations. Start paying for decisions.
How is your team adapting to usage-based AI billing👇
#LLMOps #AIEngineering
Spot on. 'Cognitive surrender' is a silent killer.
At Stimy AI, we’ve seen that avoiding this trap requires:
1) Productive Struggle > Instant Answers: AI shouldn't do the thinking; it should provoke it. If a tool always hands over the "result", the learning muscle atrophies.
2) Pen and paper with screens > just screens. Research shows the tactile act of writing improves encoding and conceptual integration. Writing on paper beats writing on tablet.
Kids need to show their work. AI needs to act as a real tutor.
Hot take: most companies are overpaying for AI by 100x.
Not because they chose the wrong model.
Because they're using a chat model to do a classification job.
Routing tickets. Tagging products. Detecting sentiment. Checking compliance.
None of these need GPT. They need a specialist.
We built one → https://t.co/dNpEyvR0ZH
• 10x faster than GPT-5.4
• Up to 100x cheaper
• Higher accuracy. Zero schema hallucinations.
• First 10M tokens free.
The era of specialist AI is here. 🧠
#AI #LLMOps #AIAgents