Check out all the amazing work from our @SimonsFdn Collaboration on the Physics of Learning and Neural Computation (https://t.co/TfOKlQxCrE) presented at the main meeting of @ICMLconf#ICML2026
Tuesday
Efficient Learning of Compositional Targets with Hierarchical Spectral Methods,Hugo Tabanelli, Yatin Dandi, Luca Pesce, and Florent Krzakala
https://t.co/wix8AkXVcl
CompleteP for RL: Maintaining Feature Learning When Scaling Deep Reinforcement Learning
M Ganesh Kumar, Adam Lee, Blake Bordelon , Cengiz Pehlevan
https://t.co/Ox6AgFt5LU
Universal One-third Time Scaling in Learning Peaked Distributions
Yizhou Liu, Ziming Liu, Cengiz Pehlevan, Jeff Gore
https://t.co/QzIQf5ANde
Wednesday
A Noise Sensitivity Exponent Controls Large Statistical-to-Computational Gaps in Single- and Multi-Index Models, Leonardo Defilippis, Florent Krzakala, Bruno Loureiro, Antoine Maillard
https://t.co/x4zZVfTHP9
Single-Head Attention in High Dimensions: A Theory of Generalization, Weights Spectra, and Scaling Laws Fabrizio Boncoraglio, Vittorio Erba, Emanuele Troiani, Yizhou Xu, Florent Krzakala, Lenka Zdeborová
https://t.co/CKWt5qGyOR
A Solvable High-Dimensional Model Where Nonlinear Autoencoders Learn Structure Invisible to PCA While Test Loss Misaligns With Generalization
Vicente Mendes, Lorenzo Bardone, Cédric Koller, Jorge Medina Moreira, Vittorio Erba ⋅ Emanuele Troiani, Lenka Zdeborova
https://t.co/rgDY2ieGJR
Deep networks learn to parse uniform-depth context-free languages from local statistics
Jack T. Parley, Francesco Cagnetta, Matthieu Wyart
https://t.co/yrqjxZTrAp
Demystifying LLM-as-a-Judge: Analytically Tractable Model for Inference-Time Scaling
Indranil Halder, Cengiz Pehlevan
https://t.co/ERCgkiOyIt
On the Existence of Consistent Adversarial Attacks in High-Dimensional Linear Classification
Matteo Vilucchio, Lenka Zdeborova, Bruno Loureiro
https://t.co/KDpelqRLla
Robust Stochastic Gradient Posterior Sampling with Lattice Based Discretisation
Zier Mensch, Lars Holdijk, Samuel Duffield, Maxwell Aifer, Patrick Coles, Max Welling, Miranda C. N. Cheng
https://t.co/ikqMhKQOfJ
Teaching Models to Teach Themselves: Reasoning at the Edge of Learnability
Shobhita Sundaram, John Quan, Ariel Kwiatkowski, Kartik Ahuja, Yann Ollivier, Julia Kempe
https://t.co/wjgSrAbJ25
Thursday
Deriving Neural Scaling Laws from the Statistics of Natural Language
Francesco Cagnetta ⋅ Allan Raventos ⋅ Surya Ganguli ⋅ Matthieu Wyart
https://t.co/b6nKYqNulh
Symmetry in language statistics shapes the geometry of model representations
Dhruva Karkada, Daniel Korchinski, Andres Nava, Matthieu Wyart, Yasaman Bahri
https://t.co/Y58fJt9qmk
A Random Matrix Perspective on the Consistency of Diffusion Models
Binxu Wang, Jacob A Zavatone-Veth, Cengiz Pehlevan
https://t.co/snM0EAxv3Q
Hyperparameter Transfer with Mixture-of-Expert Layers
Tianze Jiang, Blake Bordelon, Cengiz Pehlevan, Boris Hanin
https://t.co/dIe32NuQTS
Analytic Bijections for Smooth and Interpretable Normalizing Flows
Mathis Gerdes, Miranda C. N. Cheng
https://t.co/kWCw1EHGn4
Efficient RL Training for LLMs with Experience Replay
Charles Arnal, Vivien Cabannnes, Taco Cohen, Julia Kempe, Remi Munos
https://t.co/EjmNErAFpC
Embedding Trust: Semantic Isotropy Predicts Nonfactuality in Long-Form Text Generation
Dhrupad Bhardwaj, Julia Kempe, Tim G. J. Rudner
https://t.co/MknrTodSaX
What Characterizes Effective Reasoning? Revisiting Length, Review, and Structure of CoT
Yunzhen Feng, Julia Kempe, Cheng Zhang, Parag Jain, Anthony Hartshorn
https://t.co/S18yTP5fy5
From Kepler to Newton: Inductive Biases Guide Learned World Models in Transformers
Ziming Liu, Surya Ganguli, Andreas Tolias
https://t.co/H7eFnYtYQC
We are pleased to announce our incoming Fellows, starting in Fall 2025. We are additionally happy to have this opportunity to partner with the @MIT_SCC through their inaugural Tayebati Fellowship. We look forward to welcoming @CongyueD, Berthy Feng, and @mathisgerdes!
Meet GUD: our new Generative Unified Diffusion model inspired by the Renormalization Group. It generalizes standard diffusion by a choice of basis, a prior and separate noise schedules per dimension. Main author Mathis Gerdes and w/ Miranda Cheng.
https://t.co/LlOifkgtgU
Like to work on cutting edge generative AI using physics tools such as the Renormalization Group, with the briliant mathematician & physicist prof Miranda Cheng at U. Amsterdam (co-supervised by me)? Think no more and apply to below!
https://t.co/goUHXy0V26
My first physics paper is officially published!
Continuous flows making neural samplers for ϕ⁴ lattice theories much more scalable:
https://t.co/eGwfUQWVcZ
with @mathisgerdes, Corrado Rainone, Roberto Bondesan and @adnarim066
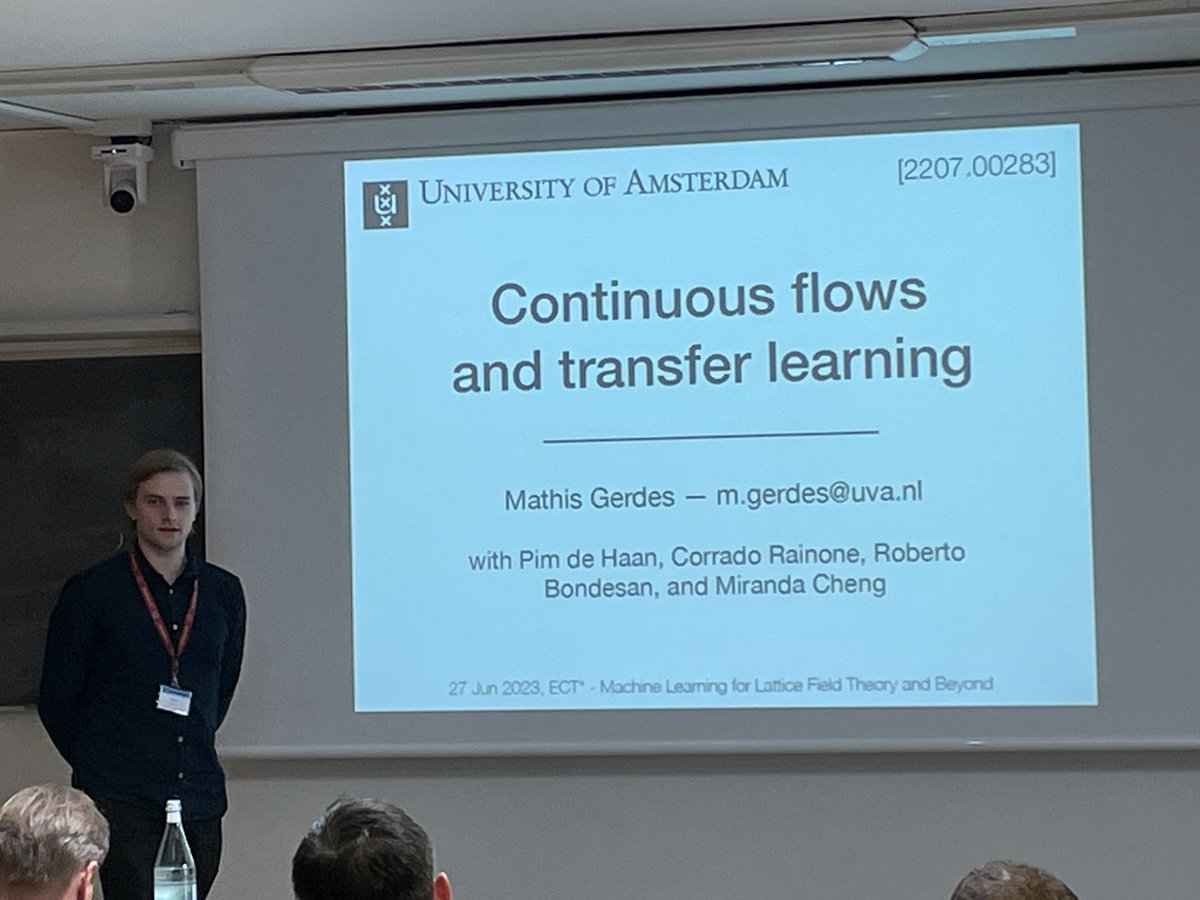
Next up at the @EctTrento#ML workshop: Mathis Gerdes (@UvA_Amsterdam), who explores efficient ways for #deeplearning the distribution of Feynman path integrals with normalising flows using transfer learning. Reuse results from small systems to make progress in larger volumes.
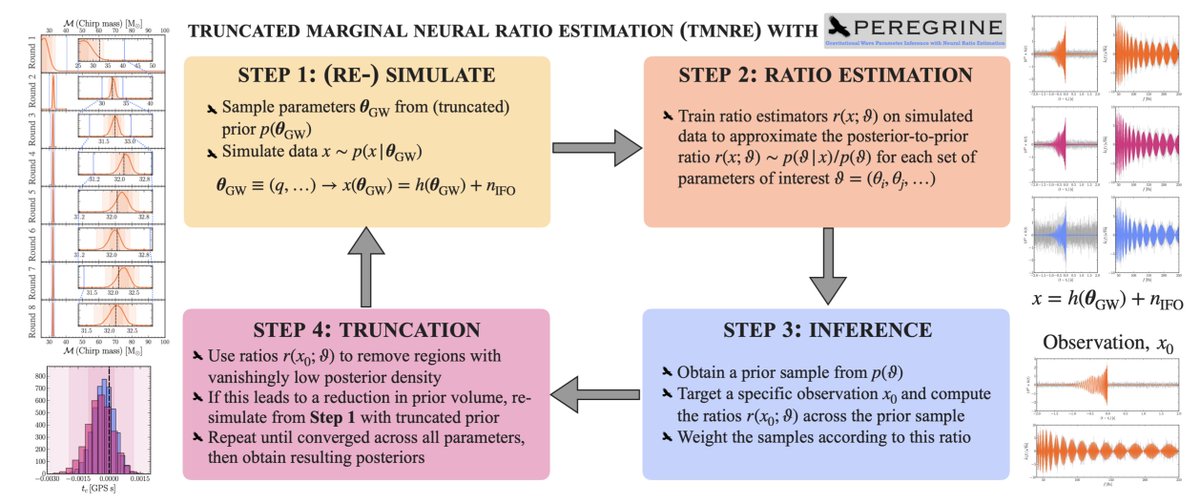
Two new @GRAPPAinstitute papers! Scientific simulation-based inference for stellar streams (https://t.co/fSdFhA1hlZ) and for gravitational waves (https://t.co/oYkS1fsLrc), led by the awesome GRAPPA PhD students @Uddi9, @mathisgerdes and postdoc @James_A_42.
Bringing to you CYJAX, a package to approximate Calabi-Yau metrics at state of the art level. @mathisgerdes has done an amazing job in pushing this through.
Paper: https://t.co/88gDjP9wCR
Code: https://t.co/dGesP7wPyy
Documentation: https://t.co/wiRchalEu1
Bringing to you CYJAX, a package to approximate Calabi-Yau metrics at state of the art level. @mathisgerdes has done an amazing job in pushing this through.
Paper: https://t.co/88gDjP9wCR
Code: https://t.co/dGesP7wPyy
Documentation: https://t.co/wiRchalEu1
Physicists and Mathematicians wanted in Taipei: we are looking for postocs in 1) string theory and quantum field theory. 2) interface between theoretical physics and machine learning. 3) mathematical physics and number theory. See below for links.
The first and most amazing IAIFI Summer School '22 came to an end with my awesome friends paying a visit to the most awesome Penthouse in the world! Grateful to all organizers @jhhalverson, @iaifi_news!
Grateful to be member of IAIFI since its inauguration.
New neural-network-assisted MCMC method that works. One network for different sizes and phases. No exponential growth in training time. Proud of my student and grateful for my teammates for the great work.
https://t.co/NVYRYJpGhy