You can now generate an entire 3blue1brown style video from any research paper with Opus 5.5.
Here’s a 8min video summary of “Regularized Recursive Self Improvement of Agent Harnesses”.
The 90%ile educational YouTuber is fully automated.
ESTO ES JODIDAMENTE INCREÍBLE
un dev en solitario acaba de abrir el código de un reemplazo 100% GRATIS de ElevenLabs que se ejecuta completamente en tu propia máquina.
el repo de GitHub está en 19.4K estrellas.
te permite:
→ clonar una voz desde un clip de referencia limpio
→ doblar cualquier video a 646 idiomas
→ generar audiolibros, dictado, transcripción
→ elegir entre 14 motores TTS en lugar de uno
ElevenLabs soporta 32 idiomas. esto hace 646.
sin cobro por carácter. sin límites de uso. ningún audio sale nunca de tu computadora.
guarda esto para después.
os dejo el repo abajo
When I set up a new Hetzner VPS first thing I do install Tailscale and once I'm in via Tailscale lock down the firewall to only accept web traffic on HTTPS 443 for Cloudflare IPs and SSH 22 for Tailscale IP
That way nobody can get in
I know I keep repeating this but it should be basics of setting up a new VPS
So basic IMHO it should be part of any VPS service to default install Tailscale and enable it so it's the only way to get in
Why?
A VPS server is just like your laptop or destop computer but now imagine if it's connected to the entire internet with 8 billion people that can access it and try hack it
You want to only have it accessible to you
And if you want to host a website on your VPS (like I do), you should only let Cloudflare access your VPS so it can stand in front and block any hack attempts
Never expose a VPS to the world wide web which realistically is the world WILD web
Claude Code + Nano Banana 2 is f*cking cracked 🤯
I built a system inside Claude Code that researches any brand, writes 40 ad prompts from scratch, and fires them all to Nano Banana 2.
One brand name + one URL = 40 production-ready static ads.
All inside Claude Code.
I took @alexgoughcooper's brilliant framework and automated the whole thing inside Claude Code.
Perfect for DTC brands and agencies who need high-volume ad creative without briefing a designer or spending hours in Canva.
If you're finding winning ad concepts on Meta and manually recreating them one at a time in Higgsfield — copying prompts, pasting product details, tweaking aspect ratios, downloading, organizing...
This system eliminates the entire loop:
→ Give Claude a brand name and URL
→ It researches the brand's fonts, colors, packaging, and photography style
→ Builds a Brand DNA document from scratch
→ Fills in Alex's 40 proven ad templates (headline, us vs them, testimonial, UGC, review cards, stat callouts) with brand-specific details
→ Fires every prompt to Nano Banana 2 with your product photos as reference
→ Downloads finished ads into organized folders with an HTML gallery
No Higgsfield.
No manual prompt filling.
No copy-pasting between tools.
What you get:
→ 40 ad formats filled with your exact brand colors, fonts, and copy
→ 4 variations per format so you pick the best output
→ Product photos passed as reference so the model matches your real packaging
→ A reusable system — new brand, new folder, same pipeline
Built 100% in Claude Code with Nano Banana 2.
I put together a full playbook & Loom video showing the exact process to set this up yourself.
Want access for free?
> Like this post
> Comment "NANO"
And I'll send it over (must be following so I can DM)
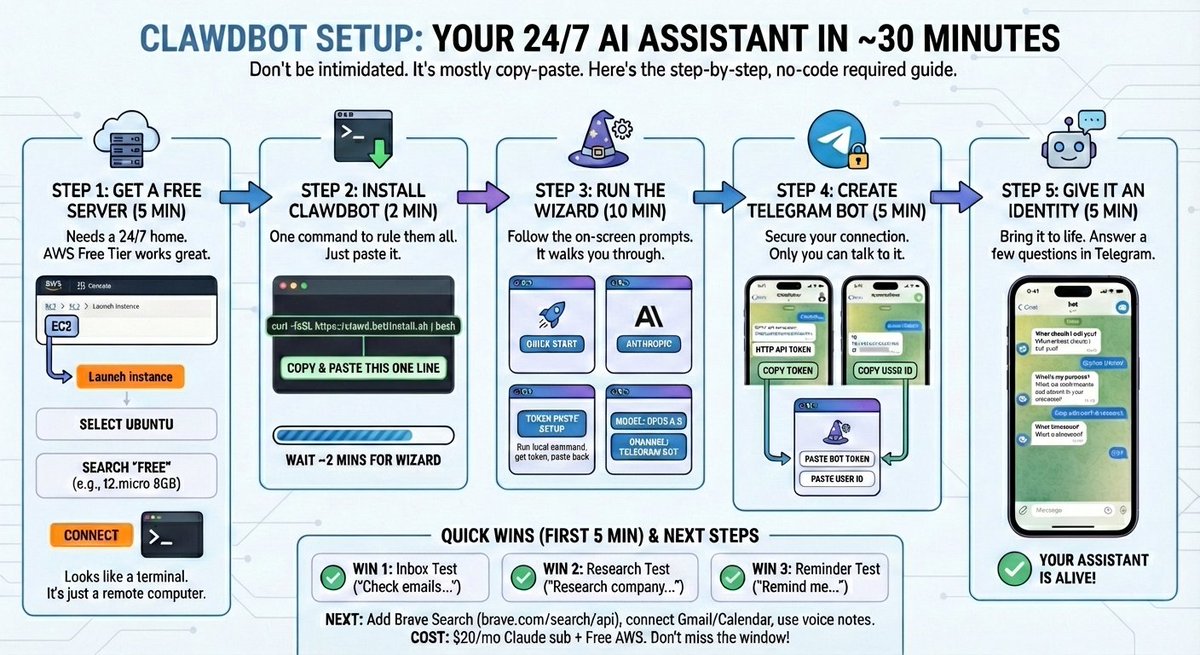
Ok Clawdbot is insane.
People can't stop building and founders are making money with it.
10 wild examples + how to setup (No-code required guide in ~30 minutes).
Bookmark this👇
I scaled Chatbase from a side project to a $6M ARR startup. No sales team, no VCs, just product‑led growth.
Here is the full strategy for scaling to millions purely through product-led growth.
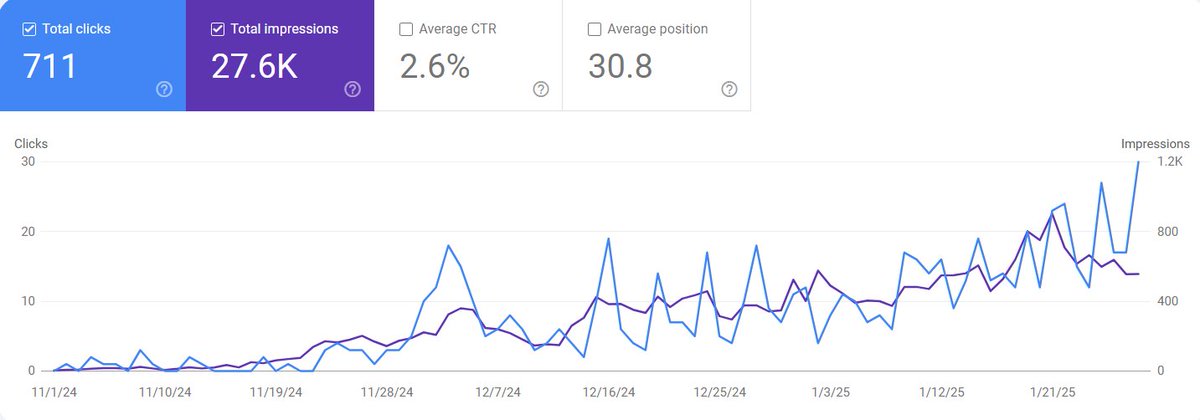
Traffic for my app keeps increasing exponentially on autopilot with pSEO. 📈
Every 3 hours a new page is indexed by Google, driving long-term profitable organic traffic. 🌱
Here's how you can do it too, full guide 👇
It's so exciting to be in tech right now
He's 100% right, it's like the early days of the internet around 1995 again
Everything was new and you had endless opportunities, you could build the first web browser, or mail app, or video streaming tech, etc
But instead of internet, it's now the early days of AI and 1995 is 2025
Most people don't realize it but this is a VERY special time with SO many opportunities right now, all you need is to build
And times like these only happen every ~30 years if at all, jump on it!
AI coding = Proper Documentation + Detailed Instructions
It's like a smart kid who can code but doesn't know the best practices of code.
You need to tell AI what exactly you want:
- web app?
- features?
- structure?
etc
Here's how you can make AI your full stack developer:
🧵
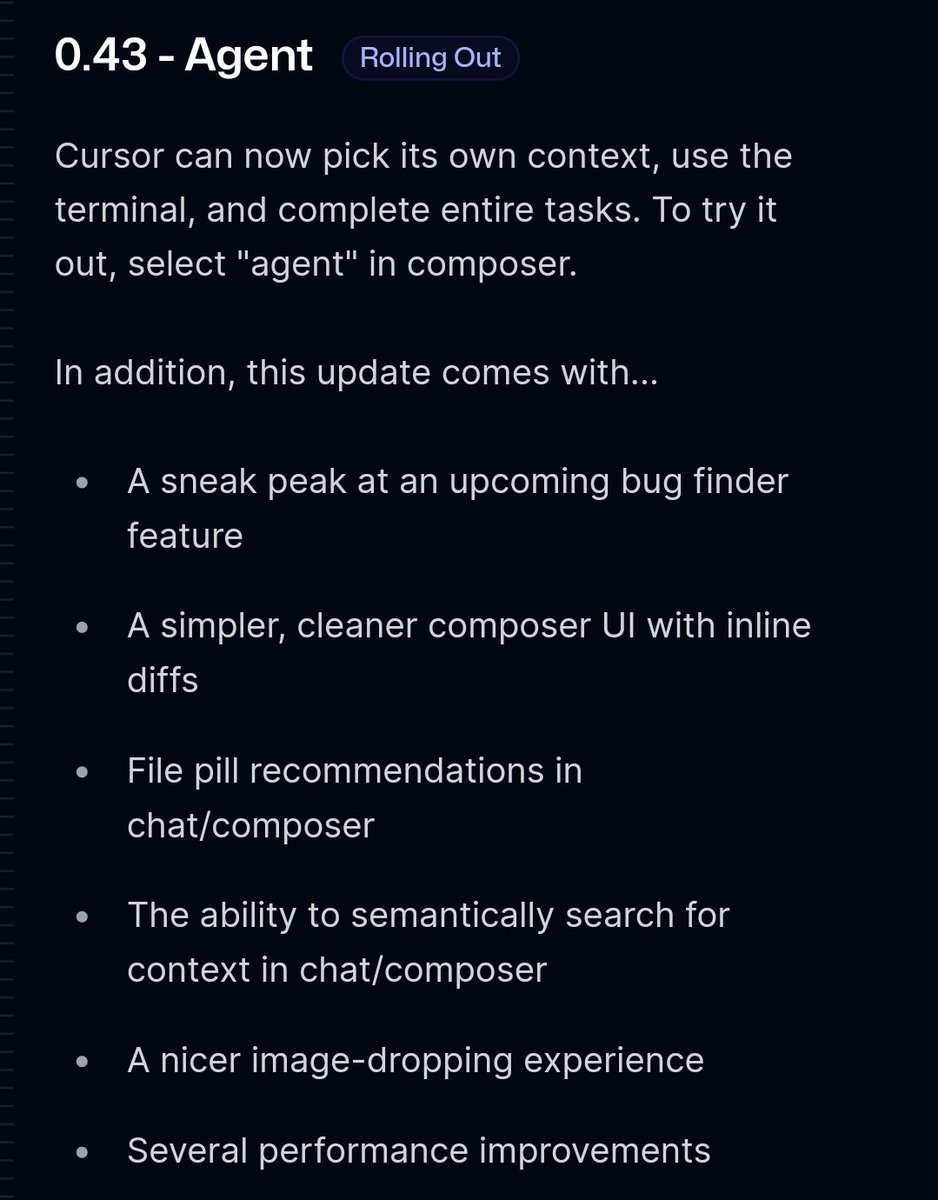
Cursor is rolling out Agents.
It can now pick its own context, use the terminal, and complete entire tasks. 🔥🔥
What's next for Software developer?? Just open the IDE and chill???
Traditional RAG vs. HyDE, visually explained!
One critical problem with the traditional RAG system is that questions are not semantically similar to their answers.
Consider the example where you want to find a sentence similar to "What is ML?" It is likely that "What is AI?" will appear more similar than "Machine learning is fun."
This semantic dissimilarity leads to several irrelevant contexts being retrieved during the retrieval step.
HyDE solves this issue.
The visual below illustrates how this approach differs from traditional RAG.
Here's how it works:
- Use an LLM to generate a hypothetical answer (H) for the query (Q). This answer doesn't have to be entirely correct.
- Embed the answer using a contriever model to obtain E. Bi-encoders trained with contrastive learning are generally used for this purpose.
- Use the embedding E to query the vector database and retrieve relevant context (C).
- Pass the hypothetical answer H, the retrieved context C, and the query Q to the LLM to produce a final answer.
Done!
Now, of course, the hypothetical generated will likely contain hallucinated details.
But this does not severely affect the performance due to the contriever model—one which embeds.
More specifically, this model is trained using contrastive learning and it also functions as a near-lossless compressor whose task is to filter out the hallucinated details of the fake document.
This produces a vector embedding that is expected to be more similar to the embeddings of actual documents than the question is to the real documents.
Several studies have shown that HyDE improves the retrieval performance compared to the traditional embedding model.
But this comes at the cost of increased latency and more LLM usage.
Enjoyed this? You should also my RAG series! From building and optimizing RAG apps to evaluating performance and crafting agentic & multi-modal systems—it's all here.
Link in the next tweet!
_____
Find me → @akshay_pachaar ✔️
For more insights and tutorials on AI and Machine Learning!
I used the new Cursor agent + CopyCoder to build a Calendly frontend clone in 20mins
Cursor agent now:
- runs terminal commands
- picks it's own context
- executes more jobs with one prompt
Crazy where this is going
Here's a quick demo using the Claude desktop app, where we've configured MCP:
Watch Claude connect directly to GitHub, create a new repo, and make a PR through a simple MCP integration.
Once MCP was set up in Claude desktop, building this integration took less than an hour.
✨ First AI talking video made from within Photo AI with the new [ 💬 Make talking video ] interface
AI photo -> AI video -> AI lipsync -> AI captions
Obviously not very passable yet, BUT it's a start and with voice and lipsync models improving so fast I think it'll be passable in 3-6 months
One thing @elevenlabs is severely missing is background sounds which I didn't add here manually just to show the state of things, is there any good TTS API that DOES have bg noise?
Captions are by CapCut, but it'd be nice to be able to do that in-app with Photo AI too, not sure where to start with that though
Again cool thing of this vs HeyGen is it has no limits to where you wanna place yourself or your model, the source is just a prompted AI photo in Photo AI that becomes a talking video with 2 clicks