🇰🇷 #ICML2026 Alert! 🇰🇷
Come check out our new work with @mathuvu_ and @ylecun 👀
📍 Starting 2PM - Poster #1606
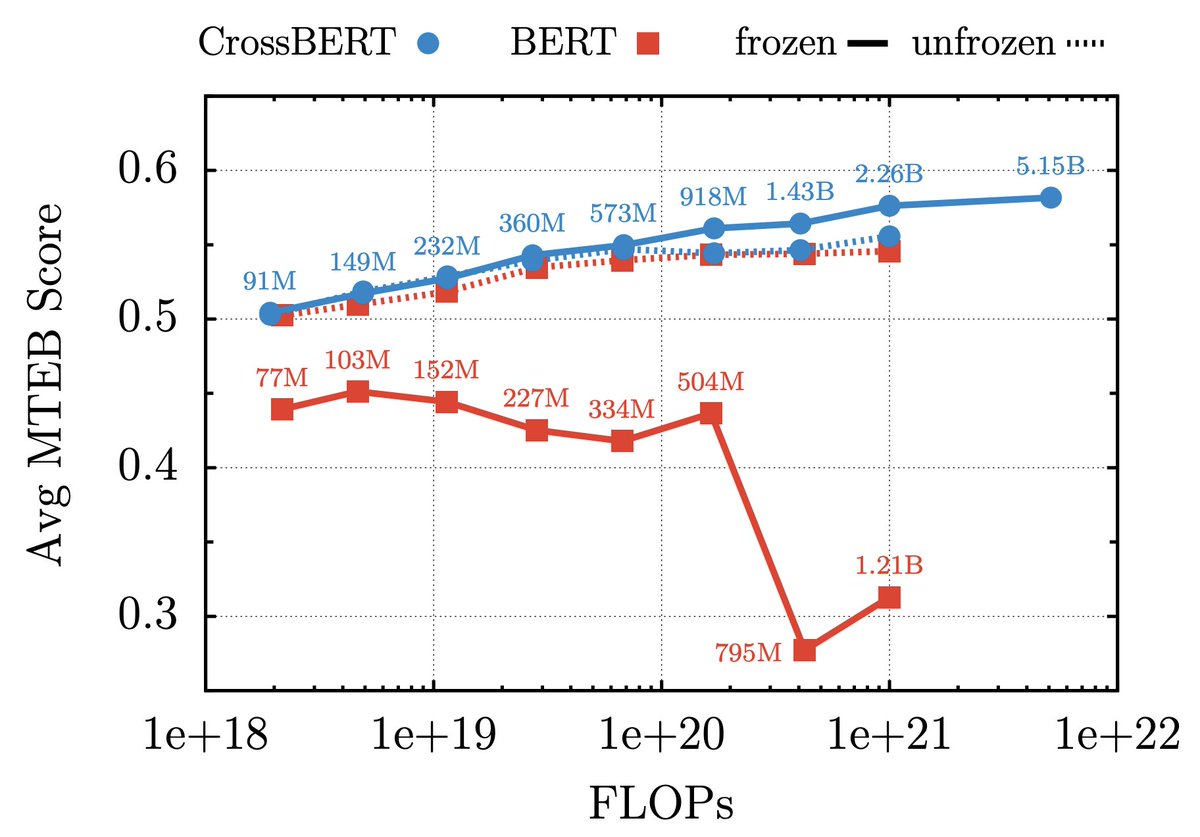
💡 Representation learning for text done efficiently - clean scaling, 2× retrieval, ~100× less compute.
🚨 Spoiler Alert: BERT does not scale
V-JEPA: a step towards getting machines to understand how the world works by watching.
The Joint embedding Predictive Architecture (JEPA) is a non-generative architecture that predicts the representation of a signal from a corrupted or transformed version of that signal.
In V-JEPA the signal is a short video that is corrupted by masking a large portion of each frame.
After training, the learned representation is used as input to a simple classifier tested on action recognition from videos.
The system gives excellent results on action recognition on SSv2 and K400 with frozen backbone and fine-tuning.
blog post: https://t.co/mfLvtvk8jj
paper: https://t.co/UuABuXRsXp
code (CC-BY-NC): https://t.co/2LuxnfPGH6