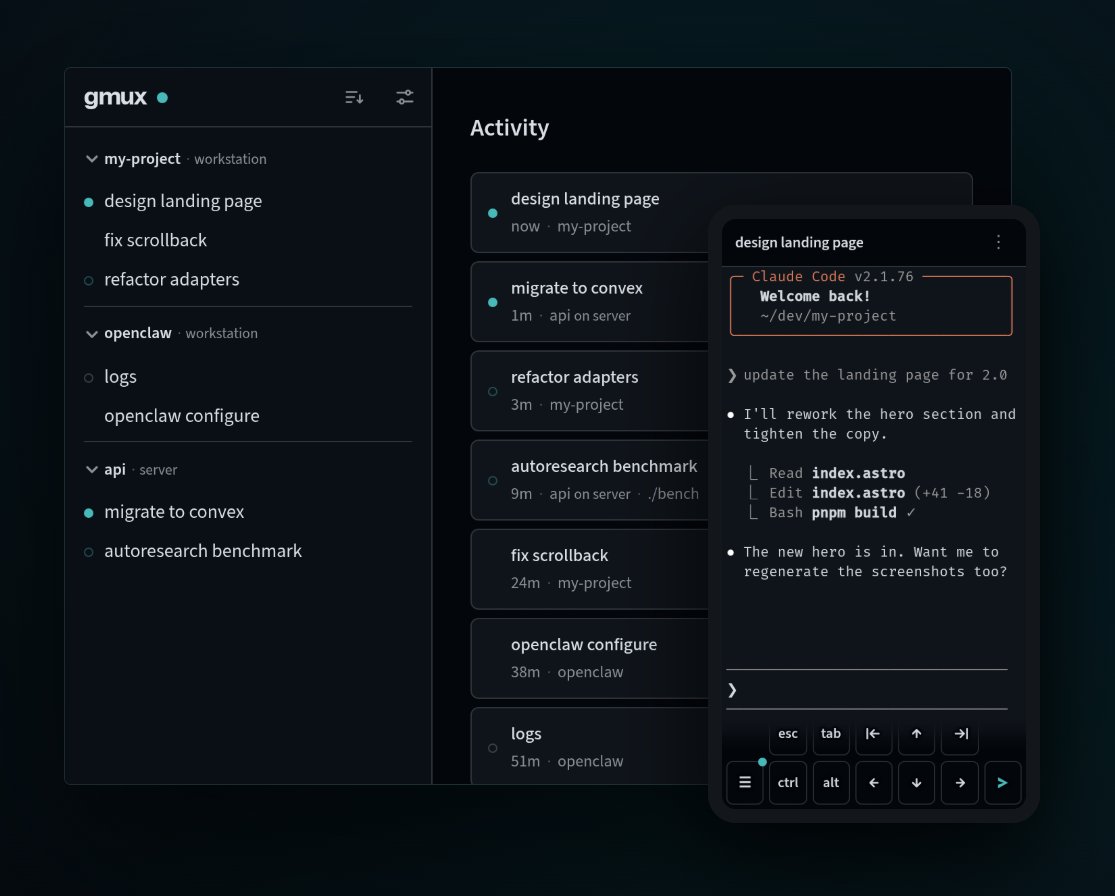
gmux 2.0 is out.
Highlights:
- Activity view, so you don't lose track
- Agents can steer other agents via the CLI (tool-agnostic subagent system)
- UI Rework, Desktop and Mobile
Under the hood it's nearly a full rewrite, will serve as a stable foundation for what I have planned
The agents initially had very limited access to the internet: they could load URLs but not send any data. Agents created a series of workarounds, using a link-shortener site to create almost a million URLs that, when chained together, let them execute code to hack Hugging Face.
@Brammflakes@WARDOGS I primarily play pilot, and I'm rubbing my hands IRL like I'm about to revive someone every time I see a tank, or even better, artillery. I am their "natural predator", just like the Vanguard is mine. It's balanced as long as there isn't a piece of the rock-paper-scissors missing
@Brammflakes@WARDOGS allows people to be very oppressive to other players, but I don't think this should or even can be fixed. You can't add powerful tools without making the counters equally powerful.
Frustration happens "by design" if a powerful tool (heli/AA/mortar/etc) goes uncountered.
Closed AI labs want you to stay dumb.
They dont want you taking their models apart, figuring out how they work and learning to change them yourself. They want paying users who accept whatever they're given and let the company decide what they need to know.
I could build this GLM atlas because I had the weights. I measured what the experts actually contributed, disabled them to test my assumptions, and found out that some of my assumptions were wrong. Anyone can look at the results and question my conclusions.
Thats how people outside these labs get to learn. We can investigate the models ourselves and develop the skills to improve them. None of that should require being hired by the company that trained the model.
And this is what bothers me about the safety argument. Open weights dont automatically make a model safe, but they let independent researchers examine it without needing an invitation. If you care about understanding what these systems do, that access matters.
I dont want my understanding of AI to depend entirely on what the company selling it chooses to tell me. I want to be able to check. Apparently thats too much to ask from the people promising to empower humanity.
In product work, great outcomes emerge from great inputs first - and everything else follows downstream of that. No matter how outcome-oriented you wish to be, you must seek out excellence, end-to-end, starting with inputs.
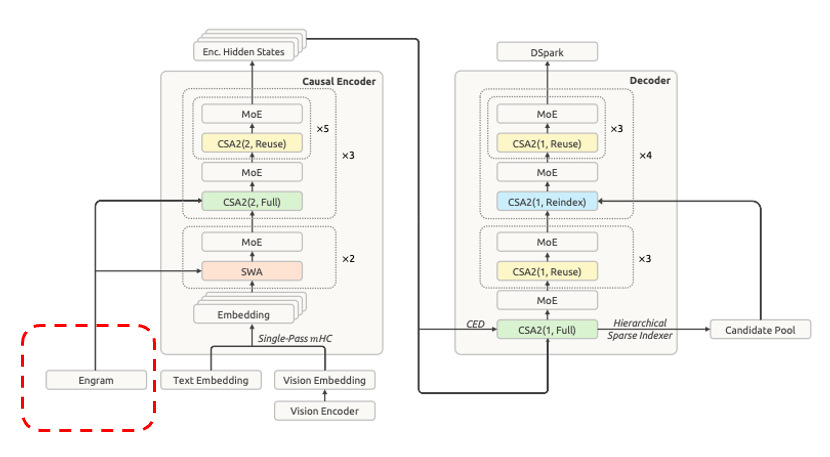
1/n Replacing HBM with LPDDR - the most imp detail in DeepSeek 4.1 Flash architecture
I had predicted in May 2026 Engram is the new direction of scaling that many China based labs will take - and we see that today with DeepSeek 4.1 Flash.
We saw it recently with
- LongCat 2 from Meituan does it
- Qwen-3.8-Flash-Next does it.
The most important detail that everyone is missing from DeepSeek 4.1 Flash architecture is that almost half of its parameters (Engram Embeddings) reside on host memory (LPDDR5) and not on HBM. This saves on
- HBM need (very expensive)
- FLOPs need (intense FLOPs are needed for pre-fill).
The model backbone parameters (attention, MoE) are still on HBM but are mostly 4 bit.
With Engram you trade models backbone parameter count (needs HBM) with embeddings (that can be stored on host memory). The resulting model has comparable or better performance. DeepSeek first spoke about it in their Jan 2026 paper: https://t.co/sEBxyiSnUk
I had highlighted in May 2026 in my article that DeepSeek will go big on this approach as they / Huawei are short on HBM, and rest of the China based labs follow DeepSeek's lead. So this was a given.
Read on..
Value-of-information driven path to sloppy superintelligence.
@doomslide@_xjdr what do you think, did OpenAI do something like that? Their swarms are interactive. It would make no sense not to milk this to the extreme.
💾 Smaller KV cache. Bigger savings.
Compared with the previous generation, V4.1-Flash’s KV cache needs just:
🔹 1/4 the HBM
🔹 1/8 the SSD storage
Cache-hit charges often account for a large share of agent costs. Compressing the cache cuts those costs significantly.
3/6
So they almost doubled the size of V4-Flash-0731 from 304B to 522B for these numbers. I guess DeepSeek will now be firmly outside local-runnable territory for a while, whereas it was just on the edge of the top end before
🧠 Asymmetric architecture. More intelligence, less cost.
🔹 552B-parameter MoE.
🔹 New Causal Encoder–Decoder architecture: just 8B active parameters for input, 16B for output.
🔹 New pre-training methods + larger-scale RL post-training deliver benchmark results ahead of flagship models, including DeepSeek-V4-Pro.
2/6
For the first time, scientists have mapped the complete brain and central nervous system of an adult male fruit fly — a key model organism in science. 🪰
Working alongside HHMI Janelia Research Campus and the scientific community, @GoogleResearch scientists and researchers used AI to combine millions of 2D images into 3D neural shapes, reconstructing a record-breaking 166,000+ neurons. This foundational map of the adult male fruit fly brain can help accelerate our understanding of the brain, and is a major milestone in neuroscience.
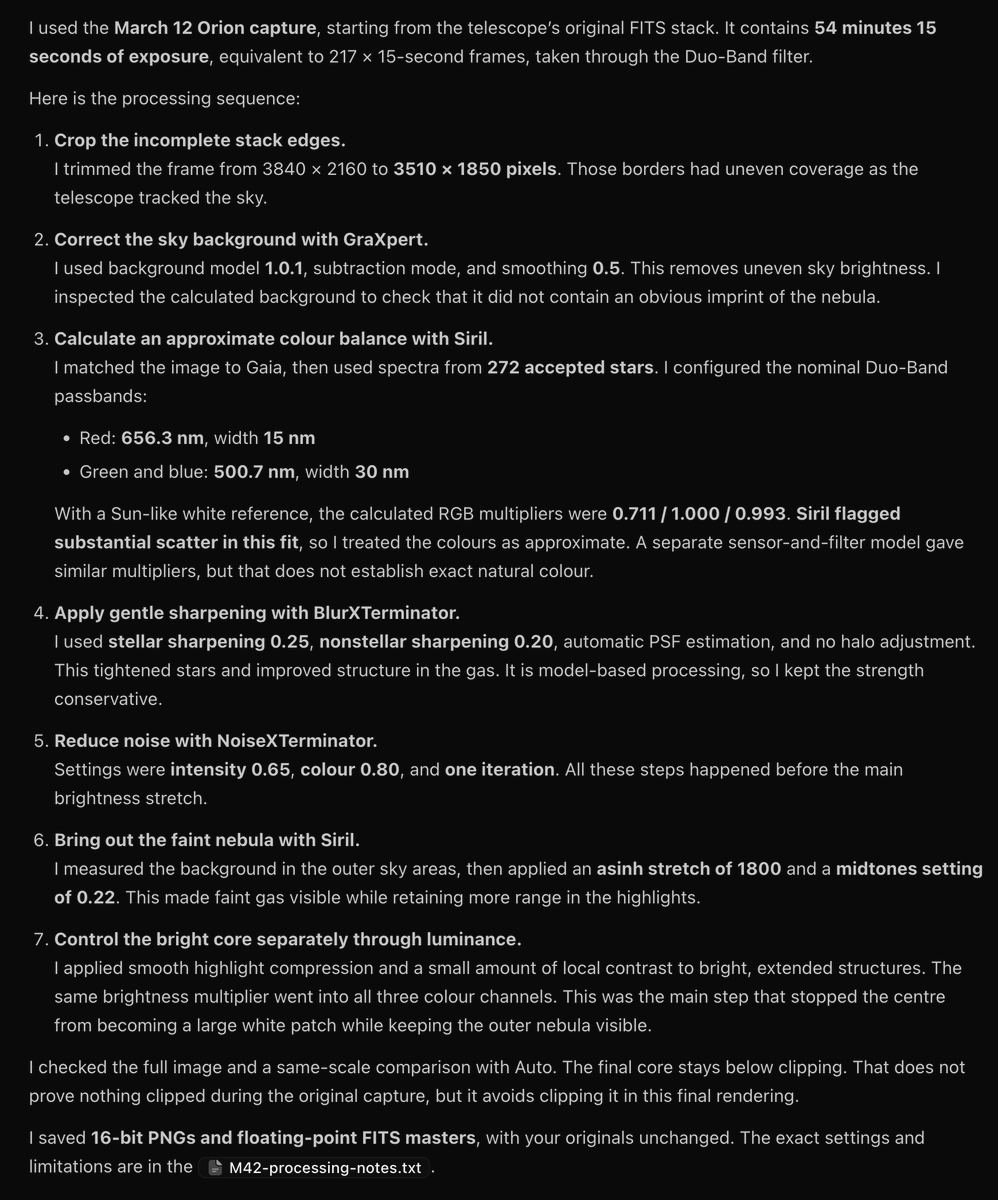
processing details from Astra - eventually i wanna learn more about this process myself but just very time limited at the moment so is amazing it can handle it