I put Jev (TypeSafe's classifier model) in front of an agent loop to pick skills before the main agent loop ran. Here's what I actually learned and the changes you need to make to your skill disclosures 🧵
Efficiency gains are relative to the base model. Sonnet loads skills one at a time: 15% fewer calls, 10% cheaper. Haiku already batches and barely moved. Latency: flat on both.
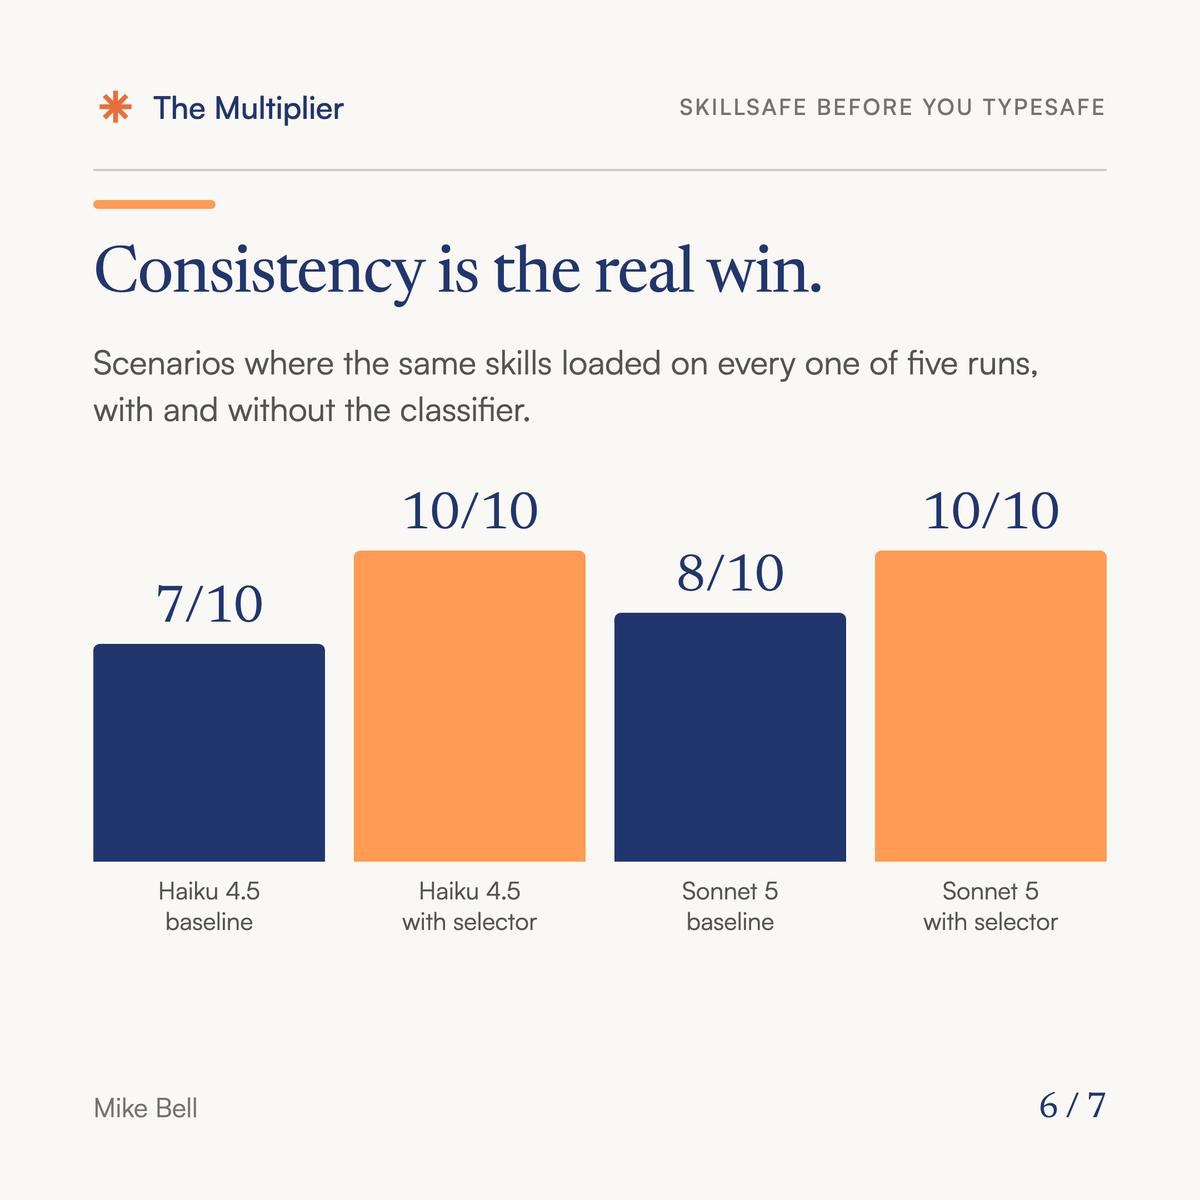
Consistency is the real win. Same skills loaded on every run of every scenario, both models.
@sharran Solid list overall but re 3 I think LinkedIn will figure out how to identify and shut down the IPs of the automation companies powering the majority of the slop and start mass-banning users.