Hiring Research Interns in Singapore on agents, coding, and environment construction. Visa sponsorship available
Looking for candidates with hands-on research in at least one of: Agentic systems, Coding, Environment simulation, Post-training
Minimum internship: 6 months
Interested? Send your CV + 1-2 representative works (paper / blog / repo / project) to:
hanzedong at microsoft dot com
OSWorld 2.0 is here.
This is a new batch of ever solid tasks for CUA. Leading us to the next stage of changing the way we let AI free humans’ labour.
Congrats and be proud of the team.
🚨 New paper alert!🚨
🤔Can we train long-context LVLMs effectively without massive token budgets?
🤯Yes! Our MMProLong extends Qwen2.5-VL-7B from 32K to 128K with only 5B tokens, and generalizes to 512K without additional training.
In our new paper, we systematically study Long-Context Continued Pre-Training (LongPT) for LVLMs and introduce MMProLong.
🔥 Starting from Qwen2.5-VL-7B, MMProLong:
• extends the context window from 32K to 128K
• maintains strong performance at 256K/512K without additional training
• generalizes zero-shot to webpage needle retrieval, VTCBench, and long-video understanding
• uses only a 5B-token training budget
📄 Paper: https://t.co/DrnfDU97Tf
🎯 Motivation
Long-context modeling is becoming a core capability for LVLMs, enabling long-document, long-video, and long-horizon agent tasks. However, practical recipes for training long-context LVLMs remain underexplored, as many existing systems are closed-source or only briefly describe their data and training choices.
In MMProLong, we systematically study long-context continued pre-training (LongPT) for LVLMs. Starting from Qwen2.5-VL-7B, we extend the context window from 32K to 128K with only a 5B-token budget, while maintaining strong performance at 256K and 512K contexts without additional training.
🔥 Key Finding
Long-document VQA is not only a data source for document understanding, but also an effective vehicle for learning general multimodal long-context capability.
Although MMProLong is mainly trained on long-document VQA, it generalizes zero-shot to broader long-context multimodal tasks, including webpage-based multimodal needle retrieval, long-context vision-text compression, and long-video understanding.
🔍 Practical Takeaways
Our ablations suggest that:
Training a 128K model does not mean simply packing more 128K examples. A balanced sequence-length distribution is more effective.
Retrieval remains a core bottleneck for long-context LVLMs: models need to locate sparse evidence before reasoning.
Pure long-document VQA training largely preserves short-context ability, reducing the need for heavy short-data mixing.
Between theorem recognition and theorem proving lies theorem understanding.
We introduce LiveMathematicianBench: a live, contamination-resistant testbed for research-level mathematical reasoning, built from post-cutoff arXiv theorems.
It probes a capability that existing benchmarks rarely isolate: whether models can understand theorem statements, track delicate assumptions, reason over logical structure, and leverage proof-level guidance.
https://t.co/TZ8KYTVCmG
Introducing Nemotron-Terminal: a systematic data engineering pipeline for scaling LLM Terminal Agents.
We bridge the gap between open models and proprietary models with a fully open synthetic-to-real trajectory pipeline.
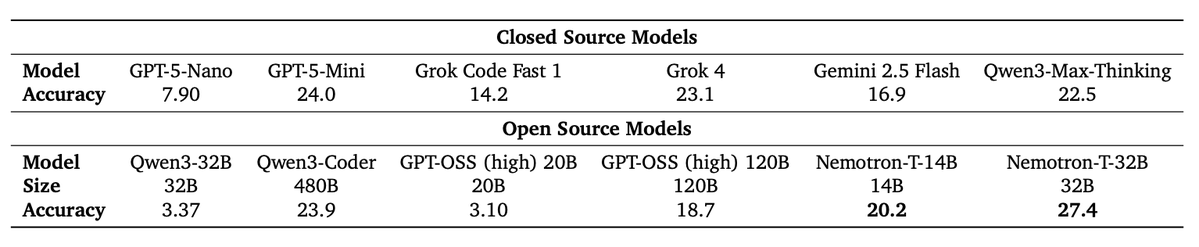
🤯The payoff: SFT on our Nemotron-Terminal-Corpus boosts Qwen3-32B from 3.4% → 27.4% on Terminal-Bench 2.0 (+24.0), rivaling models multiple its size.
What makes it work?
🌟Terminal-Task-Gen: A lightweight data curation pipeline that seamlessly combines the adaptation of existing datasets with robust synthetic task construction.
🌟Nemotron-Terminal-Corpus: A massive, open-source dataset covering diverse terminal interactions, which contains explicit planning and execution traces for complex long-horizon tasks.
And we’re releasing everything:
📦 Nemotron-Terminal-Corpus (Large-scale dataset)
🤖 Nemotron-Terminal models (8B, 14B, 32B)
Paper: https://t.co/ORIZ01sav1
HF Daily: https://t.co/nSH4hu7I5D
Models & Data: https://t.co/J1Zc22M95r
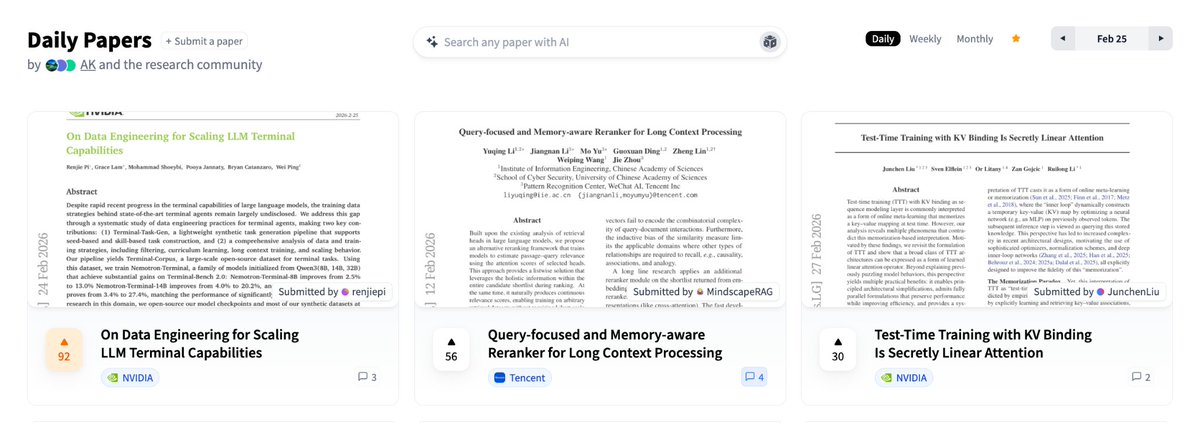
Our tech report just hit the #1 spot on Hugging Face Daily Papers!
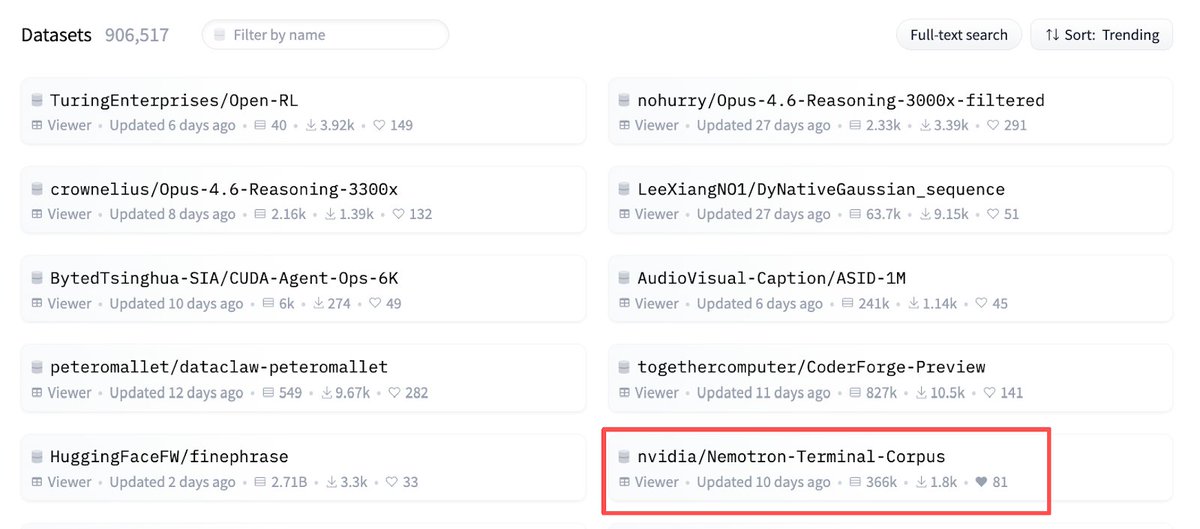
We're also incredibly excited to see the open-source community putting our work to the test, with the Nemotron-Terminal-Corpus dataset currently trending at over 1,800 downloads and counting.
We can't wait to see what the community build with it!
Thank you for sharing our work!
The code, data, and models have been open-sourced for the research community’s benefit:
https://t.co/Uf0lzonz9Y
https://t.co/fddsqHGZcw
https://t.co/2qNOYO71CJ
🚀 Introducing MA-LoT Theorem Framework: An open-source multi-agent framework utilizing the Long Chain-of-Thought to boost automated theorem-proving🎉
✅ Achieving 61.07% accuracy rate under pass@32 on MiniF2F-Test outperforming Goedel-Prover, Lean_STP and DeepSeek-Prover-V1.5
🔥 Proposing LoT-TL training-inference framework to train LLMs with field-specific Long CoT ability.
🤖 Composing the multi-agent system that combines the advantage of both whole-proof generation and tree-search.
[1/n]
Paper: https://t.co/J9m5i4lNf6
Website: https://t.co/OjQ9P0fYAN
Huggingface: https://t.co/tXsLlxnfvb
Github repo: https://t.co/PZZqk9wAo2
Wonderful collaborators: @rui4research@TheTallEric@shizhediao@RenjiePi@mircale2003@JunjieHu12
Excited to share that EmbodiedBench was selected for an Oral at ICML 2025!
We recently added results for new models (InternVL3, Gemma3, Ovis2) and released a large agent trajectory dataset on 🤗: https://t.co/91OLQaaHbT
Try training and evaluating your MLLM for embodied agents!
What happend after Dream 7B?
First, Dream-Coder 7B: A fully open diffusion LLM for code delivering strong performance, trained exclusively on public data.
Plus, DreamOn cracks the variable-length generation problem! It enables code infilling that goes beyond a fixed canvas.
📢 Update: Announcing Dream's next-phase development.
- Dream-Coder 7B: A fully open diffusion LLM for code delivering strong performance, trained exclusively on public data.
- DreamOn: targeting the variable-length generation problem in dLLM!