Low-level developer. Peakbagger. Private Pilot.
Founder/CTO Ringcube (acquired by Citrix) and Deepfactor (acquired by Cisco).
Building hypervisors and OSes.
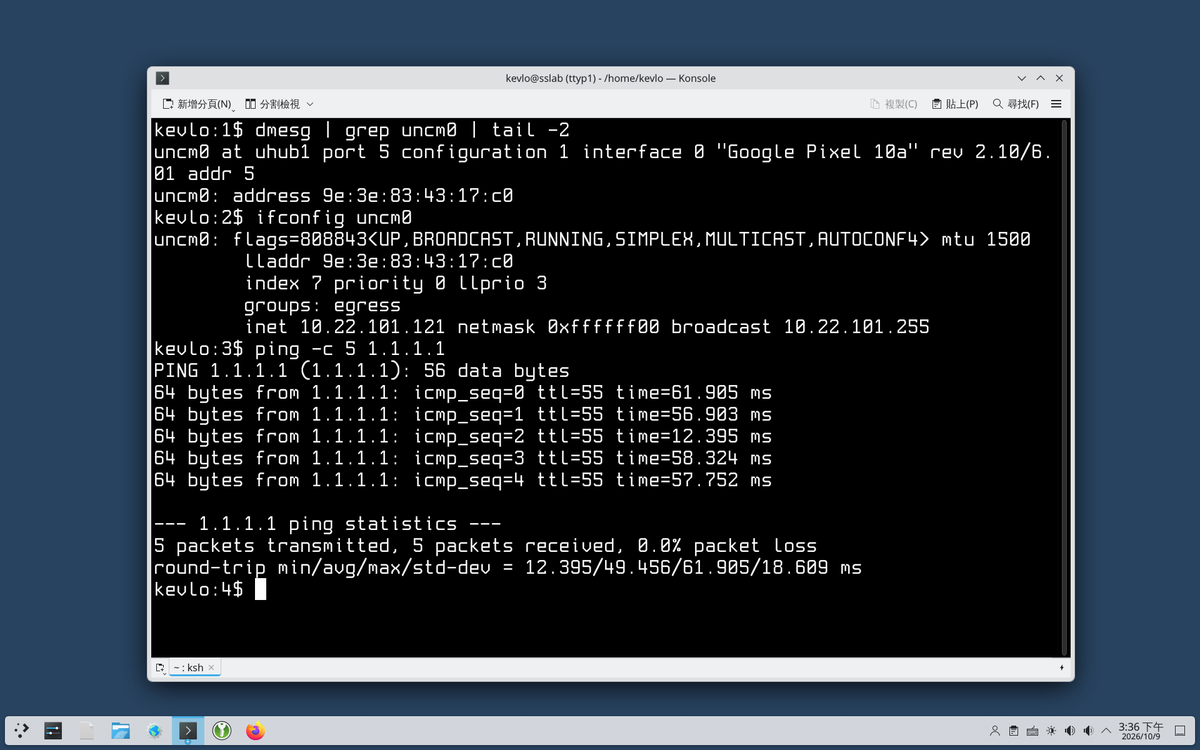
Congratulations to the @openbsd team on their 8.0 release!
Looks like 8.0 received tons of improvements to multiple hardware architectures, expanded and improved hibernate support, and a boatload of fixes.
Keep up the excellent work, OpenBSD!
https://t.co/LYIPeoBWmN
Let me show you how ridiculous the amount of computation inside a modern AI model actually is.
This is Qwen3.8-27B answering one of the easiest questions imaginable:
“What is the capital of France?”
Thinking is disabled.
The requested response is one word.
Paris.
But the GPU still has to perform an enormous amount of numerical computation before those four letters appear.
The visualization shows individual mathematical operations from the model’s actual computation. Each frame represents only a tiny slice of what is happening inside the network.
And here’s the part that completely changes how you see the video:
Between the frames, roughly 7.2 million operations are being skipped.
The complete inference for that single-word answer involved an estimated 25.8 billion numerical operations.
The RTX PRO 6000 Blackwell completed the computation in roughly 13 milliseconds.
That’s 0.013 seconds.
At 60 frames per second, if you tried to visualize every operation one by one, you’d need more than 13 years of video to represent what the GPU processed in those few milliseconds.
The visualization you’re watching is therefore massively slowed down compared with the actual computation.
The GPU is effectively doing in milliseconds what would take years to display at human-friendly speed.
And remember, this is a 27B parameter model answering a trivial question with thinking turned off.
Now scale the idea up.
Hundreds of billions of parameters.
Longer context windows.
Multiple reasoning steps.
Tool calls.
Image and video inputs.
Thousands of concurrent users.
Suddenly the enormous compute requirements of AI don’t seem quite so mysterious.
A language model isn’t sitting there “thinking” in the human sense.
It’s executing an absurd number of numerical operations across billions of learned parameters, moving data through layers, calculating activations, and repeatedly predicting what should come next.
And all of that happens before you see something as simple as:
“Paris.”
That’s why GPU hardware is so ridiculous.
Whether you’re running a giant datacenter accelerator or squeezing a local model onto an old consumer GPU, you’re watching silicon perform billions of calculations at a speed that is basically impossible for humans to intuit.
We see one word.
The GPU sees billions of operations.
Appreciate your GPU.
They’re genuinely insane pieces of engineering.
@codertlr@gabriberton Right. This.
Just because the model emits a tool call request to upload your secrets shouldn't automatically result in being pwned. This is a harness and environment problem not a model problem.
*All* models can be convinced to do bad shit. External controls are always needed.
This is why Omarchy Linux was needed: The anti-AI stance of many Linux projects, which is closely connected to their political views, is becoming a real problem and hinders progress.
Omarchy is completely free of such inhibitions and embraces AI.
Dusting off this tweet from April because this gap in shared understanding of LLM capability is *widening*. It's now less "two groups of people speaking past each other" and more a sharp funnel.
- Napkin math somewhere around 6B people (~75% of the population) have barely come in contact with LLMs at all.
- Around 1-2B (~20%) are casual and infrequent users of free-tier ChatGPT-like products. This group sees derpy chatbots and treats them a bit like a better Google search, a writing aid, or etc. Maybe an agent tries to book you a flight. I have non-tech friends who (reasonably, imo) say they have not much use for it at all. Even many professionals outside of math&code are in this tier. For example, execs and many other functions spend a lot of their time talking to other people, so while they understand what is happening intellectually, it is still second-hand and a bit abstract.
- Now we get to professional use of frontier-grade LLMs in math&code. Somewhere around 20M people (0.2%) see first-hand that large, complex projects that used to take them weeks/months can now be completed by agents with a prompt. Building apps, copying apps, translating apps, decompiling apps from binaries... This has all happened very quickly and recently - less than 1 year ago, I was writing code manually by hand, typing memorized computer code commands into a code editor character by character, occasionally pressing Tab to autocomplete a little chunk of code.
- And finally we get to the ~5,000 people (~0.00006%) with access to frontier-grade systems internally. The external world has seen the preview. It looks like swarms of thousands of agents collaborating over weeks on software mega projects: minting zero days, running cyber attacks and defenses at machine speeds, discovering new science, advancing the frontier of mathematics. Things that would have taken top professionals in the industry years of work. Meanwhile, human review and comprehension are starting to fall behind. For example, people are still involved in the "archeology" of the OpenAI-HF incident from many months ago. Mathematicians may be poring over the 722 manuscripts on frontier mathematics for a while.
The funnel is driven by a combination of factors:
1. The impact scales with ambition, problem size, and horizon. A question with a paragraph answer barely stresses the system. You need a reservoir of big, difficult problems that you really care about. This aspect drives the consumer / professional dimension of the funnel.
2. The jaggedness of the system (which I have written about a lot separately). Capability peaks in domains that are digital, verifiable and economically valuable. This is because LLM capability emerges from reinforcement learning on verifiable rewards on a curated environment mixture driven by revenue potential. This aspect primarily drives the area (e.g. math&code) dimension of the funnel.
3. Access. Free-tier, paid-tier, internal.
So this is the weirdness of the moment. The general public has mostly not interacted with these systems. When they have, it looks like a derpy chatbot. The majority of professionals still see only a modest uplift. And a small sliver of professionals are experiencing the vertigo of the curve going vertical. And it is all happening at the same time.
Thrilled to welcome @spacexai as a Founding Corporate Patron for the Omacom Foundation. That's $1,500,000 in @grok tokens for the maintenance and development of Omarchy. Maybe soon they'll be beamed straight from orbit? Let's go 🚀🌕 https://t.co/PeVkvxHecg
@Perpetualmaniac@PrinceStarkness yep. I'm not a rust guy by any stretch of the imagination but the compiler offers such verbose and precise guidance when errors occur that good harnesses and models just speed through stuff at a crazy pace. continual positive feedback loop.
Indeed.
Imagine telling everyone you are solving problems to help humanity, then someone invents solving machine, and then you're like "actually we don't give a fuck about humanity. These puzzles are entrance tickets into an exclusive club we gatekeep. Please don't solve these puzzles. There is a finite number, and we need them for our game."