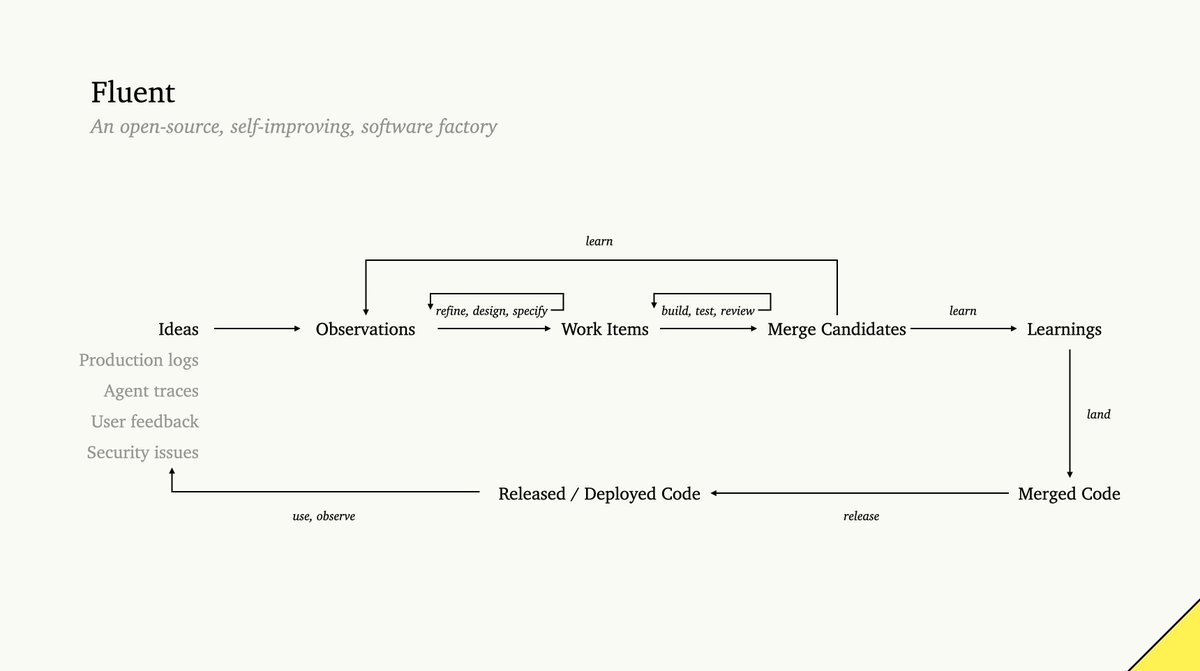
@OpenChurchlabs Work is done in rounds of:
author -> tester -> parallel reviewers ↺
Each reviewer does not see the feedback of other reviewers in that round. But it does see the notes of a previous round.
Here's how my software factory bootstraps:
- Most of Fluent is deterministic Rust code. The Rust command line drives the queues, work lifecycle etc.
- Skills are used to teach coding agents at two levels:
1. How to use Fluent at the level of driving the factory.
2 How to write and review code the way I like it at the level of individual code writers and specialized parallel reviewers.
When you install Fluent via `npx skills add ...` it installs a lightweight shim skill https://t.co/t0DijtVPuq
This shim skill on first request to use Fluent, installs the Fluent rust command line binary and the full Fluent skill
https://t.co/76dPBs8ygr
That full skill then invokes the `fluent init` command to initialize a project to use Fluent.
That command edits your project's AGENTS.md to add some instructions to teach it how to use Fluent as a software factory so Codex, Claude, Pi etc. know that they need to refer to Fluent skill and Fluent command output when fixing bugs and building new features.
https://t.co/NRbX0NrzpI
Here's what gets injected into AGENTS.md:
hi.
curious question - how do you work on the software factory itself ? using Claude/Codex i mean.
your agents.md says "use fluent to build fluent". But for those of us with (subsidized) claude plans...how do we tell Claude to work with fluent ?
something like "dont ever fix a bug directly - delegate it to fluent and fix whatever is necessary"
@jscraik I think the flow will work. The instructions will be in in the skill. When a user asks to uninstall the agent would read the skill and know what command to invoke. After invocation of fluent uninstall the skill, binary, and agents.md section will be gone
@jscraik Great question. Currently there is no `fluent uninstall` command but I think that would be a good way to add this and combine it with an instruction in the skill to invoke that command to uninstall.
@PryvitKyle An issue OAuth maybe creates here is if it requires the list of possible scopes to be named- that again looks a lot like predefined list of roles.
We don’t want that for ABCs
We instead want a general container that can be any list of valid attributes.
Thank you, that context helps.
I would approach as follows:
On OAuth scopes, they work as ABCs as long as we avoid the temptation to give a group of attributes one name. The moment you do that you have a role and that’s a slippery slope to a never ending list of roles.
Keep the attributes truly granular, and let the combination happen in the policy rule when it is computed and applied at access times.
On delegation..
don’t give the subagent the parent agents credential, that’s confused deputy (ideally don’t even have bearer creds)
The other two approaches are both okay.. either a credential scheme that can attenuate OR a round trip to the issuing authority.
Have you hit issues with the above?
I might have to write a bot that anytime someone says anything about agents and granular attenuate-able delegate-able permissions…
replies with: “the answer you’re looking for is attribute-based credentials (ABCs) and attribute-based access control (ABAC)”
I suspect I'm missing a piece of the puzzle here that is specific to the set of technologies you've explored to build this. I'd love to discuss the specifics of it if/when you're able to share them.
In the way I've approached this in the past I've never needed to create a notion of scope. So in your comments above I was puzzled at this statement: "a and b are scopes of resource attributes". Because in my case the policy would be a dynamically computed logical rule over (subject, resource, and sometime environment) attributes.
I must be missing a piece.
@raveeshbhalla Yeh I also don't like that it signals producing a lot of the same thing. But I think the factory metaphor does an okay job of quickly communicating faster speed of production and a quality baseline.
Politely, you're mistaken about balooning of scopes with ABAC.
When using ABAC you don't need predefined scopes at all. Instead, subjects receives attribute based creds that attest facts about the subject. Access is controlled using policies that compute over subject and resource attributes - Allow if sub.a and sub.b are true.
This way, there is no combinatorial explosion.
Attenuated delegation is also simple, a subject can delegate a narrowed subset of its own.
Product managers stay on the left-ish side of this picture, I think.
We while there are engining building, improving, scaling the whole machine.
There are also product level engineers who are discussing architecture, security, and technical tradeoffs with the factory. While product managers are focused on how users experience the product.
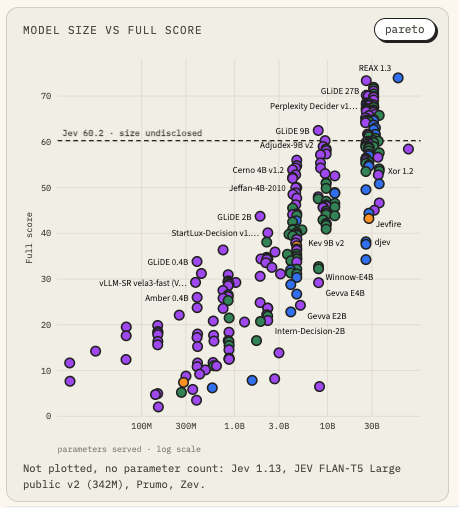
There are 54 models on the decision index that score better than Jev. All of them can likely run on your laptop (less than 31B parameters)
https://t.co/hHWBG0dn0r
Embarrassing story: for a decade I thought my git push to github was protected by my yubikey tap.
Then one day an agent that couldn't get me to tap because I was away noticed that I had the gh command installed and it allows access to a github token that can be used to push via the API 🤦♂️
@dinodaizovi is right of course. I love how good agents can be at helping you harden security boundaries if you focus them on that problem.
@Anunymouze I had the same experience. Memory is a rather simple primitive, most models at the current frontier do a pretty good job navigating it in various shapes - indexed files, or even DBs via a tool.
Fascinating! Continuously learning systems will need continuous evals.
I already feel this with Fluent (my software factory), which continuously learns by writing learnings down as files and providing an index for future agents to lookup. Similar to a memory system.
Weight Space Programming: a glimpse into continual learning.
Agent edited Qwen 0.8B's weights to inject facts about my X profile directly into the model: my handle, bio, GitHub, and what i build. It edited 2% of the network (5 of 488 tensors). No training, no gradients.
Result:
Before, it had never heard of me ("I don't have access to private information…").
After, it tells you who i am, my bio and GitHub, answer project questions it was never trained on. Everything else it knew is untouched.
Reproduce : Link to reproduction repo in comments. Point your agent to the repo and teach model your own facts.