I believe there is no such thing as failure, it's result we get by our belief and actions. Continuously steer our path until we get a result, called as Success
Dubai AI Festival 2026 I'm attending https://t.co/LvhBcTaahO
Dubai AI Festival brings together the organisations, investors and decision-makers driving the future of AI adoption.
#DubaiAIFestival#DAIF#FutureofAI
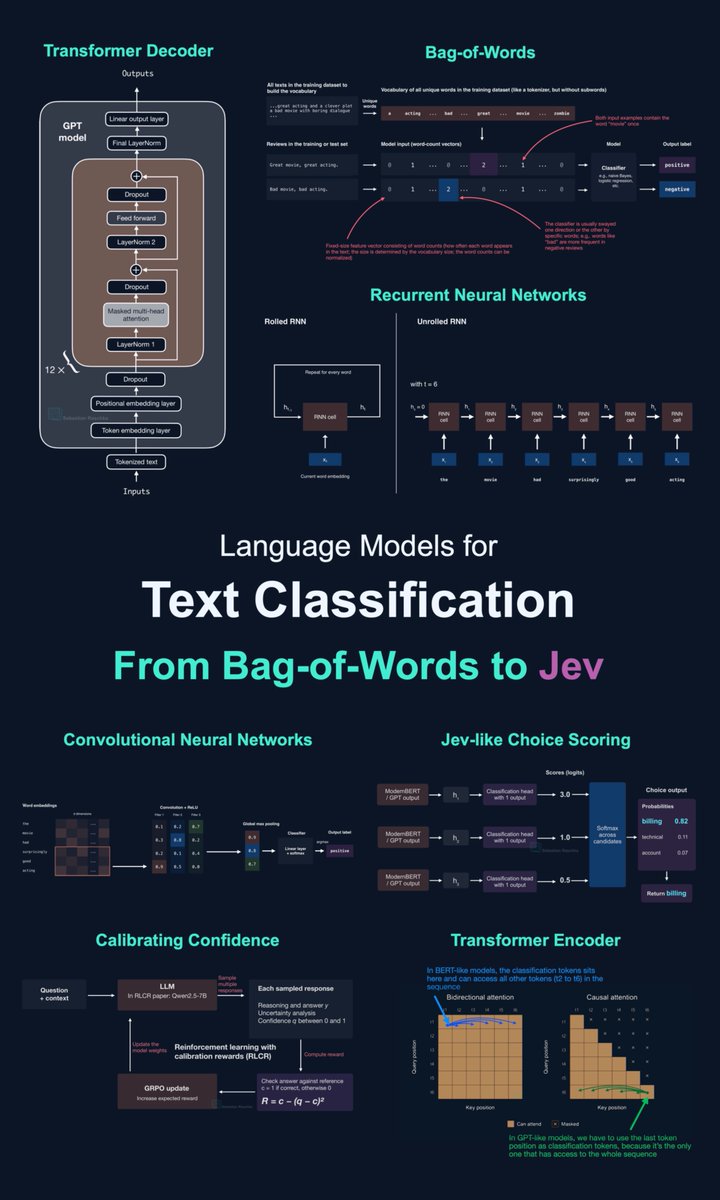
Took a while, but here it is, a mega write-up on language models for text classification and, of course, Jev.
It's basically a visual guide to RNNs, CNNs, transformers, and calibration, with hands-on experiments on accuracy and efficiency.
Andrej Karpathy:
"Prompting is going away.
Delete everything, keep Graph."
In 1 hour he shows how to build Graphs, and why it's the only thing that will be left standing at the end.
Anyone can build an agent, almost no one builds the Graph that runs them.
Watch it, then read the full guide on Graphs below.
KV cache is one of the most important ideas in LLM inference, but it is often explained too casually.
During autoregressive generation, a model produces one token at a time. Without caching, each new decoding step would repeatedly recompute key and value states for tokens the model has already processed. KV caching avoids that redundant work by storing those past K/V tensors and reusing them as the sequence grows.
That sounds simple, but it has consequences across the entire serving stack. The cache grows with sequence length, consumes significant GPU memory, creates memory-bandwidth pressure during decoding, and helps explain why architectures moved from MHA to MQA and GQA, why MLA takes a different compression approach, and why systems such as PagedAttention exist in the first place. It also explains why long context is not free, why prefix caching is a separate optimization, and why KV cache should not be confused with an LLM’s memory.
I put together a technical handbook that works through this from first principles => what exactly gets cached, the tensor shapes, the memory formula, concrete MHA/GQA/MQA calculations, prefill vs. decode, MLA, PagedAttention, prefix reuse, offloading, quantization, eviction, and the common misconceptions around all of it.
The explanations are grounded in the original papers and current framework documentation.
Sharing the handbook here
Excited to attend #SeamlessDXB - a top global digital commerce event with 15k attendees, 500 speakers, exhibitors, and start-ups.
Join me on May 23-24, 2023 - get your free exhibition ticket today!
https://t.co/iWBdf71SpM